Best Design & Creative Startups & Tools

Recently Listed

256 launches
Sort
Emojisilo

Emojisilo solves a narrow but frustrating problem: getting one piece of artwork into the many different sizes and formats that chat platforms and streaming services demand. Streamers, Discord server admins, and Slack communities often end up resizing the same image by hand in design software, and Emojisilo is built for them. It also suits anyone who needs platform-ready emotes without learning a design tool. The most notable thing about the product is how much it handles in a single step. You drop one PNG, JPG, WebP, or GIF, and the tool exports Twitch emote sizes at 112, 56, and 28 pixels, Discord and Slack emojis at 128 by 128, and optional Twitch subscriber badges at 72, 36, and 18 pixels, all bundled into one ZIP file. Square images work best, and the page pads non-square uploads rather than stretching them, which protects the artwork's proportions. Animated GIFs keep their motion with per-platform size targets, which matters for streamers who rely on animated emotes. The privacy model also stands out. According to the site, workshop files are processed on the device and never uploaded to a server, and no account is required. That is a meaningful difference for creators working with unreleased or personal artwork, since the files never leave the browser during resizing. Beyond the resizing workshop, Emojisilo offers a separate section for emoji combinations and Japanese kaomoji, which are text-based faces such as (╯°□°)╯. Users can browse curated, copy-ready shelves, which stay on the device, or type a feeling to generate new combinations with AI. The AI path is different: the prompt is sent through the company's server to a third-party AI provider, so users should expect that text to leave the site. On business model, the site describes the core workshop as free, with no sign-up needed. The AI generation feature includes a limited number of free uses per day, and the site displays advertising. No paid tiers or pricing beyond these details are mentioned.

Graphic-design-tools
A
Alex Brown

Emojisilo solves a narrow but frustrating problem: getting one piece of artwork into the many different sizes and formats that chat platforms and streaming services demand. Streamers, Discord server admins, and Slack communities often end up resizing the same image by hand in design software, and Emojisilo is built for them. It also suits anyone who needs platform-ready emotes without learning a design tool. The most notable thing about the product is how much it handles in a single step. You drop one PNG, JPG, WebP, or GIF, and the tool exports Twitch emote sizes at 112, 56, and 28 pixels, Discord and Slack emojis at 128 by 128, and optional Twitch subscriber badges at 72, 36, and 18 pixels, all bundled into one ZIP file. Square images work best, and the page pads non-square uploads rather than stretching them, which protects the artwork's proportions. Animated GIFs keep their motion with per-platform size targets, which matters for streamers who rely on animated emotes. The privacy model also stands out. According to the site, workshop files are processed on the device and never uploaded to a server, and no account is required. That is a meaningful difference for creators working with unreleased or personal artwork, since the files never leave the browser during resizing. Beyond the resizing workshop, Emojisilo offers a separate section for emoji combinations and Japanese kaomoji, which are text-based faces such as (╯°□°)╯. Users can browse curated, copy-ready shelves, which stay on the device, or type a feeling to generate new combinations with AI. The AI path is different: the prompt is sent through the company's server to a third-party AI provider, so users should expect that text to leave the site. On business model, the site describes the core workshop as free, with no sign-up needed. The AI generation feature includes a limited number of free uses per day, and the site displays advertising. No paid tiers or pricing beyond these details are mentioned.

Emojisilo preview

Key features

  • Multi-Platform Export: Exports one uploaded image into Twitch emote sizes at 112, 56, and 28 pixels, Discord and Slack emojis at 128 by 128, and optional Twitch subscriber badges at 72, 36, and 18 pixels, bundled into one ZIP file.
  • Animated GIF Support: Keeps motion in animated GIFs while resizing them to per-platform size targets.
See full listing
Bicep Heart AI

Creating short videos typically requires equipment, technical skill, or at minimum the willingness to film yourself. Bicep Heart AI removes these barriers by generating personalized clips from a single photograph. The product taps into a social media trend that found particular popularity on TikTok and Reels: a short vertical video where someone flexes one arm and folds their hands into a heart shape beside their head, making the bicep the base of the heart. The trend functions as a lighthearted gesture sent between friends, romantic partners, and family members, often with captions like "I heard you were sad, have a bicep heart." Rather than requiring someone to film and edit themselves, Bicep Heart AI accepts a photo and generates the video automatically. The workflow is straightforward. Users upload a single photograph showing one person facing the camera with shoulders and arms visible, confirm two consent checkboxes, and receive a roughly seven-second video in 9:16 aspect ratio usually within minutes. The output resembles the person in the photo but is not pixel-perfect; hand positioning occasionally appears imperfect. This transparency about technical limitations distinguishes the product from vendors prone to overpromising AI capabilities. The service operates on a strict pay-per-use model with no subscription. Pricing runs 4.99 dollars for a single clip, 9.99 dollars for three clips, or 19.99 dollars for eight clips, structured as one-time purchases. Credits never expire. If a clip fails to generate or times out, the service automatically refunds credits, eliminating friction around failures. Consent protections and privacy guardrails appear built into core product rather than treated as afterthoughts. Users must confirm they have the right to use the photo and that the person pictured is eighteen or older and consents to the use. Uploaded photos are deleted after approximately two days. The product targets a narrow but concrete use case: people who want to participate in a specific social media trend without the filming burden. Whether the trend maintains sufficient longevity to sustain the business remains uncertain, but for the current window of popularity, Bicep Heart AI offers a purposeful tool that addresses genuine friction in how people create and share social videos.

Video-editing
S
Sylas Qiu

Creating short videos typically requires equipment, technical skill, or at minimum the willingness to film yourself. Bicep Heart AI removes these barriers by generating personalized clips from a single photograph. The product taps into a social media trend that found particular popularity on TikTok and Reels: a short vertical video where someone flexes one arm and folds their hands into a heart shape beside their head, making the bicep the base of the heart. The trend functions as a lighthearted gesture sent between friends, romantic partners, and family members, often with captions like "I heard you were sad, have a bicep heart." Rather than requiring someone to film and edit themselves, Bicep Heart AI accepts a photo and generates the video automatically. The workflow is straightforward. Users upload a single photograph showing one person facing the camera with shoulders and arms visible, confirm two consent checkboxes, and receive a roughly seven-second video in 9:16 aspect ratio usually within minutes. The output resembles the person in the photo but is not pixel-perfect; hand positioning occasionally appears imperfect. This transparency about technical limitations distinguishes the product from vendors prone to overpromising AI capabilities. The service operates on a strict pay-per-use model with no subscription. Pricing runs 4.99 dollars for a single clip, 9.99 dollars for three clips, or 19.99 dollars for eight clips, structured as one-time purchases. Credits never expire. If a clip fails to generate or times out, the service automatically refunds credits, eliminating friction around failures. Consent protections and privacy guardrails appear built into core product rather than treated as afterthoughts. Users must confirm they have the right to use the photo and that the person pictured is eighteen or older and consents to the use. Uploaded photos are deleted after approximately two days. The product targets a narrow but concrete use case: people who want to participate in a specific social media trend without the filming burden. Whether the trend maintains sufficient longevity to sustain the business remains uncertain, but for the current window of popularity, Bicep Heart AI offers a purposeful tool that addresses genuine friction in how people create and share social videos.

Bicep Heart AI preview

Key features

  • AI Video Generation: Automatically generates personalized bicep heart videos from a single photograph in seconds
  • Pay-Per-Use Model: One-time purchases starting at $4.99 with no subscription required and credits that never expire
See full listing
SoftCrit

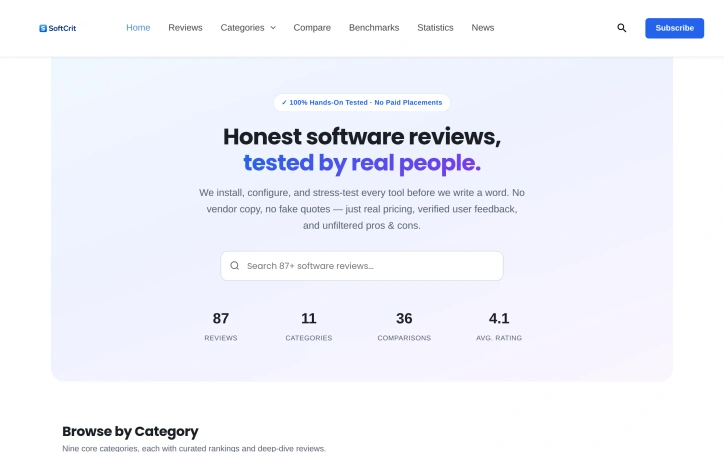
Finding reliable software in a crowded market has become increasingly difficult. Vendor marketing teams saturate review platforms with paid placements and promotional content, leaving buyers drowning in biased recommendations. SoftCrit tackles this problem head-on by providing a curated directory of software reviews built on hands-on testing rather than sponsorship relationships. The platform maintains an intentional commitment to credibility. Every tool undergoes installation, configuration, and stress-testing by the SoftCrit team before any review is published. This methodology eliminates the vendor copy and fake endorsements that plague other review sites. The directory currently catalogs 87 reviews across 11 categories, each focused on specific business needs from email management to AI video generation to financial accounting. The average rating of 4.1 suggests balanced assessment rather than uncritical praise. The breadth of coverage reflects thoughtful category selection. SoftCrit organizes tools by use case rather than generic software type, spanning emerging categories like AI app builders and coaching-specific software alongside established categories like accounting and invoicing. This structure helps buyers find solutions tailored to their specific workflows. The platform also publishes comparative reviews between competing tools, adding another dimension to its utility. What distinguishes SoftCrit from crowded review aggregators is its explicit refusal of paid placements. This creates a straightforward incentive alignment: the platform succeeds by helping readers find genuine matches, not by collecting sponsorship fees. The emphasis on verified user feedback and transparent pricing information addresses legitimate frustrations with typical software review sites, where real costs and authentic user experiences remain obscured behind marketing jargon. The top-rated reviews demonstrate the depth of testing available. Tools like Front for shared inboxes, Sunsama for task planning, and HeyGen for AI video generation each receive detailed analysis reflecting actual use rather than feature-list regurgitation. The platform prioritizes practical decision-making factors that buyers genuinely care about. SoftCrit fills a real gap for buyers seeking unvarnished software evaluation. Whether evaluating personal productivity tools or specialized software for specific professions, the commitment to hands-on testing and transparent pricing offers a counterweight to the sponsored content that dominates other recommendation platforms. For founders, small business owners, and individual contributors making tool decisions, this represents a genuinely useful resource.
User-research
M
Matthew Hu

Finding reliable software in a crowded market has become increasingly difficult. Vendor marketing teams saturate review platforms with paid placements and promotional content, leaving buyers drowning in biased recommendations. SoftCrit tackles this problem head-on by providing a curated directory of software reviews built on hands-on testing rather than sponsorship relationships. The platform maintains an intentional commitment to credibility. Every tool undergoes installation, configuration, and stress-testing by the SoftCrit team before any review is published. This methodology eliminates the vendor copy and fake endorsements that plague other review sites. The directory currently catalogs 87 reviews across 11 categories, each focused on specific business needs from email management to AI video generation to financial accounting. The average rating of 4.1 suggests balanced assessment rather than uncritical praise. The breadth of coverage reflects thoughtful category selection. SoftCrit organizes tools by use case rather than generic software type, spanning emerging categories like AI app builders and coaching-specific software alongside established categories like accounting and invoicing. This structure helps buyers find solutions tailored to their specific workflows. The platform also publishes comparative reviews between competing tools, adding another dimension to its utility. What distinguishes SoftCrit from crowded review aggregators is its explicit refusal of paid placements. This creates a straightforward incentive alignment: the platform succeeds by helping readers find genuine matches, not by collecting sponsorship fees. The emphasis on verified user feedback and transparent pricing information addresses legitimate frustrations with typical software review sites, where real costs and authentic user experiences remain obscured behind marketing jargon. The top-rated reviews demonstrate the depth of testing available. Tools like Front for shared inboxes, Sunsama for task planning, and HeyGen for AI video generation each receive detailed analysis reflecting actual use rather than feature-list regurgitation. The platform prioritizes practical decision-making factors that buyers genuinely care about. SoftCrit fills a real gap for buyers seeking unvarnished software evaluation. Whether evaluating personal productivity tools or specialized software for specific professions, the commitment to hands-on testing and transparent pricing offers a counterweight to the sponsored content that dominates other recommendation platforms. For founders, small business owners, and individual contributors making tool decisions, this represents a genuinely useful resource.

SoftCrit preview

Key features

  • Hands-On Testing: Every tool is installed, configured, and stress-tested by the SoftCrit team before publication.
  • No Paid Placements: The platform explicitly refuses sponsorship relationships to ensure credibility and align incentives with readers.
See full listing
imov.dev

Creative professionals juggling separate AI tools for image, video, and audio generation now have a unified alternative. This platform consolidates text-to-image, image-to-video, text-to-video, and music generation into a single workspace, eliminating context-switching and streamlining the creative workflow. The product targets designers, content creators, product photographers, and anyone producing marketing materials at scale. The workflow emphasizes consistency through features like brand presets that store visual direction and reference-based generation, allowing creators to maintain a cohesive visual identity across multiple outputs. Several features distinguish imov.dev from competitors. The reference-based approach stands out, letting users upload existing product or character imagery and request variations while preserving key details. Brand presets function as reusable direction containers saved locally on the device, providing a lightweight way to inject visual consistency into prompts. The platform also includes specialized workflows for specific use cases—clothing concept exploration, product photography with different backgrounds and lighting, and connected generation steps that calculate total credit costs upfront. Image editing is built directly into the workspace, so creators can request adjustments and review outputs before download rather than exporting to external tools. The integration of music and speech generation alongside visual tools further consolidates the creative process. The pricing structure emphasizes simplicity and control. Rather than monthly subscriptions, imov.dev operates on a pay-as-you-go model with one-time credit purchases ranging from 400 credits for $12.90 to 5,000 credits for $109.90. All plans include full commercial rights, removing friction for agencies, freelancers, and businesses creating client work. The platform supports multiple generation engines, including GPT Image 2, Nano Banana 2, and Kling 3.0 Turbo, giving creators options for different quality and cost tradeoffs. The emphasis on review and refine workflows reflects an iterative design philosophy, acknowledging that AI outputs require human judgment before final use. The main value proposition boils down to efficiency and ownership. By consolidating three content types and removing switching costs, imov.dev positions itself as a focused alternative to maintaining separate subscriptions to individual AI generators. The absence of recurring charges lowers commitment friction for users testing the platform or working on one-off projects.

Ai-generative-media
W
weiyuan zhou

Creative professionals juggling separate AI tools for image, video, and audio generation now have a unified alternative. This platform consolidates text-to-image, image-to-video, text-to-video, and music generation into a single workspace, eliminating context-switching and streamlining the creative workflow. The product targets designers, content creators, product photographers, and anyone producing marketing materials at scale. The workflow emphasizes consistency through features like brand presets that store visual direction and reference-based generation, allowing creators to maintain a cohesive visual identity across multiple outputs. Several features distinguish imov.dev from competitors. The reference-based approach stands out, letting users upload existing product or character imagery and request variations while preserving key details. Brand presets function as reusable direction containers saved locally on the device, providing a lightweight way to inject visual consistency into prompts. The platform also includes specialized workflows for specific use cases—clothing concept exploration, product photography with different backgrounds and lighting, and connected generation steps that calculate total credit costs upfront. Image editing is built directly into the workspace, so creators can request adjustments and review outputs before download rather than exporting to external tools. The integration of music and speech generation alongside visual tools further consolidates the creative process. The pricing structure emphasizes simplicity and control. Rather than monthly subscriptions, imov.dev operates on a pay-as-you-go model with one-time credit purchases ranging from 400 credits for $12.90 to 5,000 credits for $109.90. All plans include full commercial rights, removing friction for agencies, freelancers, and businesses creating client work. The platform supports multiple generation engines, including GPT Image 2, Nano Banana 2, and Kling 3.0 Turbo, giving creators options for different quality and cost tradeoffs. The emphasis on review and refine workflows reflects an iterative design philosophy, acknowledging that AI outputs require human judgment before final use. The main value proposition boils down to efficiency and ownership. By consolidating three content types and removing switching costs, imov.dev positions itself as a focused alternative to maintaining separate subscriptions to individual AI generators. The absence of recurring charges lowers commitment friction for users testing the platform or working on one-off projects.

imov.dev preview

Key features

  • Unified Content Generation: Consolidates text-to-image, image-to-video, text-to-video, and music generation in a single workspace.
  • Reference-Based Generation: Upload existing imagery to request variations while preserving key details.
See full listing
On-Model

Fashion e-commerce teams spend considerable resources on photoshoots to generate diverse product imagery—a costly bottleneck when brands need to showcase garments across multiple models, styles, and colorways. On-Model addresses this directly with AI infrastructure designed to transform static product photography into dynamic, on-model content at scale. The platform handles four core workflows: converting flat-lay images into on-model shots, generating packshot variations, recoloring garments, and swapping models across existing imagery. What distinguishes On-Model from broader AI image tools is its focus on garment preservation. The system maintains every stitch, seam, and pattern detail at pixel level—critical for fashion where product accuracy directly affects customer trust and return rates. The product accommodates high-volume operations through batch processing that handles thousands of images daily and integrates into existing workflows via REST API and TypeScript and Python SDKs. This infrastructure-first approach targets enterprise e-commerce operations rather than one-off content creation. The platform includes a library of 70+ AI models and allows brands to upload custom models to generate digital twins of their brand ambassadors. The customer roster spans 50+ brands across six countries, including both established labels like Pierre Cardin and Zalando alongside athletic and streetwear brands. This breadth demonstrates the technology works across different garment types and brand positioning. The business model remains undisclosed from the marketing materials. A free trial tier and demo booking option are available, but specific pricing is not detailed. This approach typically indicates usage-based billing or custom enterprise pricing, common for API-first platforms with variable throughput requirements. On-Model directly addresses a real pain point in fashion e-commerce: the gap between manual photoshoots and the demand for diverse visual content. Whether the garment preservation delivers on its promise and whether pricing aligns with cost savings versus traditional photography will determine its staying power in a crowded AI image space.

Ai-generative-media
D
Davide Righini

Fashion e-commerce teams spend considerable resources on photoshoots to generate diverse product imagery—a costly bottleneck when brands need to showcase garments across multiple models, styles, and colorways. On-Model addresses this directly with AI infrastructure designed to transform static product photography into dynamic, on-model content at scale. The platform handles four core workflows: converting flat-lay images into on-model shots, generating packshot variations, recoloring garments, and swapping models across existing imagery. What distinguishes On-Model from broader AI image tools is its focus on garment preservation. The system maintains every stitch, seam, and pattern detail at pixel level—critical for fashion where product accuracy directly affects customer trust and return rates. The product accommodates high-volume operations through batch processing that handles thousands of images daily and integrates into existing workflows via REST API and TypeScript and Python SDKs. This infrastructure-first approach targets enterprise e-commerce operations rather than one-off content creation. The platform includes a library of 70+ AI models and allows brands to upload custom models to generate digital twins of their brand ambassadors. The customer roster spans 50+ brands across six countries, including both established labels like Pierre Cardin and Zalando alongside athletic and streetwear brands. This breadth demonstrates the technology works across different garment types and brand positioning. The business model remains undisclosed from the marketing materials. A free trial tier and demo booking option are available, but specific pricing is not detailed. This approach typically indicates usage-based billing or custom enterprise pricing, common for API-first platforms with variable throughput requirements. On-Model directly addresses a real pain point in fashion e-commerce: the gap between manual photoshoots and the demand for diverse visual content. Whether the garment preservation delivers on its promise and whether pricing aligns with cost savings versus traditional photography will determine its staying power in a crowded AI image space.

On-Model preview

Key features

  • Flat-Lay Conversion: Automatically transforms static product photography into on-model shots.
  • Garment Preservation: Maintains every stitch, seam, and pattern detail at pixel level.
See full listing
B

For product-based sellers overwhelmed by the friction of asset creation, a streamlined alternative has emerged. BlueVeta addresses a genuine pain point: the gap between having a product and having marketing collateral across every sales channel. Rather than juggling agencies, hiring photographers, waiting for designers, or manually prompted AI tools, the platform promises to compress months of production into minutes. The core premise is straightforward but ambitious. Users upload a single product photo—even a casual phone shot will do—and receive 25 or more finished assets: professional studio renderings, lifestyle compositions, short-form video, and platform-specific copy ready to deploy across Instagram, TikTok, Amazon, email, and 16 additional channels. The output spans 10 languages, addressing multi-regional sellers directly. No additional editing is required; assets ship pre-sized for their intended destination. What distinguishes the offering is its refusal of the subscription model. Rather than locking users into recurring charges, BlueVeta prices individual packs at $9.99, with bundles available at better rates. The business model eliminates a major adoption barrier for one-off campaigns or small sellers testing the waters. A free demo dashboard lets prospects explore real output from actual products before committing. The product positions itself deliberately against two alternatives: the traditional agency workflow (expensive, slow, relationship-dependent) and the current chaos of single-task AI tools (fragmented, inconsistent, lacking continuity). To that end, BlueVeta introduces brand memory—a learning mechanism that absorbs information from user uploads, explicit feedback, edits, and even website content. The system claims to progressively internalize voice, visual style, and audience preferences, so repeated use improves output relevance and brand coherence over time. The founder's framing emphasizes simplicity: one upload triggers 18 automated steps behind the scenes, handling everything from image generation to copywriting to platform adaptation. The service covers diverse product categories—from food and beauty to electronics and home goods—suggesting broad applicability. The core risk is inherent to the category: AI-generated lifestyle photography and copy carry consistency and authenticity questions that remain unresolved across the industry. Whether algorithmically produced scenes and messaging satisfy demanding sellers, particularly those competing on brand differentiation rather than price, remains an open question. Nevertheless, the product's combination of speed, accessibility, and pay-per-use pricing positions it squarely where small and mid-sized brands currently spend their time and money.

Ai-generative-media
T
Tomer Bar-Meir (Tom)

For product-based sellers overwhelmed by the friction of asset creation, a streamlined alternative has emerged. BlueVeta addresses a genuine pain point: the gap between having a product and having marketing collateral across every sales channel. Rather than juggling agencies, hiring photographers, waiting for designers, or manually prompted AI tools, the platform promises to compress months of production into minutes. The core premise is straightforward but ambitious. Users upload a single product photo—even a casual phone shot will do—and receive 25 or more finished assets: professional studio renderings, lifestyle compositions, short-form video, and platform-specific copy ready to deploy across Instagram, TikTok, Amazon, email, and 16 additional channels. The output spans 10 languages, addressing multi-regional sellers directly. No additional editing is required; assets ship pre-sized for their intended destination. What distinguishes the offering is its refusal of the subscription model. Rather than locking users into recurring charges, BlueVeta prices individual packs at $9.99, with bundles available at better rates. The business model eliminates a major adoption barrier for one-off campaigns or small sellers testing the waters. A free demo dashboard lets prospects explore real output from actual products before committing. The product positions itself deliberately against two alternatives: the traditional agency workflow (expensive, slow, relationship-dependent) and the current chaos of single-task AI tools (fragmented, inconsistent, lacking continuity). To that end, BlueVeta introduces brand memory—a learning mechanism that absorbs information from user uploads, explicit feedback, edits, and even website content. The system claims to progressively internalize voice, visual style, and audience preferences, so repeated use improves output relevance and brand coherence over time. The founder's framing emphasizes simplicity: one upload triggers 18 automated steps behind the scenes, handling everything from image generation to copywriting to platform adaptation. The service covers diverse product categories—from food and beauty to electronics and home goods—suggesting broad applicability. The core risk is inherent to the category: AI-generated lifestyle photography and copy carry consistency and authenticity questions that remain unresolved across the industry. Whether algorithmically produced scenes and messaging satisfy demanding sellers, particularly those competing on brand differentiation rather than price, remains an open question. Nevertheless, the product's combination of speed, accessibility, and pay-per-use pricing positions it squarely where small and mid-sized brands currently spend their time and money.

BlueVeta preview
B

Key features

  • Bulk Asset Generation: Converts a single product photo into 25+ finished marketing assets.
  • Multi-Channel Optimization: Pre-sized assets ready for Instagram, TikTok, Amazon, email, and 18+ other platforms.
See full listing
U

Creators and small brands managing visual content face a fragmented workflow: generate images on one platform, edit them on another, then find a separate tool for video creation. Uyo consolidates these tasks into a single browser workspace designed specifically for creators who need fast turnarounds without compromising on customization. The platform generates images from text prompts, then lets users refine them through integrated editing tools including upscaling, background removal, and reference photo adjustments. Users can also transform static images into short videos, either by providing a new text description or by letting the AI animate existing visuals. This flexibility lets creators iterate quickly, moving from concept to finished asset without switching applications. What distinguishes Uyo is its focus on transparency and control. The interface displays estimated credit costs before generation, letting users make informed decisions about their spending. The workspace automatically saves all tasks and results in a personal "My Creations" library, eliminating the friction of hunting through generated files or losing track of which prompt produced which output. This organizational approach directly addresses the chaos that often accompanies bulk content creation. The platform curates a collection of reference images and videos across categories like portraits, landscapes, illustrated characters, and everyday scenes. Each reference includes the prompt used to create it, allowing users to study techniques and adapt them for their own projects. This gallery serves as both inspiration and a learning resource, especially valuable for creators without formal training in AI prompt engineering. Uyo supports both English and Chinese interfaces, signaling an intention to serve international markets. Access requires an account and credits purchased in one-time packs, positioning the tool as a consumption-based service rather than a subscription model. For small businesses and independent creators, this approach offers flexibility in budget allocation across multiple platforms. The combination of generation, editing, and video creation in one cohesive environment—paired with deliberate design choices around cost visibility and result organization—positions Uyo for creators tired of patchwork workflows. Whether users prioritize speed or fine-grained control, the platform attempts to accommodate both.

Ai-generative-media
W
weiyuan zhou

Creators and small brands managing visual content face a fragmented workflow: generate images on one platform, edit them on another, then find a separate tool for video creation. Uyo consolidates these tasks into a single browser workspace designed specifically for creators who need fast turnarounds without compromising on customization. The platform generates images from text prompts, then lets users refine them through integrated editing tools including upscaling, background removal, and reference photo adjustments. Users can also transform static images into short videos, either by providing a new text description or by letting the AI animate existing visuals. This flexibility lets creators iterate quickly, moving from concept to finished asset without switching applications. What distinguishes Uyo is its focus on transparency and control. The interface displays estimated credit costs before generation, letting users make informed decisions about their spending. The workspace automatically saves all tasks and results in a personal "My Creations" library, eliminating the friction of hunting through generated files or losing track of which prompt produced which output. This organizational approach directly addresses the chaos that often accompanies bulk content creation. The platform curates a collection of reference images and videos across categories like portraits, landscapes, illustrated characters, and everyday scenes. Each reference includes the prompt used to create it, allowing users to study techniques and adapt them for their own projects. This gallery serves as both inspiration and a learning resource, especially valuable for creators without formal training in AI prompt engineering. Uyo supports both English and Chinese interfaces, signaling an intention to serve international markets. Access requires an account and credits purchased in one-time packs, positioning the tool as a consumption-based service rather than a subscription model. For small businesses and independent creators, this approach offers flexibility in budget allocation across multiple platforms. The combination of generation, editing, and video creation in one cohesive environment—paired with deliberate design choices around cost visibility and result organization—positions Uyo for creators tired of patchwork workflows. Whether users prioritize speed or fine-grained control, the platform attempts to accommodate both.

Uyo preview
U

Key features

  • Image Generation: Creates images from text prompts with customization options
  • Image Editing Tools: Includes upscaling, background removal, and reference photo adjustments
See full listing
LumoKeep – Smart Photo Cleaner & Video Compressor for iPhone

Smartphone photo libraries have become digital junk drawers. For iPhone users drowning in duplicates, screenshots, and forgotten moments, finding a cleanup solution that doesn't feel aggressive—or require surrendering control—is genuinely difficult. LumoKeep addresses this problem head-on with a thoughtfully designed photo management app that treats deliberate review as a feature, not an afterthought. Rather than offering a single "clean all" button, the app guides users through their camera roll one photo at a time using a swipe interface. This Tinder-like interaction model makes the cleanup process feel less like data destruction and more like curation. Users mark photos for deletion as they go, then review their selections before anything is actually removed from the library—a critical safeguard against accidental loss. The app distinguishes itself through several practical capabilities. A similar-photo detection tool identifies and groups near-duplicate shots, helping users quickly decide which variations to keep. A dedicated screenshots and large-files finder surfaces the storage hogs users often forget about. Built-in compression tools for photos and videos let users reduce file sizes before deletion, with savings estimates shown beforehand. Beyond cleanup, LumoKeep organizes content by albums, favorites, screenshots, videos, and a timeline view, positioning itself as both a cleaner and a rediscovery tool for older photos. What particularly stands out is the privacy architecture. LumoKeep processes everything on-device without requiring an account or sending data elsewhere. This isn't a trendy privacy claim—it's baked into the product design. For users concerned about data practices, this approach eliminates a major friction point with competitor apps. The business model reflects a thoughtful balance. Core cleanup features are available free, with ad-free functionality as the default experience. Some advanced tools sit behind a Pro tier, though specific pricing remains undisclosed on the public site. This freemium structure allows users to test the core workflow before committing to premium features. LumoKeep targets a specific user: the iPhone owner whose photo library has spiraled into chaos, who values control over automation, and who would prefer not to see ads while doing so. For that audience, the swipe-based review system paired with local processing and deletion safeguards represents a genuinely refreshing alternative to aggressive, cloud-dependent competitors. The app doesn't oversell what it does, and that restraint itself feels like an asset in an overcrowded market.

Mobile-editing-apps
G
gao xiao

Smartphone photo libraries have become digital junk drawers. For iPhone users drowning in duplicates, screenshots, and forgotten moments, finding a cleanup solution that doesn't feel aggressive—or require surrendering control—is genuinely difficult. LumoKeep addresses this problem head-on with a thoughtfully designed photo management app that treats deliberate review as a feature, not an afterthought. Rather than offering a single "clean all" button, the app guides users through their camera roll one photo at a time using a swipe interface. This Tinder-like interaction model makes the cleanup process feel less like data destruction and more like curation. Users mark photos for deletion as they go, then review their selections before anything is actually removed from the library—a critical safeguard against accidental loss. The app distinguishes itself through several practical capabilities. A similar-photo detection tool identifies and groups near-duplicate shots, helping users quickly decide which variations to keep. A dedicated screenshots and large-files finder surfaces the storage hogs users often forget about. Built-in compression tools for photos and videos let users reduce file sizes before deletion, with savings estimates shown beforehand. Beyond cleanup, LumoKeep organizes content by albums, favorites, screenshots, videos, and a timeline view, positioning itself as both a cleaner and a rediscovery tool for older photos. What particularly stands out is the privacy architecture. LumoKeep processes everything on-device without requiring an account or sending data elsewhere. This isn't a trendy privacy claim—it's baked into the product design. For users concerned about data practices, this approach eliminates a major friction point with competitor apps. The business model reflects a thoughtful balance. Core cleanup features are available free, with ad-free functionality as the default experience. Some advanced tools sit behind a Pro tier, though specific pricing remains undisclosed on the public site. This freemium structure allows users to test the core workflow before committing to premium features. LumoKeep targets a specific user: the iPhone owner whose photo library has spiraled into chaos, who values control over automation, and who would prefer not to see ads while doing so. For that audience, the swipe-based review system paired with local processing and deletion safeguards represents a genuinely refreshing alternative to aggressive, cloud-dependent competitors. The app doesn't oversell what it does, and that restraint itself feels like an asset in an overcrowded market.

LumoKeep – Smart Photo Cleaner & Video Compressor for iPhone preview

Key features

  • Swipe Interface: Tinder-like interaction model for reviewing and marking photos for deletion one at a time.
  • Duplicate Detection: Identifies and groups near-duplicate shots to help users decide which variations to keep.
See full listing
A

Creating shareable videos typically requires equipment, technical skill, and considerable time. This generator eliminates those barriers by transforming two portrait photos into a 15-second rap video with an original verse and beat, ready for vertical social platforms like TikTok and Instagram Reels. The product targets adults seeking quick, humorous content to share with friends or partners. The appeal lies in its simplicity: users upload clear photos, select a themed stage, and optionally add names or details about the occasion. The AI then generates lyrics tailored to that context, builds an original beat, and renders the complete video. The process takes minutes and requires no recording equipment, microphone, or editing software. Several features distinguish this from generic video creation tools. The template library focuses on social moments with built-in contexts like birthday celebrations, roasts, or holiday variations, which influences the lyrical direction. Users control whether the output is a solo performance, a duo with a second person or pet, or a meme remake format. The AI generates both music and vocals for each video rather than licensing or remixing existing tracks. The business model emphasizes accessibility and low commitment. A single video costs 10 credits; starter packs begin at 6.99 dollars with no ongoing subscription or credit expiration. This removes friction for casual users testing the product without long-term financial obligation. The pay-per-video approach means creators only pay when generating content, not for potential videos they never make. The platform enforces adult-only usage with consent requirements, specifying that only adults can appear in videos and that all participants must agree. Photos are deleted after seven days, addressing privacy concerns from users uploading portraits. The 10 megabyte file size limit accommodates typical smartphone photos without demanding high-resolution originals. The vertical 15-second format aligns precisely with mobile-first social consumption, where such videos generate engagement through humor and novelty rather than production quality. For creators without video production experience or budget, this represents a significant simplification of a traditionally technical process. The execution hinges on AI capabilities in lyric generation, beat production, and facial animation quality, elements not detailed in the current materials but central to user satisfaction.

Ai-generative-media
J
Jason Wei

Creating shareable videos typically requires equipment, technical skill, and considerable time. This generator eliminates those barriers by transforming two portrait photos into a 15-second rap video with an original verse and beat, ready for vertical social platforms like TikTok and Instagram Reels. The product targets adults seeking quick, humorous content to share with friends or partners. The appeal lies in its simplicity: users upload clear photos, select a themed stage, and optionally add names or details about the occasion. The AI then generates lyrics tailored to that context, builds an original beat, and renders the complete video. The process takes minutes and requires no recording equipment, microphone, or editing software. Several features distinguish this from generic video creation tools. The template library focuses on social moments with built-in contexts like birthday celebrations, roasts, or holiday variations, which influences the lyrical direction. Users control whether the output is a solo performance, a duo with a second person or pet, or a meme remake format. The AI generates both music and vocals for each video rather than licensing or remixing existing tracks. The business model emphasizes accessibility and low commitment. A single video costs 10 credits; starter packs begin at 6.99 dollars with no ongoing subscription or credit expiration. This removes friction for casual users testing the product without long-term financial obligation. The pay-per-video approach means creators only pay when generating content, not for potential videos they never make. The platform enforces adult-only usage with consent requirements, specifying that only adults can appear in videos and that all participants must agree. Photos are deleted after seven days, addressing privacy concerns from users uploading portraits. The 10 megabyte file size limit accommodates typical smartphone photos without demanding high-resolution originals. The vertical 15-second format aligns precisely with mobile-first social consumption, where such videos generate engagement through humor and novelty rather than production quality. For creators without video production experience or budget, this represents a significant simplification of a traditionally technical process. The execution hinges on AI capabilities in lyric generation, beat production, and facial animation quality, elements not detailed in the current materials but central to user satisfaction.

AI Rap Generators preview
A

Key features

  • Photo to Rap Video: transforms portrait photos into 15-second rap videos with AI-generated verses and beats
  • Original Beat Generation: AI generates both music and vocals rather than licensing or remixing existing tracks
See full listing
Rapvora

Creating short-form video content for social media typically requires video editing skills, curated music libraries, and significant time investment. This gap between creator ambition and technical barriers is precisely where an AI-powered rap video generator operates. The platform targets content creators, music enthusiasts, and social media users seeking to produce hip-hop videos quickly without professional editing experience or deep music production knowledge. The core offering is direct: upload one to three portrait photos, select a template or enter a custom topic, and receive a finished music video in seconds. The platform supports three distinct modes scaled to photo count, enabling solo performances, duo battle scenarios, and crew setups. This structure directly addresses creator demand for group content, which dominates platforms like TikTok and Instagram Reels where ensemble videos frequently outperform solo material. Templated categories for birthdays, roasts, flexing, and business promotion save users from concept development time. Technical implementation separates this from simpler face-swapping tools. The platform uses beat-synchronized animation, realistic head movements, and dynamic camera work timed to rhyme flows. Audio generation includes original hip-hop instrumentals with drop sequences engineered for rhythmic editing. Output flexibility spans multiple aspect ratios and resolutions up to 4K, accommodating varied platform distribution strategies. Video lengths range from five to thirty seconds depending on template and model selection, matching algorithmic preferences across short-form platforms. The testimonials showcase creators achieving significant view counts through group performances and platform-native formatting, though attribution depends heavily on existing audience size and broader content strategy. The featured feedback highlights the platform's ability to produce realistic ensemble performances and optimized social media formatting as genuine technical strengths. The business model relies on a credit system rather than pure subscription access. Users receive starter credits upon signup, with flexible monthly plans and non-expiring credit packs available for purchase. The platform includes failure protection through automatic credit refunds when tasks timeout or trigger safety filters, reducing friction on unsuccessful attempts. The platform successfully removes technical barriers to rapid hip-hop video production, addressing a legitimate gap in creator tooling. Durability depends on execution depth and whether this specialized capability withstands broader competition from increasingly sophisticated generative video platforms entering the market.

Ai-generative-media
W
win one

Creating short-form video content for social media typically requires video editing skills, curated music libraries, and significant time investment. This gap between creator ambition and technical barriers is precisely where an AI-powered rap video generator operates. The platform targets content creators, music enthusiasts, and social media users seeking to produce hip-hop videos quickly without professional editing experience or deep music production knowledge. The core offering is direct: upload one to three portrait photos, select a template or enter a custom topic, and receive a finished music video in seconds. The platform supports three distinct modes scaled to photo count, enabling solo performances, duo battle scenarios, and crew setups. This structure directly addresses creator demand for group content, which dominates platforms like TikTok and Instagram Reels where ensemble videos frequently outperform solo material. Templated categories for birthdays, roasts, flexing, and business promotion save users from concept development time. Technical implementation separates this from simpler face-swapping tools. The platform uses beat-synchronized animation, realistic head movements, and dynamic camera work timed to rhyme flows. Audio generation includes original hip-hop instrumentals with drop sequences engineered for rhythmic editing. Output flexibility spans multiple aspect ratios and resolutions up to 4K, accommodating varied platform distribution strategies. Video lengths range from five to thirty seconds depending on template and model selection, matching algorithmic preferences across short-form platforms. The testimonials showcase creators achieving significant view counts through group performances and platform-native formatting, though attribution depends heavily on existing audience size and broader content strategy. The featured feedback highlights the platform's ability to produce realistic ensemble performances and optimized social media formatting as genuine technical strengths. The business model relies on a credit system rather than pure subscription access. Users receive starter credits upon signup, with flexible monthly plans and non-expiring credit packs available for purchase. The platform includes failure protection through automatic credit refunds when tasks timeout or trigger safety filters, reducing friction on unsuccessful attempts. The platform successfully removes technical barriers to rapid hip-hop video production, addressing a legitimate gap in creator tooling. Durability depends on execution depth and whether this specialized capability withstands broader competition from increasingly sophisticated generative video platforms entering the market.

Rapvora preview

Key features

  • Photo-to-Video: Upload one to three portrait photos and receive a finished music video in seconds.
  • Multiple Performance Modes: Supports solo performances, duo battles, and crew setups based on photo count.
See full listing
Adobe Alternatives

Designers switching from Adobe or exploring open-source creative tools face a discovery problem: dozens of projects exist, but finding ones that genuinely match Adobe workflows is time-consuming. This independent directory cuts through that noise by curating ArtCraft creative applications and related open-source tools, organizing them by the familiar Adobe product categories they replace. The directory concentrates on five core Adobe replacements: PhotoCraft for image editing, VectorCraft for illustration, LightCraft for photography workflows and RAW development, PdfCraft for PDF management, and EffectCraft for motion graphics. Each entry includes the tool's primary workflow type, supported platforms, current development status, and direct links to official projects. This clarity about project maturity matters when evaluating alpha and in-development software for production use. What distinguishes this approach is transparency about dependencies. Rather than selling these tools as finished products, the directory emphasizes checking development status and documentation before committing to production workflows. It includes WordCraft as a bonus for document handling but explicitly notes it is not an Adobe alternative, and a separate guide addresses SolidCraft for parametric 3D CAD work. This honesty about scope strengthens credibility. Cross-platform availability is consistent across the directory, with all tools supporting Windows, macOS, and Linux, and most offering web-based access. This reduces friction for teams with mixed systems and suggests that open-source alternatives are increasingly viable for real work, not just experimentation. The interface prioritizes usability: no account creation required, free browsing, and a comparison table that helps users shortlist candidates before testing their own files. The directory maintains editorial independence by avoiding affiliation with either Adobe or the ArtCraft project it curates. This positioning strengthens credibility when recommending tools that are truly transitional options rather than mature replacements. For anyone seeking to reduce Creative Cloud subscriptions or explore the open-source creative toolchain, this directory functions as a practical starting point rather than a definitive verdict. It identifies the most viable options for each workflow, bundles critical metadata, and sets expectations about stability appropriately.

Design-resources
Z
Zheng Li

Designers switching from Adobe or exploring open-source creative tools face a discovery problem: dozens of projects exist, but finding ones that genuinely match Adobe workflows is time-consuming. This independent directory cuts through that noise by curating ArtCraft creative applications and related open-source tools, organizing them by the familiar Adobe product categories they replace. The directory concentrates on five core Adobe replacements: PhotoCraft for image editing, VectorCraft for illustration, LightCraft for photography workflows and RAW development, PdfCraft for PDF management, and EffectCraft for motion graphics. Each entry includes the tool's primary workflow type, supported platforms, current development status, and direct links to official projects. This clarity about project maturity matters when evaluating alpha and in-development software for production use. What distinguishes this approach is transparency about dependencies. Rather than selling these tools as finished products, the directory emphasizes checking development status and documentation before committing to production workflows. It includes WordCraft as a bonus for document handling but explicitly notes it is not an Adobe alternative, and a separate guide addresses SolidCraft for parametric 3D CAD work. This honesty about scope strengthens credibility. Cross-platform availability is consistent across the directory, with all tools supporting Windows, macOS, and Linux, and most offering web-based access. This reduces friction for teams with mixed systems and suggests that open-source alternatives are increasingly viable for real work, not just experimentation. The interface prioritizes usability: no account creation required, free browsing, and a comparison table that helps users shortlist candidates before testing their own files. The directory maintains editorial independence by avoiding affiliation with either Adobe or the ArtCraft project it curates. This positioning strengthens credibility when recommending tools that are truly transitional options rather than mature replacements. For anyone seeking to reduce Creative Cloud subscriptions or explore the open-source creative toolchain, this directory functions as a practical starting point rather than a definitive verdict. It identifies the most viable options for each workflow, bundles critical metadata, and sets expectations about stability appropriately.

Adobe Alternatives preview

Key features

  • Curated Directory: Organizes open-source creative tools by Adobe product categories they replace.
  • Development Status Tracking: Displays each tool's workflow type, supported platforms, and current maturity level.
See full listing
C

Designers often complain that developers write good documentation, and developers often complain that getting that documentation into a shareable visual format requires jumping between tools. Cardify bridges this gap by converting Markdown directly into styled visual cards without leaving the browser. The product targets knowledge workers who live in Markdown—developers writing READMEs, researchers compiling notes, product teams documenting processes—and need to present that content visually without learning design software. Instead of copying content into a design tool and recreating the layout, users paste Markdown into Cardify's editor and watch a polished card render in real time on the adjacent preview pane. What distinguishes Cardify from a simple Markdown-to-image converter is the breadth of design flexibility baked in. The tool offers over 30 pre-built themes that can be browsed side by side, with adjustable card dimensions, customizable fonts either from a built-in library or via upload, and the ability to add images. The full Markdown specification is supported—headings, lists, code blocks, inline links—so users aren't restricted to plain text. A searchable image library and thousands of emoji options let creators add visual weight without hunting elsewhere. The workflow supports batch operations. Users who need to export an entire set of cards can do so at once rather than one-by-one, with output available in PNG, SVG, and PDF formats. This is particularly valuable for teams generating marketing materials, knowledge bases, or educational content where consistency and scale matter. Cardify runs entirely in the browser on both desktop and mobile devices with no installation required, lowering the barrier to adoption. The company employs a freemium model: creating and previewing cards is free, while exporting to final formats requires a paid plan. This strikes a reasonable balance—users can experiment with the tool and its extensive theme library without financial commitment, and those who find value can unlock distribution. The product occupies a specific niche but a real one: the friction between how technical people naturally write and how that content needs to be shared. By handling that translation automatically within a single tool, Cardify removes a small but persistent annoyance from the workflow of people who spend their time in text editors and Markdown files.

Graphic-design-tools
C
Chip Tong

Designers often complain that developers write good documentation, and developers often complain that getting that documentation into a shareable visual format requires jumping between tools. Cardify bridges this gap by converting Markdown directly into styled visual cards without leaving the browser. The product targets knowledge workers who live in Markdown—developers writing READMEs, researchers compiling notes, product teams documenting processes—and need to present that content visually without learning design software. Instead of copying content into a design tool and recreating the layout, users paste Markdown into Cardify's editor and watch a polished card render in real time on the adjacent preview pane. What distinguishes Cardify from a simple Markdown-to-image converter is the breadth of design flexibility baked in. The tool offers over 30 pre-built themes that can be browsed side by side, with adjustable card dimensions, customizable fonts either from a built-in library or via upload, and the ability to add images. The full Markdown specification is supported—headings, lists, code blocks, inline links—so users aren't restricted to plain text. A searchable image library and thousands of emoji options let creators add visual weight without hunting elsewhere. The workflow supports batch operations. Users who need to export an entire set of cards can do so at once rather than one-by-one, with output available in PNG, SVG, and PDF formats. This is particularly valuable for teams generating marketing materials, knowledge bases, or educational content where consistency and scale matter. Cardify runs entirely in the browser on both desktop and mobile devices with no installation required, lowering the barrier to adoption. The company employs a freemium model: creating and previewing cards is free, while exporting to final formats requires a paid plan. This strikes a reasonable balance—users can experiment with the tool and its extensive theme library without financial commitment, and those who find value can unlock distribution. The product occupies a specific niche but a real one: the friction between how technical people naturally write and how that content needs to be shared. By handling that translation automatically within a single tool, Cardify removes a small but persistent annoyance from the workflow of people who spend their time in text editors and Markdown files.

Cardify preview
C

Key features

  • Markdown to Cards: Converts Markdown directly into styled visual cards in the browser without switching tools
  • 30+ Pre-built Themes: Browse and apply over 30 design themes side by side with customizable dimensions
See full listing
CleanNoise

Audio and video quality matters, especially when your recording is full of unwanted noise. This tool addresses a real frustration for creators and professionals: extracting clear voice from messy real-world recordings without expensive software or technical expertise. The product targets a broad audience. Podcasters can strip room tone and background hum between guests. Video creators can clean wind and traffic noise captured on location. Remote workers can salvage muddy Zoom recordings. Musicians and students benefit too, whether reducing hiss from home demos or making lecture recordings transcribable. What distinguishes CleanNoise is its approach to discovery and trust. Rather than requiring sign-up or payment to test the service, users upload a file and instantly hear a full-quality 30-second preview. This removes friction and lets users judge the AI's performance before committing money. The actual processing uses an adaptive AI model rather than fixed filters, meaning it learns from the content and preserves natural voice quality—a claim tested across different recording scenarios in the tool's demo. The interface lives up to the simplicity promise. Users drag and drop files, wait for analysis, and immediately hear results. The tool accepts common formats including MP3, WAV, M4A, and video files up to an hour long. Audio output can be delivered in multiple formats. Video returns with the cleaned audio track intact. A privacy feature auto-deletes uploaded files within 48 hours, addressing concerns many users have about cloud processing of potentially sensitive recordings. The pricing model is straightforward and removes purchase friction. Single files cost $0.99 with no account required and no sign-up trap. Users pay only for processed files they download. A Pro tier exists for heavier users, offering 15 hours of monthly processing, batch operations, and processing history. The product identifies a specific use case—voice clarity in noisy environments—and solves it without unnecessary complexity. By proving value through a free preview and charging modestly per file, CleanNoise makes professional-grade audio cleanup accessible to creators without technical skills or large budgets. The combination of simple execution, transparent pricing, and privacy-conscious design positions it as a practical tool rather than complexity for its own sake.

Podcasting-tools
I
IdleCat

Audio and video quality matters, especially when your recording is full of unwanted noise. This tool addresses a real frustration for creators and professionals: extracting clear voice from messy real-world recordings without expensive software or technical expertise. The product targets a broad audience. Podcasters can strip room tone and background hum between guests. Video creators can clean wind and traffic noise captured on location. Remote workers can salvage muddy Zoom recordings. Musicians and students benefit too, whether reducing hiss from home demos or making lecture recordings transcribable. What distinguishes CleanNoise is its approach to discovery and trust. Rather than requiring sign-up or payment to test the service, users upload a file and instantly hear a full-quality 30-second preview. This removes friction and lets users judge the AI's performance before committing money. The actual processing uses an adaptive AI model rather than fixed filters, meaning it learns from the content and preserves natural voice quality—a claim tested across different recording scenarios in the tool's demo. The interface lives up to the simplicity promise. Users drag and drop files, wait for analysis, and immediately hear results. The tool accepts common formats including MP3, WAV, M4A, and video files up to an hour long. Audio output can be delivered in multiple formats. Video returns with the cleaned audio track intact. A privacy feature auto-deletes uploaded files within 48 hours, addressing concerns many users have about cloud processing of potentially sensitive recordings. The pricing model is straightforward and removes purchase friction. Single files cost $0.99 with no account required and no sign-up trap. Users pay only for processed files they download. A Pro tier exists for heavier users, offering 15 hours of monthly processing, batch operations, and processing history. The product identifies a specific use case—voice clarity in noisy environments—and solves it without unnecessary complexity. By proving value through a free preview and charging modestly per file, CleanNoise makes professional-grade audio cleanup accessible to creators without technical skills or large budgets. The combination of simple execution, transparent pricing, and privacy-conscious design positions it as a practical tool rather than complexity for its own sake.

CleanNoise preview

Key features

  • Free Preview Without Sign-up: Instantly hear a full-quality 30-second preview of processed audio by uploading a file, no account needed.
  • Adaptive AI Model: Uses an adaptive AI model that learns from content and preserves natural voice quality rather than relying on fixed filters.
See full listing
Tiny Desk AI

Meme culture thrives on participation and remixing, but most viral formats require technical editing skills or specialized tools. This new service strips away that friction by automating the core mechanics of one of TikTok's most durable audio trends: the "Outstanding" desk-concert parody inspired by NPR's Tiny Desk series. The product works with elegant simplicity. Users upload between one and five photographs—of themselves, friends, or anyone else willing to be part of a video—and the software places each face into a corresponding position within the meme template: lead vocalist, keyboardist, backing vocalists (two positions), or saxophonist. The system then renders a fresh 19-second vertical video in 720p, framed and edited to match the original's four-shot structure and cramped office setting. Crucially, the video ships without audio, requiring users to add the meme's iconic backing track directly on TikTok—a design choice that sidesteps licensing complexity while keeping the creation workflow focused. What distinguishes this approach is its commitment to reducing friction. There is no account creation, no AI prompt engineering, no layer of post-production editing. A user selects seats, uploads photos, pays $8.99 once, and receives a render. The experience is transactional and transparent: no recurring charges, no data harvesting beyond the immediate render cycle, and explicit commitments to delete uploaded photos within a day. Empty seats automatically populate with fictional musicians, so a user can generate a complete video with just a single photo. The pricing model mirrors the service's ethos. At $8.99 per video, the cost sits well below the friction threshold that would deter casual participation, while clearly establishing a commercial model rather than a free-tier trap. The one-time payment structure removes the psychological friction of ongoing subscriptions. This targets a specific but sizable audience: TikTok creators and meme enthusiasts who want to participate in established viral formats without learning new tools. It succeeds by doing one thing exceptionally well—turning a meme template into a personalization platform—rather than overextending into editing suites or AI-generated content sprawl. The product respects both the mechanics of meme culture and the constraints of its platform.

Ai-generative-media
L
lok lok

Meme culture thrives on participation and remixing, but most viral formats require technical editing skills or specialized tools. This new service strips away that friction by automating the core mechanics of one of TikTok's most durable audio trends: the "Outstanding" desk-concert parody inspired by NPR's Tiny Desk series. The product works with elegant simplicity. Users upload between one and five photographs—of themselves, friends, or anyone else willing to be part of a video—and the software places each face into a corresponding position within the meme template: lead vocalist, keyboardist, backing vocalists (two positions), or saxophonist. The system then renders a fresh 19-second vertical video in 720p, framed and edited to match the original's four-shot structure and cramped office setting. Crucially, the video ships without audio, requiring users to add the meme's iconic backing track directly on TikTok—a design choice that sidesteps licensing complexity while keeping the creation workflow focused. What distinguishes this approach is its commitment to reducing friction. There is no account creation, no AI prompt engineering, no layer of post-production editing. A user selects seats, uploads photos, pays $8.99 once, and receives a render. The experience is transactional and transparent: no recurring charges, no data harvesting beyond the immediate render cycle, and explicit commitments to delete uploaded photos within a day. Empty seats automatically populate with fictional musicians, so a user can generate a complete video with just a single photo. The pricing model mirrors the service's ethos. At $8.99 per video, the cost sits well below the friction threshold that would deter casual participation, while clearly establishing a commercial model rather than a free-tier trap. The one-time payment structure removes the psychological friction of ongoing subscriptions. This targets a specific but sizable audience: TikTok creators and meme enthusiasts who want to participate in established viral formats without learning new tools. It succeeds by doing one thing exceptionally well—turning a meme template into a personalization platform—rather than overextending into editing suites or AI-generated content sprawl. The product respects both the mechanics of meme culture and the constraints of its platform.

Tiny Desk AI preview

Key features

  • Face Placement Automation: Automatically positions uploaded faces into meme template roles including lead vocalist, keyboardist, backing vocalists, and saxophonist.
  • Video Rendering: Generates 19-second vertical videos in 720p with the original Tiny Desk four-shot structure and cramped office aesthetic.
See full listing
Rumpelstiltskin AI

Viral meme replication typically demands either technical skill with video editing software or expensive creator services. Rumpelstiltskin AI solves this by reducing the barrier to near zero: upload a photo or two, pay $8.99, and receive a finished 15-second video ready to post. The product targets TikTok creators and social media users who want to participate in meme trends without learning editing timelines or committing to subscriptions. It operates on a template model, inserting user faces into a pre-shot sequence of the "tip toeing in my Jordans" meme. This is not face-swapping. The company films eight distinct shots with physical sets and actors, then composites the user's face into five to seven of those cuts depending on role selection. The remaining shots stay as original footage, typically showing hands, feet, or angles where face insertion would be unnecessary or uncanny. What distinguishes this product is its refusal of friction. There is no account creation, no prompt engineering, no timeline scrubbing. The user selects one or two photos, chooses a role (the imp, the girl, or both), clicks "cast," and the rendering begins. The company handles casting, filming, and compositing without asking for granular controls. The output is a silent MP4, intentionally design-limited so that users must attach audio on TikTok itself, which is where the meme lives. The pricing model reinforces this simplicity: $8.99 per video, no recurring charges, no cancellation mechanics. The company demonstrates transparency about its methods. The website explicitly states which shots are newly filmed and which are always pre-made footage, differentiating itself from services that promise total customization. Uploads are deleted 24 hours after rendering, and videos are private by default. The acceptable use policy requires confirmation that all people in uploaded photos are adults who consented and are not public figures, which attempts to preempt the most obvious legal and ethical misuses. The fixed edit structure is both a feature and a limitation. The 8-shot sequence never varies; cuts always land on the beat. This predictability means faster rendering and consistent output quality, but it also means zero creative deviation. Users cannot request different choreography, camera angles, or scene variations. At $8.99 for a one-time creation, the product is positioned as an impulse purchase rather than a production tool. It targets participants in trend cycles rather than professional creators, and it prices accordingly.

Ai-generative-media
L
lok lok

Viral meme replication typically demands either technical skill with video editing software or expensive creator services. Rumpelstiltskin AI solves this by reducing the barrier to near zero: upload a photo or two, pay $8.99, and receive a finished 15-second video ready to post. The product targets TikTok creators and social media users who want to participate in meme trends without learning editing timelines or committing to subscriptions. It operates on a template model, inserting user faces into a pre-shot sequence of the "tip toeing in my Jordans" meme. This is not face-swapping. The company films eight distinct shots with physical sets and actors, then composites the user's face into five to seven of those cuts depending on role selection. The remaining shots stay as original footage, typically showing hands, feet, or angles where face insertion would be unnecessary or uncanny. What distinguishes this product is its refusal of friction. There is no account creation, no prompt engineering, no timeline scrubbing. The user selects one or two photos, chooses a role (the imp, the girl, or both), clicks "cast," and the rendering begins. The company handles casting, filming, and compositing without asking for granular controls. The output is a silent MP4, intentionally design-limited so that users must attach audio on TikTok itself, which is where the meme lives. The pricing model reinforces this simplicity: $8.99 per video, no recurring charges, no cancellation mechanics. The company demonstrates transparency about its methods. The website explicitly states which shots are newly filmed and which are always pre-made footage, differentiating itself from services that promise total customization. Uploads are deleted 24 hours after rendering, and videos are private by default. The acceptable use policy requires confirmation that all people in uploaded photos are adults who consented and are not public figures, which attempts to preempt the most obvious legal and ethical misuses. The fixed edit structure is both a feature and a limitation. The 8-shot sequence never varies; cuts always land on the beat. This predictability means faster rendering and consistent output quality, but it also means zero creative deviation. Users cannot request different choreography, camera angles, or scene variations. At $8.99 for a one-time creation, the product is positioned as an impulse purchase rather than a production tool. It targets participants in trend cycles rather than professional creators, and it prices accordingly.

Rumpelstiltskin AI preview

Key features

  • Face Compositing: Inserts user faces into pre-filmed shots without face-swapping technology.
  • No Account Required: Users can create videos without signing up or creating an account.
See full listing
Zombie Couple Video

A trend tool for couples wanting participatory viral content, Zombie Couple Video generates fifteen-second vertical clips from two portraits for $8.99 per video. The creator positions this around the autumn 2026 zombie couple aesthetic—a scenario where one partner becomes undead in a rain-soaked standoff while the other, armed with a rifle, cannot bring themselves to shoot. The narrative resolves with a hard cut to a sunlit memory of the pair embracing. The product's strength lies in radical simplicity. There is no app to download, no account to create, no timeline to navigate. Users upload two images, confirm consent and age verification, and pay directly through Stripe. The entire process treats the output as a finished asset: the 720p MP4 arrives with music and sound effects already mixed in, formatted at 9:16 for mobile phone screens and ready to share immediately. The AI handles the substantive creative work. It transforms one photo into a zombie version, stages the survival scenario, choreographs the climactic jump, and cuts to the memory. The rendering happens server-side while users wait or step away. The examples shown—rendered from fictional test faces and presented unedited—suggest consistent visual coherence across the pipeline. Privacy and consent are explicit commitments. The founder emphasizes that all subjects must be adults, must consent to participation, and cannot be celebrities or public figures. Uploaded photos are deleted within 24 hours regardless of whether rendering succeeds. This directly addresses tensions around AI image generation and consent that plague many generative tools. The business model is transparent: each video costs eight dollars ninety-nine cents, charged once, with no recurring subscriptions or account balances. There are no credits to manage, no pressure to pre-purchase batches, no friction between the intention to create and the act of paying. What distinguishes this product is not the AI video generation capability itself but its ruthlessly focused application to a specific, trending scenario. The creator recognized a cultural moment and built exactly one thing to serve it well: an unburdened tool that removes friction between impulse and artifact. The stripped-down scope is deliberate. A user enters with two photos and a social media intention. They leave with a ready-to-post clip in under two minutes. The inherent risk is trend decay. The zombie couple aesthetic may fade as quickly as it rose. But the execution—the consent frameworks, the privacy commitments, the friction-free interface—establishes a working template that could theoretically adapt to other fleeting relationship video trends if cultural moments demand it.

Ai-generative-media
L
lok lok

A trend tool for couples wanting participatory viral content, Zombie Couple Video generates fifteen-second vertical clips from two portraits for $8.99 per video. The creator positions this around the autumn 2026 zombie couple aesthetic—a scenario where one partner becomes undead in a rain-soaked standoff while the other, armed with a rifle, cannot bring themselves to shoot. The narrative resolves with a hard cut to a sunlit memory of the pair embracing. The product's strength lies in radical simplicity. There is no app to download, no account to create, no timeline to navigate. Users upload two images, confirm consent and age verification, and pay directly through Stripe. The entire process treats the output as a finished asset: the 720p MP4 arrives with music and sound effects already mixed in, formatted at 9:16 for mobile phone screens and ready to share immediately. The AI handles the substantive creative work. It transforms one photo into a zombie version, stages the survival scenario, choreographs the climactic jump, and cuts to the memory. The rendering happens server-side while users wait or step away. The examples shown—rendered from fictional test faces and presented unedited—suggest consistent visual coherence across the pipeline. Privacy and consent are explicit commitments. The founder emphasizes that all subjects must be adults, must consent to participation, and cannot be celebrities or public figures. Uploaded photos are deleted within 24 hours regardless of whether rendering succeeds. This directly addresses tensions around AI image generation and consent that plague many generative tools. The business model is transparent: each video costs eight dollars ninety-nine cents, charged once, with no recurring subscriptions or account balances. There are no credits to manage, no pressure to pre-purchase batches, no friction between the intention to create and the act of paying. What distinguishes this product is not the AI video generation capability itself but its ruthlessly focused application to a specific, trending scenario. The creator recognized a cultural moment and built exactly one thing to serve it well: an unburdened tool that removes friction between impulse and artifact. The stripped-down scope is deliberate. A user enters with two photos and a social media intention. They leave with a ready-to-post clip in under two minutes. The inherent risk is trend decay. The zombie couple aesthetic may fade as quickly as it rose. But the execution—the consent frameworks, the privacy commitments, the friction-free interface—establishes a working template that could theoretically adapt to other fleeting relationship video trends if cultural moments demand it.

Zombie Couple Video preview

Key features

  • Two-Portrait Generation: Transforms two uploaded portraits into a 15-second zombie couple scenario video
  • No Account Required: Upload photos, verify consent and age, and pay—no app, login, or setup needed
See full listing
Bulin 47 AI

Capitalizing on a viral dembow moment that swept through Latin media in October 2026, this tool converts a single selfie into a 12-second vertical video of the user lip-synced to a freestyle verse that generated tens of millions of views across platforms. The service addresses a specific use case: enabling social media users to participate in a cultural trend without requiring video production skills, equipment, or account creation. The product's core strength is its radical simplicity. Users upload one clear facial photograph, verify they own the likeness, and pay $8.99 for a rendered MP4. No editing interface, no customization prompts, no strategic decisions beyond image selection. The output arrives as a mobile-ready vertical clip with lip-sync timing calibrated to the beat. The silent video design—users add audio when posting—keeps the production pipeline focused and the tool's scope deliberately narrow. Several design choices reveal intentional restraint. Uploaded images disappear within 24 hours, treating data minimization as a feature rather than a policy footnote. The service operates without accounts or subscriptions, eliminating authentication friction and the pressure to grow monthly active users. The creator frames this as an unofficial fan tool with no artist affiliation, setting clear expectations while sidestepping brand partnership complications. The one-time payment model at $8.99 per video signals the creators understand their own market constraints. This is a trend-capture product built for a moment, not a platform engineered for perpetual engagement. The business structure treats each video as a discrete transaction: pay once, receive an asset, the relationship ends. Users retain no profile, no library, no reason to return except to make another video during the trend's active window. The limiting factor is self-evident: viral moments in music have finite lifespans. The tool's entire value depends on sustained participation in the Bulin 47 trend. Should interest fade, so does relevance. The product makes no attempt to extend utility beyond the specific cultural moment it targets, which appears intentional rather than an oversight. This focus, while commercially risky long-term, makes the offering honest about what it is and what it actually does.

Ai-generative-media
L
lok lok

Capitalizing on a viral dembow moment that swept through Latin media in October 2026, this tool converts a single selfie into a 12-second vertical video of the user lip-synced to a freestyle verse that generated tens of millions of views across platforms. The service addresses a specific use case: enabling social media users to participate in a cultural trend without requiring video production skills, equipment, or account creation. The product's core strength is its radical simplicity. Users upload one clear facial photograph, verify they own the likeness, and pay $8.99 for a rendered MP4. No editing interface, no customization prompts, no strategic decisions beyond image selection. The output arrives as a mobile-ready vertical clip with lip-sync timing calibrated to the beat. The silent video design—users add audio when posting—keeps the production pipeline focused and the tool's scope deliberately narrow. Several design choices reveal intentional restraint. Uploaded images disappear within 24 hours, treating data minimization as a feature rather than a policy footnote. The service operates without accounts or subscriptions, eliminating authentication friction and the pressure to grow monthly active users. The creator frames this as an unofficial fan tool with no artist affiliation, setting clear expectations while sidestepping brand partnership complications. The one-time payment model at $8.99 per video signals the creators understand their own market constraints. This is a trend-capture product built for a moment, not a platform engineered for perpetual engagement. The business structure treats each video as a discrete transaction: pay once, receive an asset, the relationship ends. Users retain no profile, no library, no reason to return except to make another video during the trend's active window. The limiting factor is self-evident: viral moments in music have finite lifespans. The tool's entire value depends on sustained participation in the Bulin 47 trend. Should interest fade, so does relevance. The product makes no attempt to extend utility beyond the specific cultural moment it targets, which appears intentional rather than an oversight. This focus, while commercially risky long-term, makes the offering honest about what it is and what it actually does.

Bulin 47 AI preview

Key features

  • Selfie to Video: Converts a single photograph into a 12-second lip-synced vertical video.
  • Automatic Lip-Sync: Renders video with lip-sync timing calibrated to the beat.
See full listing
My Hotel Lobby AI

Creating viral social media content typically requires either significant technical skills or expensive tools. This AI video generator addresses that friction by packaging a single trending format into an extremely focused product that requires nothing more than two photos and $8.99. The core service transforms a pair of user-supplied images into 15-second TikTok videos matching the "Hotel Lobby" trend, where one photo raps into a hanging microphone while the other dances in an orange booth. The template is pre-configured, meaning users skip the usual AI video workflow of writing prompts, selecting models, or tweaking parameters. The service handles lip-syncing automatically to the established trend sound, and the output arrives pre-formatted in 720p MP4 at 16:9 aspect ratio—ready to post directly. What distinguishes this product is its deliberate simplicity. Most AI video tools force users to learn their systems, experiment with settings, and make creative decisions. This one does the opposite: it eliminates options. There is no account signup requirement, no creative customization, no editing phase. Users select two images, confirm they have permission to use them, and submit payment. The philosophy of constraint-driven design shows throughout. The product even includes a feature to swap performer positions before payment, eliminating a common source of regret with one-way transactions. Privacy receives explicit attention in the product design. The service deletes photos within 24 hours, whether the generation succeeds or fails. The terms explicitly address consent, prohibiting use of images containing minors, celebrities, or public figures—a meaningful guardrail against the misuse that plagues many generative tools. The pricing structure removes subscription friction entirely. At $8.99 per video with no recurring charges, the transaction is transparent and one-off. Failed generations automatically refund credits, eliminating the anxiety that often surrounds experimental features. The target user is clear: social media creators who want to participate in a specific trend without spending hours learning software or acquiring new skills. This narrowness is intentional. The product refuses the temptation to become a general AI video tool, instead excelling at a single outcome. That focus, combined with the frictionless workflow and transparent pricing, creates a compelling value proposition for anyone who sees the trend and wants in without the complexity.

Ai-generative-media
L
lok lok

Creating viral social media content typically requires either significant technical skills or expensive tools. This AI video generator addresses that friction by packaging a single trending format into an extremely focused product that requires nothing more than two photos and $8.99. The core service transforms a pair of user-supplied images into 15-second TikTok videos matching the "Hotel Lobby" trend, where one photo raps into a hanging microphone while the other dances in an orange booth. The template is pre-configured, meaning users skip the usual AI video workflow of writing prompts, selecting models, or tweaking parameters. The service handles lip-syncing automatically to the established trend sound, and the output arrives pre-formatted in 720p MP4 at 16:9 aspect ratio—ready to post directly. What distinguishes this product is its deliberate simplicity. Most AI video tools force users to learn their systems, experiment with settings, and make creative decisions. This one does the opposite: it eliminates options. There is no account signup requirement, no creative customization, no editing phase. Users select two images, confirm they have permission to use them, and submit payment. The philosophy of constraint-driven design shows throughout. The product even includes a feature to swap performer positions before payment, eliminating a common source of regret with one-way transactions. Privacy receives explicit attention in the product design. The service deletes photos within 24 hours, whether the generation succeeds or fails. The terms explicitly address consent, prohibiting use of images containing minors, celebrities, or public figures—a meaningful guardrail against the misuse that plagues many generative tools. The pricing structure removes subscription friction entirely. At $8.99 per video with no recurring charges, the transaction is transparent and one-off. Failed generations automatically refund credits, eliminating the anxiety that often surrounds experimental features. The target user is clear: social media creators who want to participate in a specific trend without spending hours learning software or acquiring new skills. This narrowness is intentional. The product refuses the temptation to become a general AI video tool, instead excelling at a single outcome. That focus, combined with the frictionless workflow and transparent pricing, creates a compelling value proposition for anyone who sees the trend and wants in without the complexity.

My Hotel Lobby AI preview

Key features

  • Two Photo Conversion: Transforms two user-supplied images into 15-second Hotel Lobby trend TikTok videos
  • Template-Based Workflow: Pre-configured template eliminates writing prompts, selecting models, or tweaking parameters
See full listing
RapZap

The appeal of meme culture and viral moments lies partly in their unpredictability—watching an unexpected person inserted into a familiar scene creates comedy through surprise and recognition. A social media creator seeking to tap into this trend faces a barrier: producing convincing video content requires either professional equipment and editing skills, or access to expensive AI tools that demand technical knowledge and ongoing subscriptions. RapZap addresses this friction by packaging AI video generation into a strictly bounded, template-based service. The product targets people who want to generate short performance clips for social sharing without building skills or maintaining an account. Users select from five predefined scenarios—a hotel lobby duet, a solo rap verse, a zombie love story, a barn dance meme recreation, and a desk concert—add between one and five face-forward photos, pay 8.99 dollars once, and receive a finished 720p MP4 ready for TikTok, Instagram Reels, or YouTube Shorts. The design emphasizes simplicity over customization. No prompting interface exists; no editing stage comes after rendering; no ongoing relationship with the platform is required. This constraint-based approach avoids the choice paralysis that plagues general-purpose AI tools while keeping friction minimal. Photos are deleted within 24 hours of processing, addressing privacy concerns without requiring lengthy data retention policies. The underlying technology stacks image-based face reconstruction with video generation to animate body movement and mouth synchronization. The quality depends heavily on input—the site explicitly recommends sharp, forward-facing shots with one person or animal per photo—but real examples from the live pipeline demonstrate output suitable for social sharing at the specified resolution and frame rates. Financially, the model is straightforward: 8.99 dollars per video with no recurring charges or hidden account requirements. This positions RapZap as an impulse purchase for casual creators rather than a platform requiring ongoing commitment. The one-time transaction removes decision friction for users curious enough to try but unwilling to subscribe. The service succeeds by acknowledging what it is not. It rejects the ambition of general AI video tools in favor of nailing a narrow use case: turning ordinary photos into recognizable meme variations that work at short-form video scale. That focused scope is its strength. For someone wanting to make their friend appear in a viral moment without learning video production, RapZap delivers exactly what is promised.

Ai-generative-media
L
lok lok

The appeal of meme culture and viral moments lies partly in their unpredictability—watching an unexpected person inserted into a familiar scene creates comedy through surprise and recognition. A social media creator seeking to tap into this trend faces a barrier: producing convincing video content requires either professional equipment and editing skills, or access to expensive AI tools that demand technical knowledge and ongoing subscriptions. RapZap addresses this friction by packaging AI video generation into a strictly bounded, template-based service. The product targets people who want to generate short performance clips for social sharing without building skills or maintaining an account. Users select from five predefined scenarios—a hotel lobby duet, a solo rap verse, a zombie love story, a barn dance meme recreation, and a desk concert—add between one and five face-forward photos, pay 8.99 dollars once, and receive a finished 720p MP4 ready for TikTok, Instagram Reels, or YouTube Shorts. The design emphasizes simplicity over customization. No prompting interface exists; no editing stage comes after rendering; no ongoing relationship with the platform is required. This constraint-based approach avoids the choice paralysis that plagues general-purpose AI tools while keeping friction minimal. Photos are deleted within 24 hours of processing, addressing privacy concerns without requiring lengthy data retention policies. The underlying technology stacks image-based face reconstruction with video generation to animate body movement and mouth synchronization. The quality depends heavily on input—the site explicitly recommends sharp, forward-facing shots with one person or animal per photo—but real examples from the live pipeline demonstrate output suitable for social sharing at the specified resolution and frame rates. Financially, the model is straightforward: 8.99 dollars per video with no recurring charges or hidden account requirements. This positions RapZap as an impulse purchase for casual creators rather than a platform requiring ongoing commitment. The one-time transaction removes decision friction for users curious enough to try but unwilling to subscribe. The service succeeds by acknowledging what it is not. It rejects the ambition of general AI video tools in favor of nailing a narrow use case: turning ordinary photos into recognizable meme variations that work at short-form video scale. That focused scope is its strength. For someone wanting to make their friend appear in a viral moment without learning video production, RapZap delivers exactly what is promised.

RapZap preview

Key features

  • Template-Based Generation: Choose from five predefined scenarios without customization options
  • One-Time Payment: $8.99 per video with no subscriptions or ongoing account requirements
See full listing
Meme Video Maker

Viral short-form video creation has historically required either video editing skills or AI prompt fluency—two barriers that keep most people from participating in trending meme formats. This service eliminates both by packaging trending video templates with face-insertion AI, letting users simply upload photos and receive finished MP4s optimized for TikTok, Instagram Reels, and YouTube Shorts. The product targets social media users who want to capitalize on viral trends without learning Adobe Premiere or mastering AI prompting. The pitch is straightforward: pick a trending template, upload between one and five photos, and the system generates a 15-second video with the user's face composited into the choreography or scenario. Every video exports watermark-free in vertical 9:16 format. What distinguishes this offering from broader AI video generation tools is its template-first design. Rather than asking users to describe what they want, the service presents curated trending formats—currently 17 active templates spanning dance routines, music duets, comedy scenarios, sports moments, and cinematic sequences. This constraint is actually a strength; it trades unlimited creative freedom for reliability and speed. A template-based approach also naturally produces scroll-stopping content because the templates themselves are already proven viral hits. The execution details suggest thoughtful product design. Photo upload works via traditional browser selection or QR code scanning from mobile, acknowledging that users often have images on their phones. The service provides specific guidance on photo composition—front-facing, clear lighting, waist-up framing—to optimize AI face-insertion results. Render time is quoted at four minutes, competitive for real-time content creation. The privacy model deletes uploaded photos after 24 hours, addressing a legitimate concern about personal image data. The business model operates on a credit system, with a single video consuming 90 credits, though explicit pricing is not disclosed on the available text. The company emphasizes a refund guarantee, reducing perceived risk for first-time users evaluating the service. The main limitation is format rigidity. Users don't generate videos; they participate in predetermined templates. This works perfectly for trend-chasing and social proof but won't appeal to creators wanting original concepts. For the intended audience—people who want to be seen in trending formats without friction—the constraint is a feature, not a bug.

Ai-generative-media
Z
zeng arya

Viral short-form video creation has historically required either video editing skills or AI prompt fluency—two barriers that keep most people from participating in trending meme formats. This service eliminates both by packaging trending video templates with face-insertion AI, letting users simply upload photos and receive finished MP4s optimized for TikTok, Instagram Reels, and YouTube Shorts. The product targets social media users who want to capitalize on viral trends without learning Adobe Premiere or mastering AI prompting. The pitch is straightforward: pick a trending template, upload between one and five photos, and the system generates a 15-second video with the user's face composited into the choreography or scenario. Every video exports watermark-free in vertical 9:16 format. What distinguishes this offering from broader AI video generation tools is its template-first design. Rather than asking users to describe what they want, the service presents curated trending formats—currently 17 active templates spanning dance routines, music duets, comedy scenarios, sports moments, and cinematic sequences. This constraint is actually a strength; it trades unlimited creative freedom for reliability and speed. A template-based approach also naturally produces scroll-stopping content because the templates themselves are already proven viral hits. The execution details suggest thoughtful product design. Photo upload works via traditional browser selection or QR code scanning from mobile, acknowledging that users often have images on their phones. The service provides specific guidance on photo composition—front-facing, clear lighting, waist-up framing—to optimize AI face-insertion results. Render time is quoted at four minutes, competitive for real-time content creation. The privacy model deletes uploaded photos after 24 hours, addressing a legitimate concern about personal image data. The business model operates on a credit system, with a single video consuming 90 credits, though explicit pricing is not disclosed on the available text. The company emphasizes a refund guarantee, reducing perceived risk for first-time users evaluating the service. The main limitation is format rigidity. Users don't generate videos; they participate in predetermined templates. This works perfectly for trend-chasing and social proof but won't appeal to creators wanting original concepts. For the intended audience—people who want to be seen in trending formats without friction—the constraint is a feature, not a bug.

Meme Video Maker preview

Key features

  • Template-Based Creation: Choose from 17 trending video formats spanning dance routines, comedy, and cinematic sequences
  • Face Insertion AI: AI automatically composites user faces into choreography and scenarios within templates
See full listing