Repository navigation
Studio: pick the quant of a GGUF dictation model in Voice settings - #12900
Conversation


Settings > Voice offered 6 of the 18 audio.cpp ASR folders the Transcribe
page runs, and a saved folder id was reset to the default on reload. The
picker now derives its GGUF rows from the same catalog Transcribe uses,
keeps the existing keys, adds a Moonshine medium key, accepts folder ids,
reads folder sizes from the cached variant listing, marks downloaded
models, finds listed models by name in search, and adds Danish for Hviske.
A package-folder dictation model such as GigaAM ships several quants,
but Settings > Voice could only run the folder's default one. The voice
store now remembers the picked quant beside the model, like Transcribe
does, and a Select under the model picker offers the folder's quants
with sizes and an on-device dot. The quant travels with every Settings
dictation path: load, download, raw transcription, chat audio upload,
the Audio page's reference transcription and the download prompt, which
now shows the quant's size. Offline, a picked quant that is not on disk
is reported as not downloaded instead of an unknown variant, so the
download prompt appears rather than an error.


|
The red |
…Select

A stopped or failed download of a second quant read as complete, because
a row counts as downloaded once any quant is cached; the mirror now
checks cancel and error first. The upload dialog said Ready for a pinned
quant that was not on disk, and the download prompt took the quant from
live settings instead of the request; both now use the pinned quant.
Unpinned, the quant Select shows what a bare load runs: the resident
quant (mapping the cache's loose key), else the first cached one.
…dio-audio-stt-settings-quant

# Conflicts:
#	studio/backend/core/inference/audio_cpp_models.py
#	studio/backend/tests/test_audio_cpp_umbrella_catalog.py
#	studio/frontend/src/features/settings/stores/stt-model-catalog.ts
#	studio/frontend/src/features/settings/tabs/voice-tab.tsx
#	studio/frontend/tests/audio-cpp-catalog.test.ts
Without a browser speech service, Studio switched dictation to local as
soon as any quant of the model was on disk, so the next recording failed
on a pinned quant that was not. The switch now checks that quant first,
through the same helper upload readiness uses. A download's warm-up also
remembers which quant it fetched, so picking another quant meanwhile no
longer loads one that is not on disk.
…d quants

With no quant pinned, the quant Select showed the resident quant as its
value, so picking that same quant changed nothing and an idle unload
later fell back to another one. The Select now holds the pin and shows
the running quant as its placeholder, so any pick is saved. A quant the
listing leaves out (an offline, cache-only listing) now counts as not
downloaded, and a download adopted without a known quant only warms an
unpinned row.
An offline listing keys cached files by what tells them apart, such as
ctc/F16 for v3-ctc/F16, so treating a key it leaves out as not
downloaded showed a cached GigaAM quant as missing and blocked offline
dictation. A listing now marks the pinned quant missing only through its
own row; anything else defers to the row status, and the backend's
not-downloaded reply still raises the download prompt.
With another quant of the row cached, a failed download of the pinned
quant read as not downloaded, with a fresh Download button, hiding the
error. It now shows the same failed state and Retry a row gets.
…ll picked

The Voice tab loads the model when a download it watched finishes, but it
loaded the quant picked now, so switching quant during a download tried
to load one that was not on disk. It now remembers the quant it started
and loads only that one; a download it adopted loads only when no quant
is pinned.

|
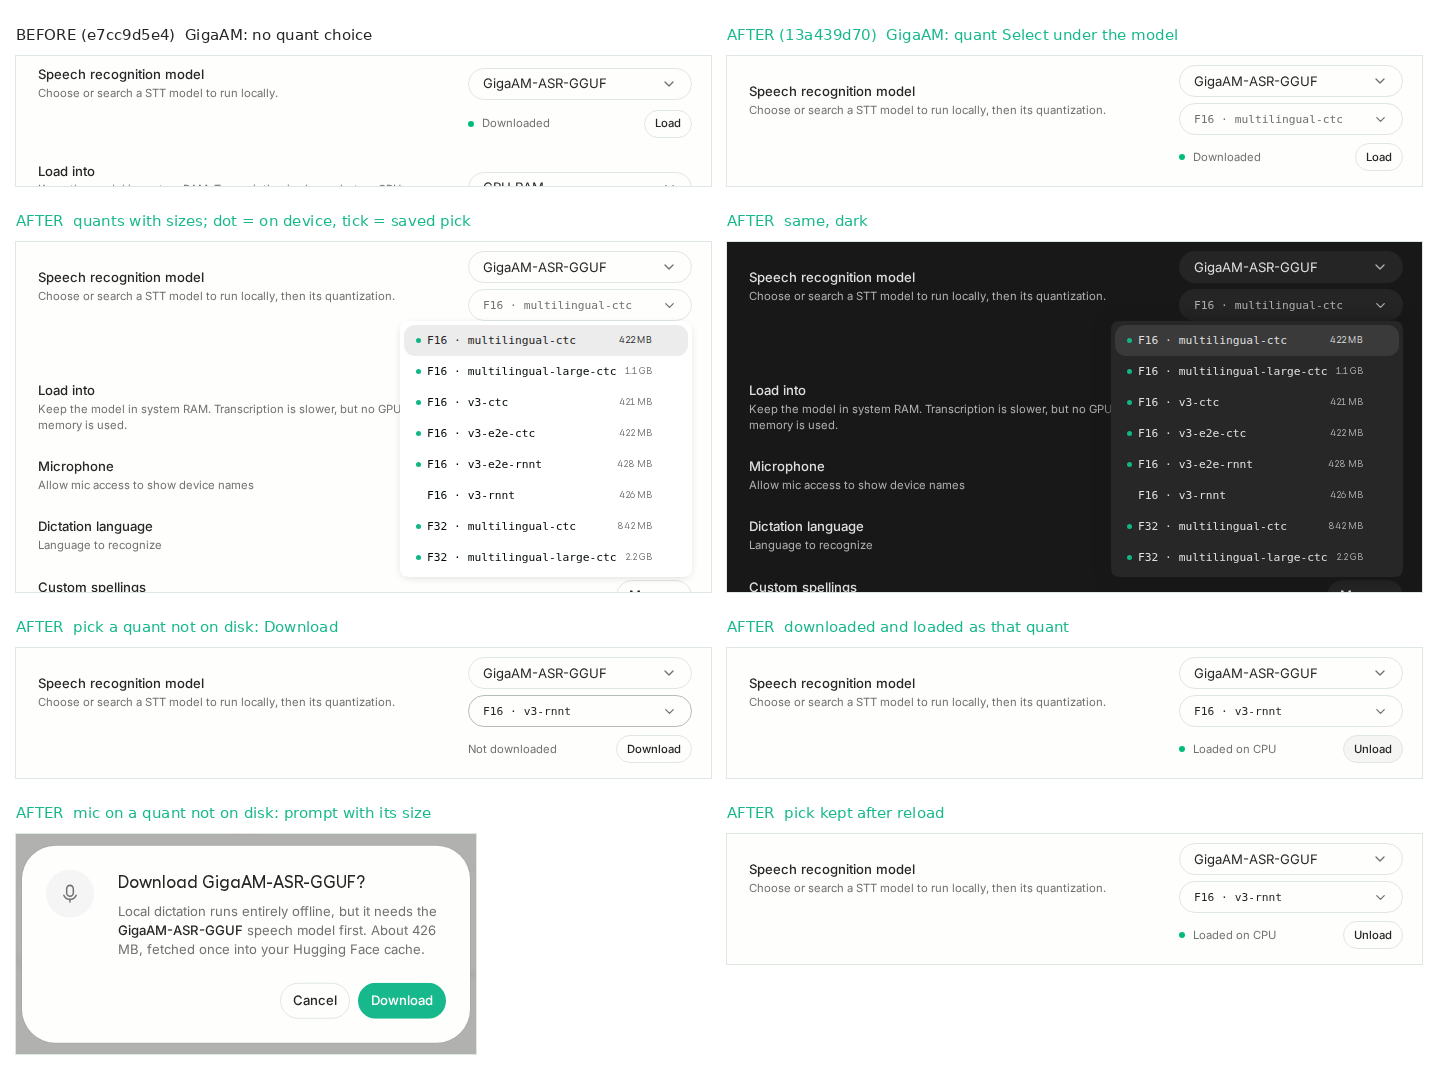
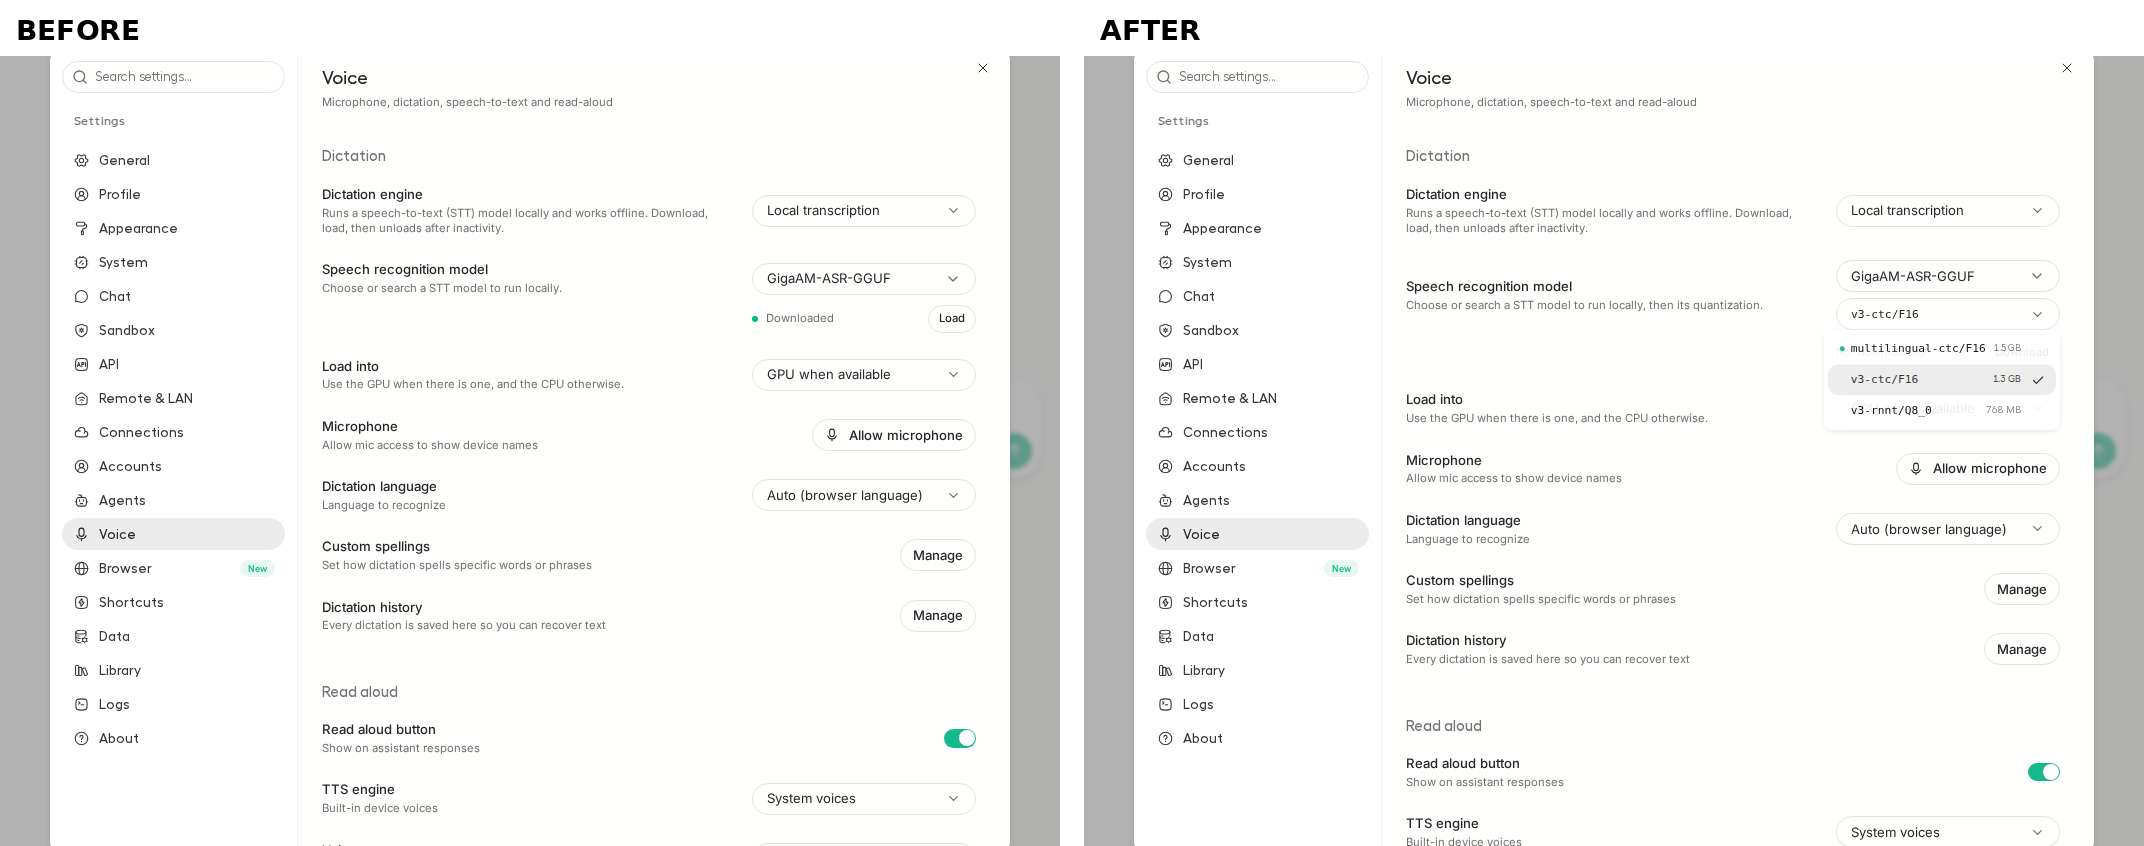
Settings > Voice now has a quantization choice for audio.cpp package-folder dictation models with several quants, such as GigaAM (eight). The pick is saved with the model and used by dictation, recorded-audio uploads, the Audio page's reference transcription and the download prompt, which shows that quant's size. Models with one quant and saved dictation keys show no extra control. What changed
At
Before: |


VerificationReviewed and repaired source head: Required mirror convergence completed on mirror PR #119 at
UI evidenceUbuntu 26.04.1 x86_64, headless Chromium 153.0.8010.12, 1440x900. Both sides used isolated Studio installs and isolated caches inside a separate process namespace. The settings endpoints were deterministically mocked; no real user session or desktop browser was used. The pair compares merge base Observed: the PR adds the Quantization selector, keeps
|

 mahiatlinux
left a comment
mahiatlinux
left a comment
There was a problem hiding this comment.
LGTM! Ready to merge, all manually checked.


Summary
A package-folder dictation model such as GigaAM ships several quants, but Settings > Voice could only run the folder's default one. Voice settings now has a Quantization select under the model picker when the selected folder has more than one quant. It lists each quant with its size and an on-device dot, and picking one unloads the current model and loads the new quant.
Changes
sttGgufVariantnext tosttModel. It is cleared when the model changes (including the fallback to the default model on a language switch) and only rehydrated when the saved model is still the selected one.sttModelVariant()andwithSttVariant()instt-model-catalog.tsapply the quant only to package-folder rows. Saved keys and the other engines ignore it./transcribe/rawgetsrow:variant, so a cold sidecar does not fall back to the default quant), chat audio upload (pinned in the upload snapshot), the Audio page's reference transcription, and the download prompt. The download prompt now shows the quant's size, read from the cached GGUF listing.resolve_audio_cpp_stt_modelraisesSttModelNotDownloadedErrorinstead ofSttModelIdErrorwhen, offline, a picked quant is not on disk but its row is a runnable ASR model. Callers then show the download prompt instead of an unknown-variant error. A folder for another task (for example Kokoro with a quant) is still rejected as a wrong model.sttQuantLabelandsttQuantDescriptionin all 14 locales.Testing
npm test: 10756 passed. New cases intests/audio-cpp-catalog.test.tscover which rows take a saved quant, clearing and rehydrating the quant with its model, the quant reaching every Settings dictation path, and when the Select appears.npm run typecheck, stricti18n:check,catalog:checkandnpm run buildpass.test_audio_cpp_models,test_stt_audiocpp_details,test_audio_cpp_umbrella_catalog,test_openai_audio_transcriptions_route,test_stt_sidecarandtest_stt_transcription_cancellation.test_audio_cpp_modelsadds the offline not-downloaded quant case and the wrong-task case.POST /api/inference/audio/transcribe/rawwith GigaAM, on CPU and on an idle GPU::v3-ctc/F16loads that quant (loaded_variantmatches), the bare row keeps the resident quant,:multilingual-ctc/F16switches and returns the LibriSpeech transcript, and a quant that is not on disk returns 409 not downloaded (422 before the backend change).