Skip to content

Studio: keep long reasoning responsive with bounded pages - #10717

Merged
Etherll merged 7 commits into
unslothai:mainfrom
wasimysaid:fix/studio-long-reasoning-window
Sep 11, 2026
Merged

Etherll merged 7 commits into
unslothai:mainfrom
wasimysaid:fix/studio-long-reasoning-window

Conversation

@wasimysaid

Copy link
Copy Markdown
Collaborator

Summary

Carry forward the reasoning-windowing direction validated in #9477, without its backend/channel-fidelity changes or general streaming-render rewrite. The follow-up correction established that pagination helps; this PR deliberately accepts page-limited native find/selection in exchange for a usable long-thinking UI.

  • Reasoning up to 16,384 characters retains its existing renderer/UX. Longer traces mount one ≤8,192-character source page, including on saved-trace load and after completion.
  • Earlier / Newer / Latest navigation; older pages stay stable while new tokens arrive. Navigation sits above, not over, the scrolling content and fits narrow screens.
  • Full Copy reasoning still uses the canonical stored trace. No data is discarded, no persistence/backend changes, no new dependencies, and normal assistant answers retain their existing rendering/highlighting.
  • Reuses the existing Markdown renderer through a source-fed entrypoint. Prefers paragraph/line boundaries, tracks fences incrementally, and labels a plain-source fallback when a page cuts an oversized/open code fence rather than inventing partial code-copy semantics.
  • Enables by actual trace length, not model name or reasoning-effort setting: High is a common trigger, not a reliable measure of UI work.

Live verification

Selected the on-device unsloth/Qwen3.8-27B-GGUF / UD-Q4_K_XL in Studio, set High, and submitted the supplied Tesla-coil demonstration-room prompt, using local inference on one B200. The baseline produced 79,366 reasoning characters and a separate 38,350-character answer. A real after-run also exercised paging while streaming.

Verified in production Studio/Chromium:

  • Earlier-page text and scroll position remained identical while the live trace grew from 24,875 to 26,879 characters; Latest resumed following the live page.
  • Three backward/forward transitions returned to the exact latest rendered page; keyboard navigation and reopen remained bounded.
  • Actual clipboard output was 79,366 characters, SHA-256 ce5c75aaf94b604ca36de7af0cfb5e1b1923a6a1b9e048422c5958bf17ca8d3f, exactly matching the canonical trace.
  • Final desktop (1440×1000) and narrow (390×844) navigation inspected visually; final saved-trace copy/navigation checks passed again after the layout polish.

Final long reasoning UX

Narrow-screen reasoning navigation

Narrow navigation

Native WebKit A/B

Immutable baseline 89b7ff009d93a3eaf4fa332d4fa6610607c27433 vs final c6430c6c13d98ead272bb9f2f086d7ff7e6fe72b. Native MiniBrowser/WebKitGTK 2.50.4, production Vite bundles, real Studio Thread/assistant-ui/reasoning renderer. The same captured Qwen reasoning was truncated/repeated to exact 8K/100K/250K workloads, streamed with the same 4,096-character / 16ms requested cadence; hashes matched across both refs. This is controlled accelerated renderer replay, not a claim about model tokens/sec or a packaged Tauri run.

Workload Mounted reasoning chars, before → final Replay duration Worst frame gap p95 frame gap
8K control 7,970 → 7,970; no controls 175 → 182 ms 73 → 74 ms 53 → 55 ms
100K 99,195 → 7,427 9,159 → 3,580 ms 1,360 → 1,323 ms 768 → 254 ms
250K 247,986 → 7,923 89,241 → 3,436 ms 5,107 → 337 ms 4,222 → 64 ms

The long-trace DOM-bound assertion fails on baseline and passes on final; the short control remains unchanged. Native Earlier/Newer/Latest checks also pass. The 100K worst outlier remains ~1.3s: this is a focused fix for unbounded reasoning growth, not a claim that all rendering stalls are eliminated. Measurements are individual controlled runs, not a statistical performance guarantee.

Sanitized facts and workload hashes

Tests

  • npm test — 7,284 passed on final source
  • npm run typecheck — passed (production + test projects)
  • npm run build — passed
  • npm run i18n:check:strict — passed
  • Added lossless paging, CRLF/Unicode, giant/open fences, stable strides, replacement/reset, and no-part-scope source-render regression tests.
  • Independent review findings (group-context crash, cold-load bound, message-identity reset) fixed and rechecked; live saved-trace rendering verified.

Accepted trade-offs / scope

Browser find, native selection, printing, deep links, and screen-reader traversal cannot reach unmounted reasoning; page navigation and full canonical Copy reasoning remain available. Very large split blocks use the labelled plain-source fallback; this is not a full Markdown-document virtualization engine. Cross-platform packaged desktop builds and every Markdown construct are not claimed as verified. Six frontend/test files only; no provider/channel suppression, model/backend behavior changes, or new dependencies.

Adapt the reasoning-only windowing direction validated in unslothai#9477. Keep full canonical copy and ordinary assistant rendering, with stable latest/earlier page navigation and a bounded oversized-fence fallback.
@chatgpt-codex-connector

chatgpt-codex-connector Bot commented Sep 10, 2026 •

Copy link
Copy Markdown

Codex Review Summary

This comment shows the latest Codex review activity on this pull request.

Review Status Commit Review trigger
📝 Code Review ✅ Completed 2026-09-11T08:30:52.887610Z c17668e Manual request
ℹ️ About Codex in GitHub

Your team has set up Codex to review pull requests in this repo. Reviews are triggered when you

  • Open a pull request for review
  • Mark a draft as ready
  • Comment "@codex review" or "@codex security review".

Codex reacts with 👀 while any review is running, comments if it has suggestions, and reacts with 👍 once all reviews finish with no findings.

@chatgpt-codex-connector chatgpt-codex-connector Bot left a comment

Copy link
Copy Markdown

Choose a reason for hiding this comment

The reason will be displayed to describe this comment to others. Learn more.

💡 Codex Review

Here are some automated review suggestions for this pull request.

Reviewed commit: c6430c6c13

ℹ️ About Codex in GitHub

Your team has set up Codex to review pull requests in this repo. Reviews are triggered when you

  • Open a pull request for review
  • Mark a draft as ready
  • Comment "@codex review".

If Codex has suggestions, it will comment; otherwise it will react with 👍.

Codex can also answer questions or update the PR. Try commenting "@codex address that feedback".

@unslothai unslothai deleted a comment from chatgpt-codex-connector Bot Sep 10, 2026
@wasimysaid

Copy link
Copy Markdown
Collaborator Author

@codex review

1 similar comment
@wasimysaid

Copy link
Copy Markdown
Collaborator Author

@codex review

@chatgpt-codex-connector chatgpt-codex-connector Bot left a comment

Copy link
Copy Markdown

Choose a reason for hiding this comment

The reason will be displayed to describe this comment to others. Learn more.

💡 Codex Review

Here are some automated review suggestions for this pull request.

Reviewed commit: 9db0681d48

ℹ️ About Codex in GitHub

Your team has set up Codex to review pull requests in this repo. Reviews are triggered when you

  • Open a pull request for review
  • Mark a draft as ready
  • Comment "@codex review".

If Codex has suggestions, it will comment; otherwise it will react with 👍.

Codex can also answer questions or update the PR. Try commenting "@codex address that feedback".

@danielhanchen

Copy link
Copy Markdown
Member

Confirmed the unbounded mounted trace in studio/frontend/src/components/assistant-ui/reasoning.tsx is still what main does, and the bounded page approach addresses it. Since browser find, native selection, printing and screen-reader traversal now only reach the mounted page, could you say how a user is expected to search a long trace before I review?

@wasimysaid

Copy link
Copy Markdown
Collaborator Author

@codex review

@chatgpt-codex-connector

Copy link
Copy Markdown

Codex Review: Didn't find any major issues. What shall we delve into next?

Reviewed commit: 1f52281ca6

ℹ️ About Codex in GitHub

Your team has set up Codex to review pull requests in this repo. Reviews are triggered when you

  • Open a pull request for review
  • Mark a draft as ready
  • Comment "@codex review".

If Codex has suggestions, it will comment; otherwise it will react with 👍.

Codex can also answer questions or update the PR. Try commenting "@codex address that feedback".

@Etherll Etherll self-assigned this Sep 11, 2026
@unslothai unslothai deleted a comment from chatgpt-codex-connector Bot Sep 11, 2026
@Etherll

Etherll commented Sep 11, 2026

Copy link
Copy Markdown
Collaborator

@codex review

@chatgpt-codex-connector

Copy link
Copy Markdown

You have reached your Codex usage limits for security reviews. Please try again later.

@Etherll

Etherll commented Sep 11, 2026

Copy link
Copy Markdown
Collaborator

@codex review

@chatgpt-codex-connector

Copy link
Copy Markdown

You have reached your Codex usage limits for security reviews. Please try again later.

@chatgpt-codex-connector

Copy link
Copy Markdown

Codex Review: Didn't find any major issues. Keep them coming!

Reviewed commit: c17668ec49

ℹ️ About Codex in GitHub

Your team has set up Codex to review pull requests in this repo. Reviews are triggered when you

  • Open a pull request for review
  • Mark a draft as ready
  • Comment "@codex review".

If Codex has suggestions, it will comment; otherwise it will react with 👍.

Codex can also answer questions or update the PR. Try commenting "@codex address that feedback".

@Etherll

Etherll commented Sep 11, 2026

Copy link
Copy Markdown
Collaborator

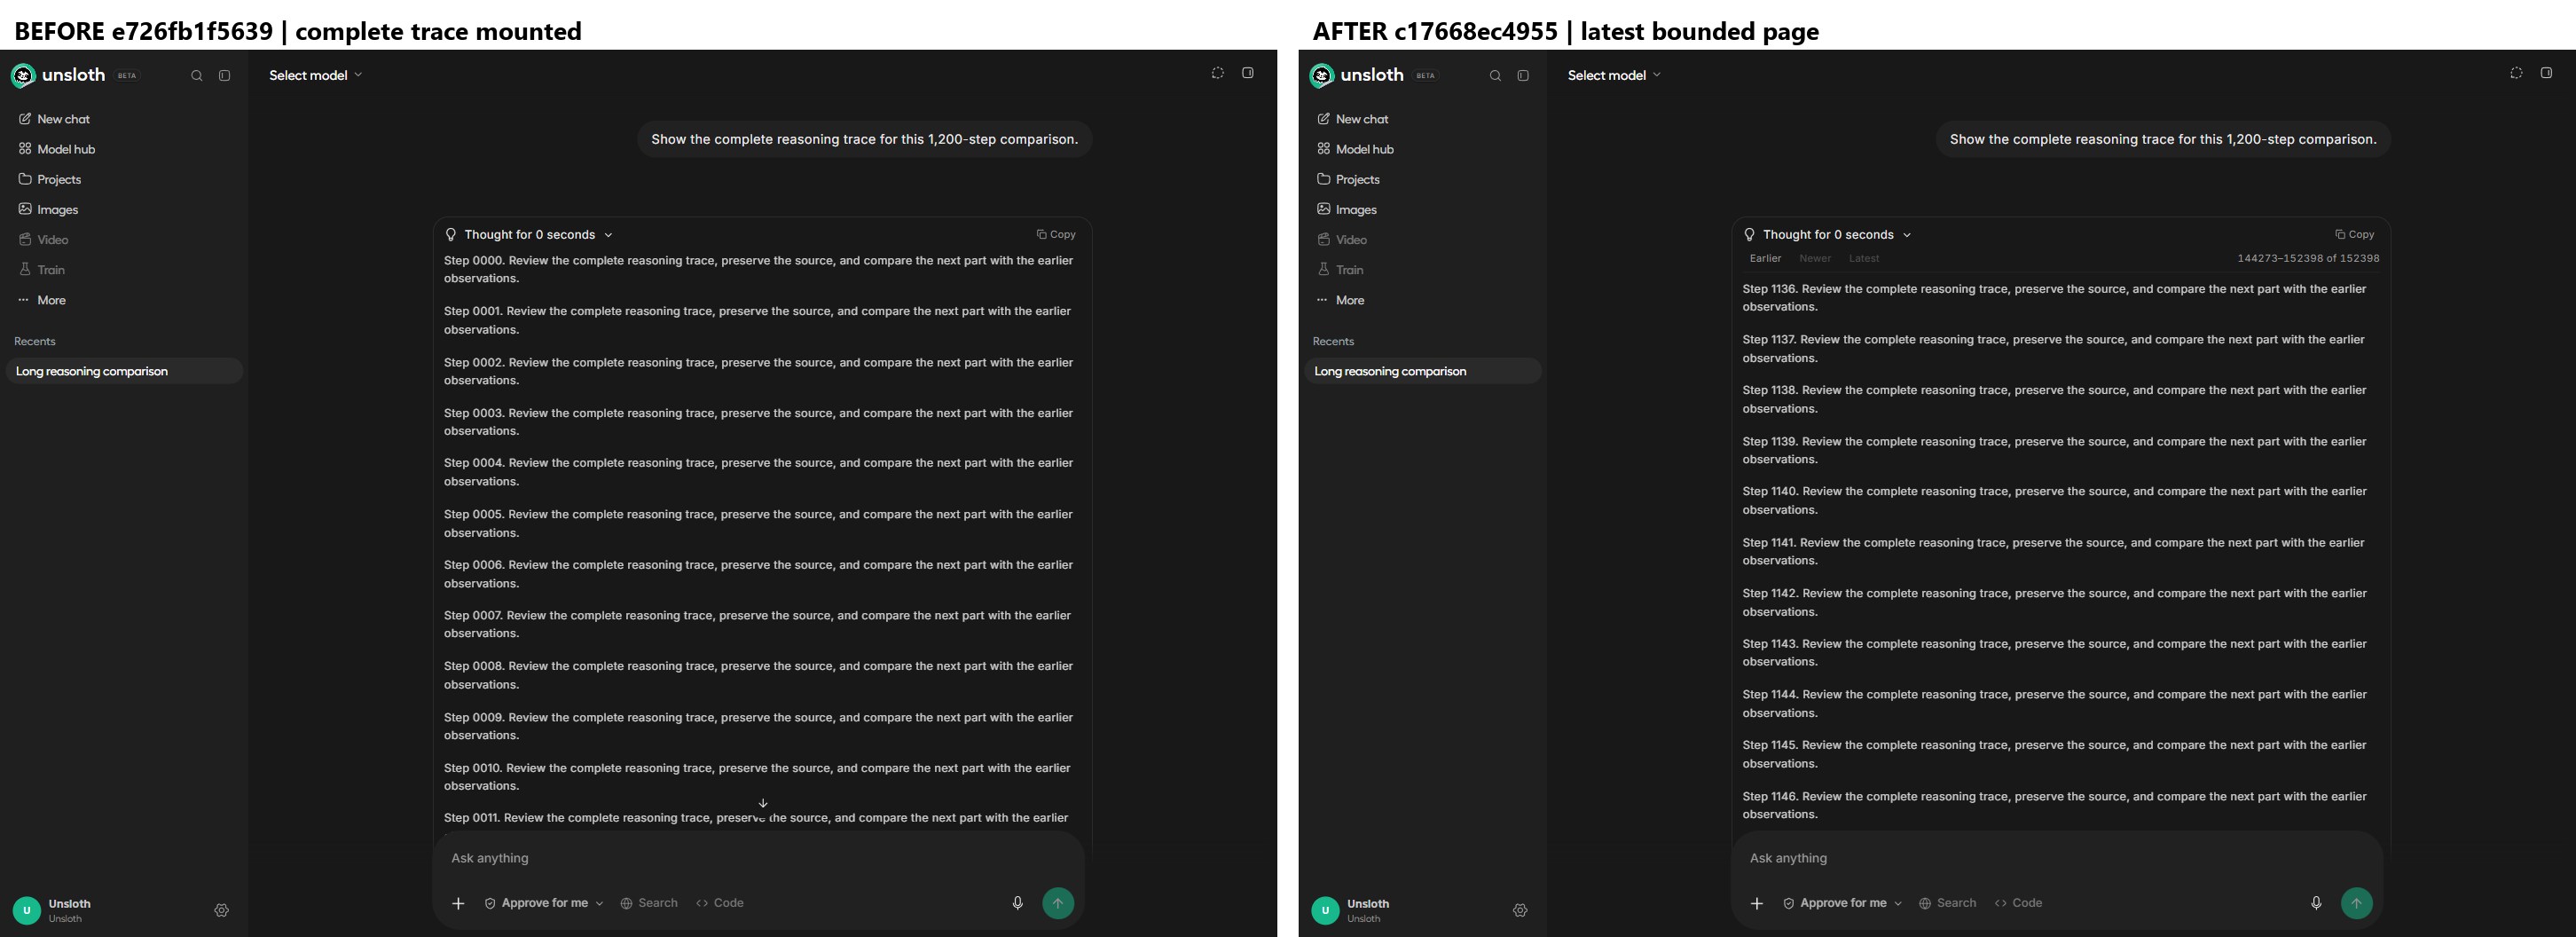
Long reasoning opens on a bounded page. At c17668ec4, Earlier no longer shows the latest body after the source range changes. Earlier, Newer, and Latest each render the matching source. Copy retains the full 152,398-character trace, and reload preserves the separate answer. Browser Find stays within the mounted page.

The new browser regression fails before the fix and passes after. 19 focused tests, type checking, the build, frontend CI, and Linux and Windows Studio UI checks pass. The optional Python 3.13 backend check still fails its unchanged idle-stream persistence assertion. Two optional macOS jobs remain queued; no required checks are reported. Local tests used saved or synthetic messages without GPU inference. Final-head review reported no major issues. Final-head security review was unavailable because of a service usage limit.

BEFORE: e726fb1f563948fabde75f35fd745158c210f3e9. AFTER: c17668ec4955672fba39ba60a9e9ef4ebf4f0e27. Same saved conversation, 1440x1000, Microsoft Edge.

Long reasoning before and after

@Etherll Etherll left a comment

Copy link
Copy Markdown
Collaborator

Choose a reason for hiding this comment

The reason will be displayed to describe this comment to others. Learn more.

LGTM !

@Etherll
Etherll merged commit 27a4ff6 into unslothai:main Sep 11, 2026
27 of 28 checks passed
@danielhanchen

Copy link
Copy Markdown
Member

Follow-up from re-checking this on studiobench and fuzzing the selector: #10922.

One latent defect, not a live one. pageStart could return an offset equal to the page end, which yields an empty page, and since Earlier sets the next page's end to this start, the chain then stops advancing. It needs maxCharacters at or under BOUNDARY_SEARCH_CHARACTERS, and reasoning.tsx passes no maxCharacters, so the shipped 8,192 default never reaches it. Nobody has hit this. It is reachable through the exported option, so it is worth closing.

Two things this did confirm about the change here. Pagination fires as described: on the studiobench 100K fixture, the largest pane goes from 76,618 mounted characters and 11,978 elements to 8,319 and 24, the whole open-reasoning document from 41,641 elements to 25,255, and the six panes under the trigger are byte-identical between arms. And the module is unusually conservative about platform surface, Range.intersectsNode rather than the non-standard Selection.containsNode, no lookbehind or /u in the fence regex, nothing persisted; Blink, Gecko and WebKit agree exactly on its output.

Worth knowing separately: on that fixture two of the three paginated panes rendered through the oversized-code plain-source fallback rather than the Markdown page, so part of the DOM reduction is Shiki not running at all. That is the labelled fallback working as designed, just more often than the description here implies.

@danielhanchen

Copy link
Copy Markdown
Member

Closing the half of this I said was unanswered.

My earlier note only covered saved traces, because the stock ladder pins every streamed reply at STREAM_TAIL_CHARS = 6,000, of which about 404 characters are reasoning at the 100K rung. The live claim here was therefore unreachable on it, and CONTRIBUTING-perf.md says so itself: a mechanism whose cost scales with reply length reads as a flat floor on this ladder.

--stream-tail-chars 110000 moves the streamed turn onto a reasoning-kind corpus unit and delivers 88,030 reasoning characters in one live reply, 5.4x the trigger, crossed 2.05s into a 13.7s stream, so both scroll_during_generation windows and keystroke sit entirely in the post-threshold region. Chromium, 100K rung, 4 reps, base 27a4ff6a^1 against head 27a4ff6a, with a concurrent base-vs-base null on adjacent pinned cores of the same NUMA node.

Two metrics cleared all three gates, and one of them is the streaming one:

metric base head delta spread floor verdict
stream_max_frame_ms 281.9 ms 73.6 ms -73.3% 12.5% 45.9% faster
reasoning_toggle.open_ms 1,582.0 ms 595.3 ms -61.9% 14.7% 43.9% faster

Everything else points the same way and does not clear its own floor, so I am not quoting it as a result: jank_index -54.0% against a 63.1% floor, max_frame_ms -32.6% against 41.6%, time_in_jank_pct -30.6% against 37.1%, stream_jank_index -3.2 against 19.0, stream_time_in_jank_pct -1.6 against 4.1. No metric regressed past its floor in either direction.

The invariants that catch this shape of change held exactly. select_all_copy.count.selected_chars reads 123,092 on both arms and clipboard_chars 122,304 on both, delta 0.0%, so bounding the mount did not truncate the copy. Behavioural parity: 0 invariants broken across 64 action pairs. Visible-region parity reports 2 differences, both reasoning_toggle, both the intended change in what is mounted.

Three things I would not want read as more than they are. The cadence is fast, 8,000 characters per second against field's 329, because at field cadence this reply takes 334s and outlasts the 243s film; that is the same accelerated-replay compromise the description above makes, though this one carries a null control and a floor. It is n=4, one rung, one engine. And reasoning_toggle opens all ten panes in one gesture, which the harness's own guide calls a stress gesture and not a user journey.

So the premise holds on both halves now, saved and live, on the venue this repo trusts.

Sign up for free to join this conversation on GitHub. Already have an account? Sign in to comment

Projects

None yet

Development

Successfully merging this pull request may close these issues.

3 participants