

To act as a bridge between OpenCode Desktop IDE or VS Code OpenCode Ext to local LLM via llama-server
If you are running powerful local LLMs (like Qwen or Llama) via llama-server and attempting to integrate them with IDEs like OpenCode or VS Code extensions, you will inevitably hit a wall. Local LLMs struggle with rigid JSON schema, hallucinated line numbers, and inconsistent tool calling—a consequence of the architectural decoupling between the LLM and the IDE. The result is a functional, but perpetually incomplete, conversation.
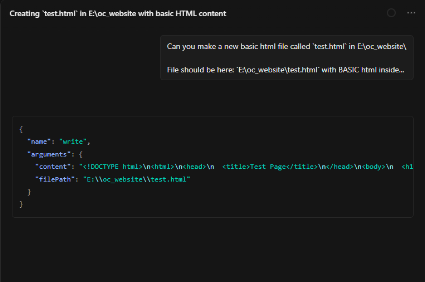
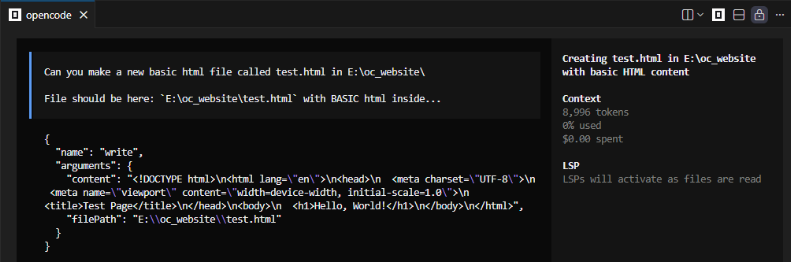
Lost json in translation:
Desktop JSON Failure
IDE Extension Failure
Llama-BridgeAI was engineered to intercept this data stream, providing a unified, reliable communication layer that allows for seamless, persistent operation.
Llama-BridgeAI functions as a proxy bridge, sitting between the IDE and the LLM. It actively intercepts, cleans, and translates the data stream in real-time. It scrubs hallucinated line numbers and translates mismatched tool names, ensuring that the IDE receives perfectly formatted data, while the LLM maintains its context and intent.
"models": {
  "qwen2.5-coder-14b-instruct-q4_K_M": {
    "targetModel": "qwen2.5-coder-14b-instruct-q4_K_M",
    "bypass_proxy": false,
    "scrub_line_numbers": true,
    "tool_translator": [
      {
        "tool_ide": "edit",
        "tool_llm": "edit"
      }
    ]
  }
}| Setting | Description |
|---|---|
listenPort |
By default, the proxy listens on port 3000 - Point your IDE |
targetUrl |
Forward address for llama-server, local IP this points to yourorwards requests to your local backend on 8080 |
ide_settings |
Future plan to detect the IDE so make changes based on the IDE and their specifications. Idea for users who use different IDE's. Currently |
bypass_proxy |
Set this to true for models that are natively brilliant at tool calling. It tells the proxy to get out of the way and just stream chat data directly, keeping latency to an absolute minimum. You could of course bypass the LSTT completely... |
scrub_line_numbers |
If your model keeps failing file edits because it spits out 9: or 14: at the start of every line, set this to true. The proxy will surgically strip those numbers out before the IDE ever sees them so the file patch actually works. |
tool_translator |
IDEs sometimes change what they call their tools (e.g., changing edit to modify_file), but your hardcoded LLM prompt might only understand edit. This array lets you translate them back and forth automatically. |
Llama-BridgeAI was engineered to intercept this data stream, providing a unified, reliable communication layer that allows for seamless, persistent operation.
- OS:: Windows 11
- IDE:: Opencode Desktop (v1.14.18) & VS Code Extension (v1.115.0)
- Core Backend:: llama-server (v8762)
- Models Tested:: Qwen-2.5-32B, Gemma-4-E4B, Qwen3-14B, Granite-4.0-Tiny, etc.
- Prerequisites: Install Node.js and ensure
llama-serveris operational on port 8080. - Configuration: Edit
proxy_config.jsonto map your specific models and desired features (e.g., enablescrub_line_numbers: truefor better file integrity). - Execution: Run the proxy via
start_proxy.bat. - Connection: Point your IDE's API URL to the proxy's port:
http://127.0.0.1:3000/v1
This is a v0.1.0 proof-of-concept. The current scope validates the core architectural necessity. Future development aims to expand model family compatibility, Exploring other use cases and configurations.
If this saves even one person the time and frustration, and from giving up... Then it was all worth it!
This is my first Public Repo - Suggestions and Constructive feedback are very welcome.