Repository navigation
Conversation


|
The remaining errors after removing the single letter cases above (keeping H) are: Now: Earlier: so a consequence of the actual characters being used. Now: Earlier: The addition of Now: Earlier: So a consequence of the combined character not being in the font. For the first, and I assume the second, case, the right thing would be to update the images. For the final case, there should be some checking if the glyph exists in the used font. |
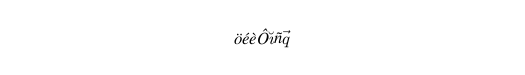
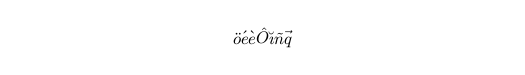

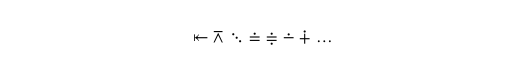

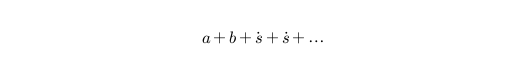

897487e to
df3add6
Compare

|
accentprefixed is being handled (removed) at #22950. |
|
@anntzer Do you know if #22950 will enable using single character accents (that is also a starting character of another LaTeX symbol)? Also, do you have any idea how one can detect if a glyph actually exists as in the ṡ turning into ¤ in the image above? (I do not think it is Matplotlib that does that substitution?) |
|
first point: yes, I think that should work. matplotlib/lib/matplotlib/_mathtext.py Lines 474 to 476 in 9e0747b |
|
Thanks! Ahh, I knew I had seen that somewhere! Grepped for ¤ though... |
df3add6 to
2529261
Compare
|
I'm wondering if one should introduce some rcParam for the replacement. If I understand it correctly, it may not be possible for the parser to actually know the exact font being used? (Only like 'rm') Edit: Inkscape was not in the path due to a reinstall...
Anyway, I am wondering if one possible should try and decompose the characters once the _get_glyph-operation fails? Example: (not relevant anymore, but may still be of interest) import unicodedata
accent = chr(775)
withcombiningaccent = 's' + chr(775)
print(withcombiningaccent , len(withcombiningaccent))
combined = unicodedata.normalize('NFC', withcombiningaccent)
print(combined, len(combined))
print(ord(combined))This shows that it correctly finds https://www.codetable.net/decimal/7777 One can do
|
|
I also replaced some of the accents with the "proper" combining accent. So this breaks another test. But avoids having to resize |
| 'combiningdiaeresis' : 776, | ||
| 'combiningtilde' : 771, | ||
| 'combiningrightarrowabove' : 8407, | ||
| 'combiningleftarrowabove' : 8406, |
There was a problem hiding this comment.
A bit of aligning required here and a few lines down.
|
Perhaps split out the addition of new accents as a separate PR, which should be fairly uncontroversial? I suspect that general handling of combining characters would basically require harfbuzz (which knows how to position an accent by itself, e.g. the classic "zalgo" text h̷̡̦͚́͛̅̔̅̊͘ě̶͚̣̭́̉͜ļ̴͚͙̝̑̒l̸̛̙̹ͅơ̵͎̻͔̯̊ ̶̨̨͖̥̺͓̽̋̒͝w̶̨̗̻̥̜͍̮̏͛͒͝o̷̟͆̍̓̚ŗ̵̢͔̦̑͗̑̑̃l̸̲̥̲̹͖̔̇̾̏͆d̴͍̲̓̄̑̉̌̇͜) + switching from bakoma to lm-math, to have access to the combining characters... Still,
I think that's actually possible? e.g. |
ce1fa41 to
e671b41
Compare

e671b41 to
9971ce1
Compare
|
You are correct that it was possible. I couldn't follow the order of things happening properly. I think that the zalgo support is actually not that much affected by this. It is just that when there are proper glyphs available these will be used, if not, it will be as before (which I guess supported zalgo to some extent). See for example the test with One may even consider consider checking if a Unicode character can be split. Anyway, this should really wait until #22950 is merged so that more accents can be added. One could also consider adding support for other combining accents, like cedilla and ogonek, which at least should work when there are available combined characters. Maybe one should have two separate groups of accents: the current ones where it is possible to "create" decently looking combinations and those like cedilla and ogonek which may have a valid combined glyph. If those doesn't work one could error if they do not combine or the glyph is not available. (I tried out to get combining accents below working, but I had some issues with aligning them correctly, especially since cedilla and ogonek should be without a gap and I didn't get that to work for e.g. p, which probably noone wants, but still...) There are now some more things changed:
|
| accent_box = AutoWidthChar( | ||
| '\\' + accent, sym.width, state, char_class=Accent) | ||
| else: | ||
| # Check if accent and character can be combined |
There was a problem hiding this comment.
One can possibly consider splitting the accents into those that may have precomposed characters and those that may not.
https://en.wikipedia.org/wiki/List_of_precomposed_Latin_characters_in_Unicode
Possibly one should check that the character is one of the standard latin characters as well, although that may lead to that those precomposed with two accents may not work (which should be checked if they even do to start with...).
|
Turns out that for some characters caron ( |


|
Since this Pull Request has not been updated in 60 days, it has been marked "inactive." This does not mean that it will be closed, though it may be moved to a "Draft" state. This helps maintainers prioritize their reviewing efforts. You can pick the PR back up anytime - please ping us if you need a review or guidance to move the PR forward! If you do not plan on continuing the work, please let us know so that we can either find someone to take the PR over, or close it. |
|
Likely to be revived, perhaps in a slightly different form, once raqm/harfbuzz lands. |
 anntzer
added
keep


PR Summary
Add support for
\check#7738 and the brief forms in https://en.wikibooks.org/wiki/LaTeX/Special_Characters (double acute is new, the others just use the standard single-letter names).In addition, replaces a character + combining accent with a single character once available as mentioned in #4561 (comment) This means that e.g.
\" inow works and is properly replaced withï.cmr10PR Checklist
Tests and Styling
pytestpasses).flake8-docstringsand runflake8 --docstring-convention=all).Documentation
doc/users/next_whats_new/(follow instructions in README.rst there).doc/api/next_api_changes/(follow instructions in README.rst there).