Repository navigation
fix(core): preserve no-argument tool calls that stream an empty arguments string - #6250
Conversation


…ents string

For tools that take no parameters, some OpenAI-compatible providers
stream `arguments: ""` (or omit the field entirely) and never send an
argument fragment. The streaming parser dropped such calls wholesale
(`meta?.name && buffer.trim()`), while the non-streaming path keeps
them with `args: {}` — so a turn containing only that call looked
empty and geminiChat raised "Model stream ended with empty response
text", triggering pointless retries.

Align the streaming parser with the non-streaming path: emit the call
with empty args when the buffer is empty at stream end. Rewrite the
unit test that encoded the drop, and add regression coverage at parser
and converter chunk level.

 doudouOUC
left a comment
doudouOUC
left a comment
There was a problem hiding this comment.
[Suggestion] buffer.trim() as occupancy signal is now inconsistent with the new empty-buffer-is-valid semantics.
getCompletedToolCalls() correctly treats empty buffers as valid no-arg tool calls, but three other methods still use buffer.trim() to decide whether a slot is "occupied":
addChunk()line ~92 — collision guardexistingBuffer.trim() &&short-circuits tofalsefor no-arg calls. A second tool call arriving at the same index silently overwrites the first.findNextAvailableIndex()line ~334 —!buffer.trim()returns a valid no-arg call's slot as "available."findMostRecentIncompleteIndex()line ~377 —!buffer.trim()classifies a valid no-arg call as "incomplete," potentially misrouting continuation chunks.
This is dormant for standard providers (OpenAI, Anthropic-via-proxy, DashScope assign unique indices per tool call), but would trigger with buggy providers that reuse indices — exactly the llama.cpp-style servers this PR targets.
Suggested fix: Replace buffer.trim() / !buffer.trim() with meta?.name / !meta?.name as the occupancy signal in all three locations:
// addChunk() line ~92:
if (existingMeta?.name && existingDepth === 0 && existingMeta?.id && existingMeta.id !== id)

// findNextAvailableIndex() line ~334:
if (!meta?.name || depth > 0 || !meta?.id)

// findMostRecentIncompleteIndex() line ~377:
if (meta?.id && (depth > 0 || (meta?.name && buffer.trim())))
And add a regression test sending two tool calls at the same index where the first has no arguments.
— qwen3.7-max via Qwen Code /review
| for (const [index, buffer] of this.buffers.entries()) { | ||
| const meta = this.toolCallMeta.get(index); | ||
| if (meta?.name && buffer.trim()) { | ||
| if (meta?.name) { |
There was a problem hiding this comment.
[Suggestion] The guard relaxation here (meta?.name only) correctly preserves empty-buffer no-arg tool calls at emission time, but three buffer.trim() checks in unchanged addChunk() code still use "has buffer content" as a proxy for "this slot is occupied by a real tool call." Now that empty buffer is a valid terminal state, those proxies break in multi-tool-call scenarios:
- Line 93 (collision detection):
existingBuffer.trim()is falsy for an empty-buffer entry, so when a second tool call arrives at the same index, the collision guard is skipped and the first call's metadata is silently overwritten. - Line 149 (replay guard):
currentBuffer.trim()is falsy, so a replayed chunk for a completed no-arg call bypasses the guard and corrupts the buffer. - Lines 121 & 345 (continuation routing +
findMostRecentIncompleteIndex):!existingBuffer.trim()classifies a completed no-arg call as "incomplete," so continuation chunks from other tool calls get misrouted to it.
None of these paths are covered by the new tests (they require multi-tool-call interleaving). The fix for all three is the same — replace buffer.trim() with a completion signal that accounts for empty-buffer entries, e.g. meta?.name && meta?.id && depth === 0.
— qwen3.7-max via Qwen Code /review
| parser.addChunk(0, ' ', 'call_1', 'function1'); | ||
|
|
||
| const completed = parser.getCompletedToolCalls(); | ||
| expect(completed).toHaveLength(1); |
There was a problem hiding this comment.
[Suggestion] This test uses weaker assertions than the empty-buffer test above (line 398). The empty-buffer test uses expect(completed).toEqual([{ id: 'call_1', name: 'function1', args: {}, index: 0 }]) (full shape), while this one only checks toHaveLength(1) and completed[0].args. It would not catch metadata corruption or wrong-index routing.
| expect(completed).toHaveLength(1); | |
| it('should return empty args for whitespace-only argument buffers', () => { | |
| parser.addChunk(0, ' ', 'call_1', 'function1'); | |
| const completed = parser.getCompletedToolCalls(); | |
| expect(completed).toEqual([ | |
| { id: 'call_1', name: 'function1', args: {}, index: 0 }, | |
| ]); | |
| }); |
— qwen3.7-max via Qwen Code /review

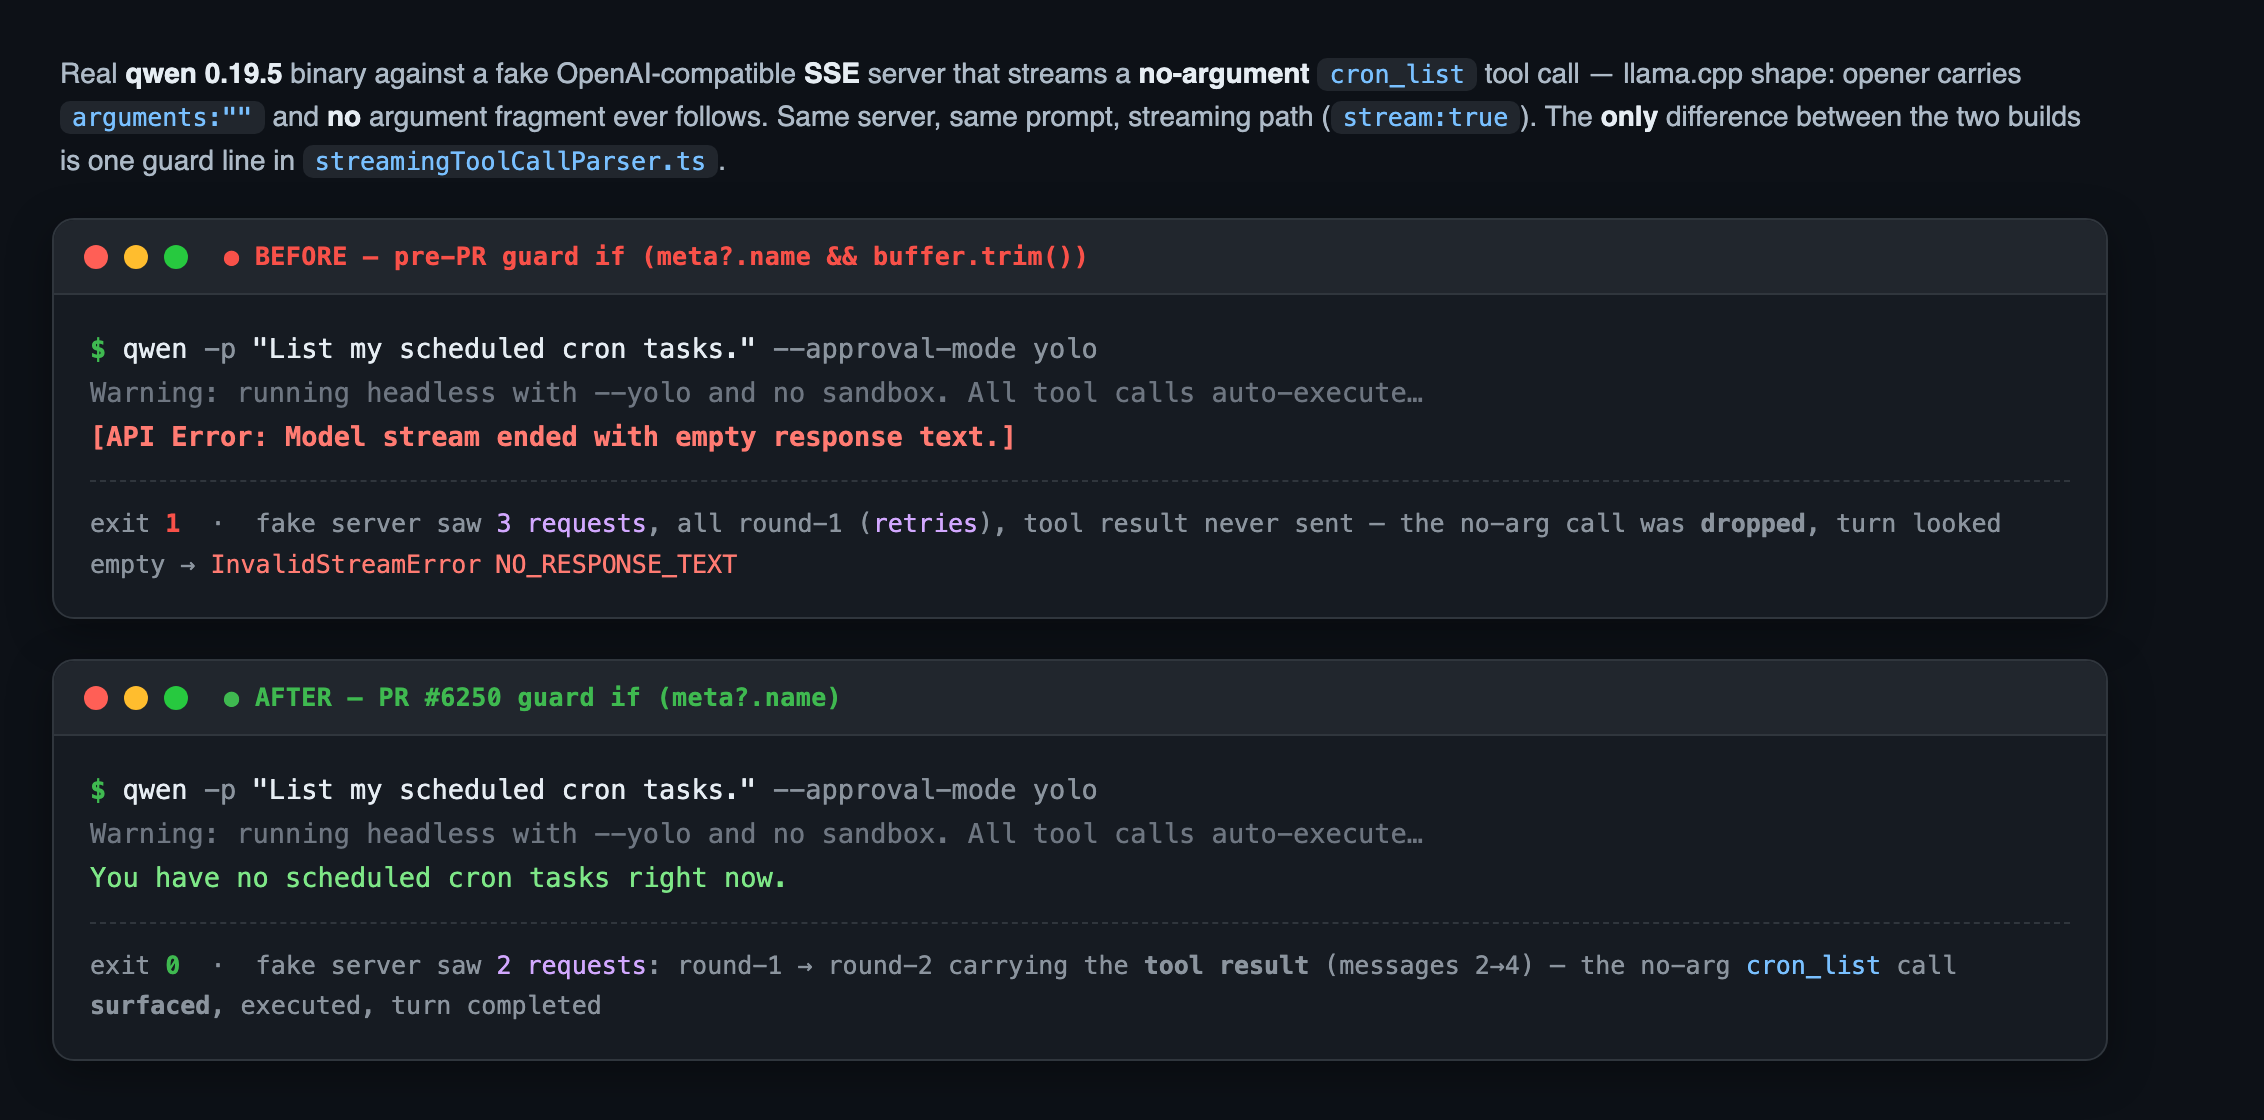
✅ Maintainer verification — local build + real-binary E2EI built this PR locally and verified it end-to-end with a real binary. The fix resolves the reported failure and is protected by load-bearing regression tests. LGTM. Scope reviewed: head Why the old behavior broke a whole turn: when the dropped call was the turn's only content, 1. Real-binary end-to-end (the actual user-facing symptom)Two bundles built from identical source except that one guard line, running the real
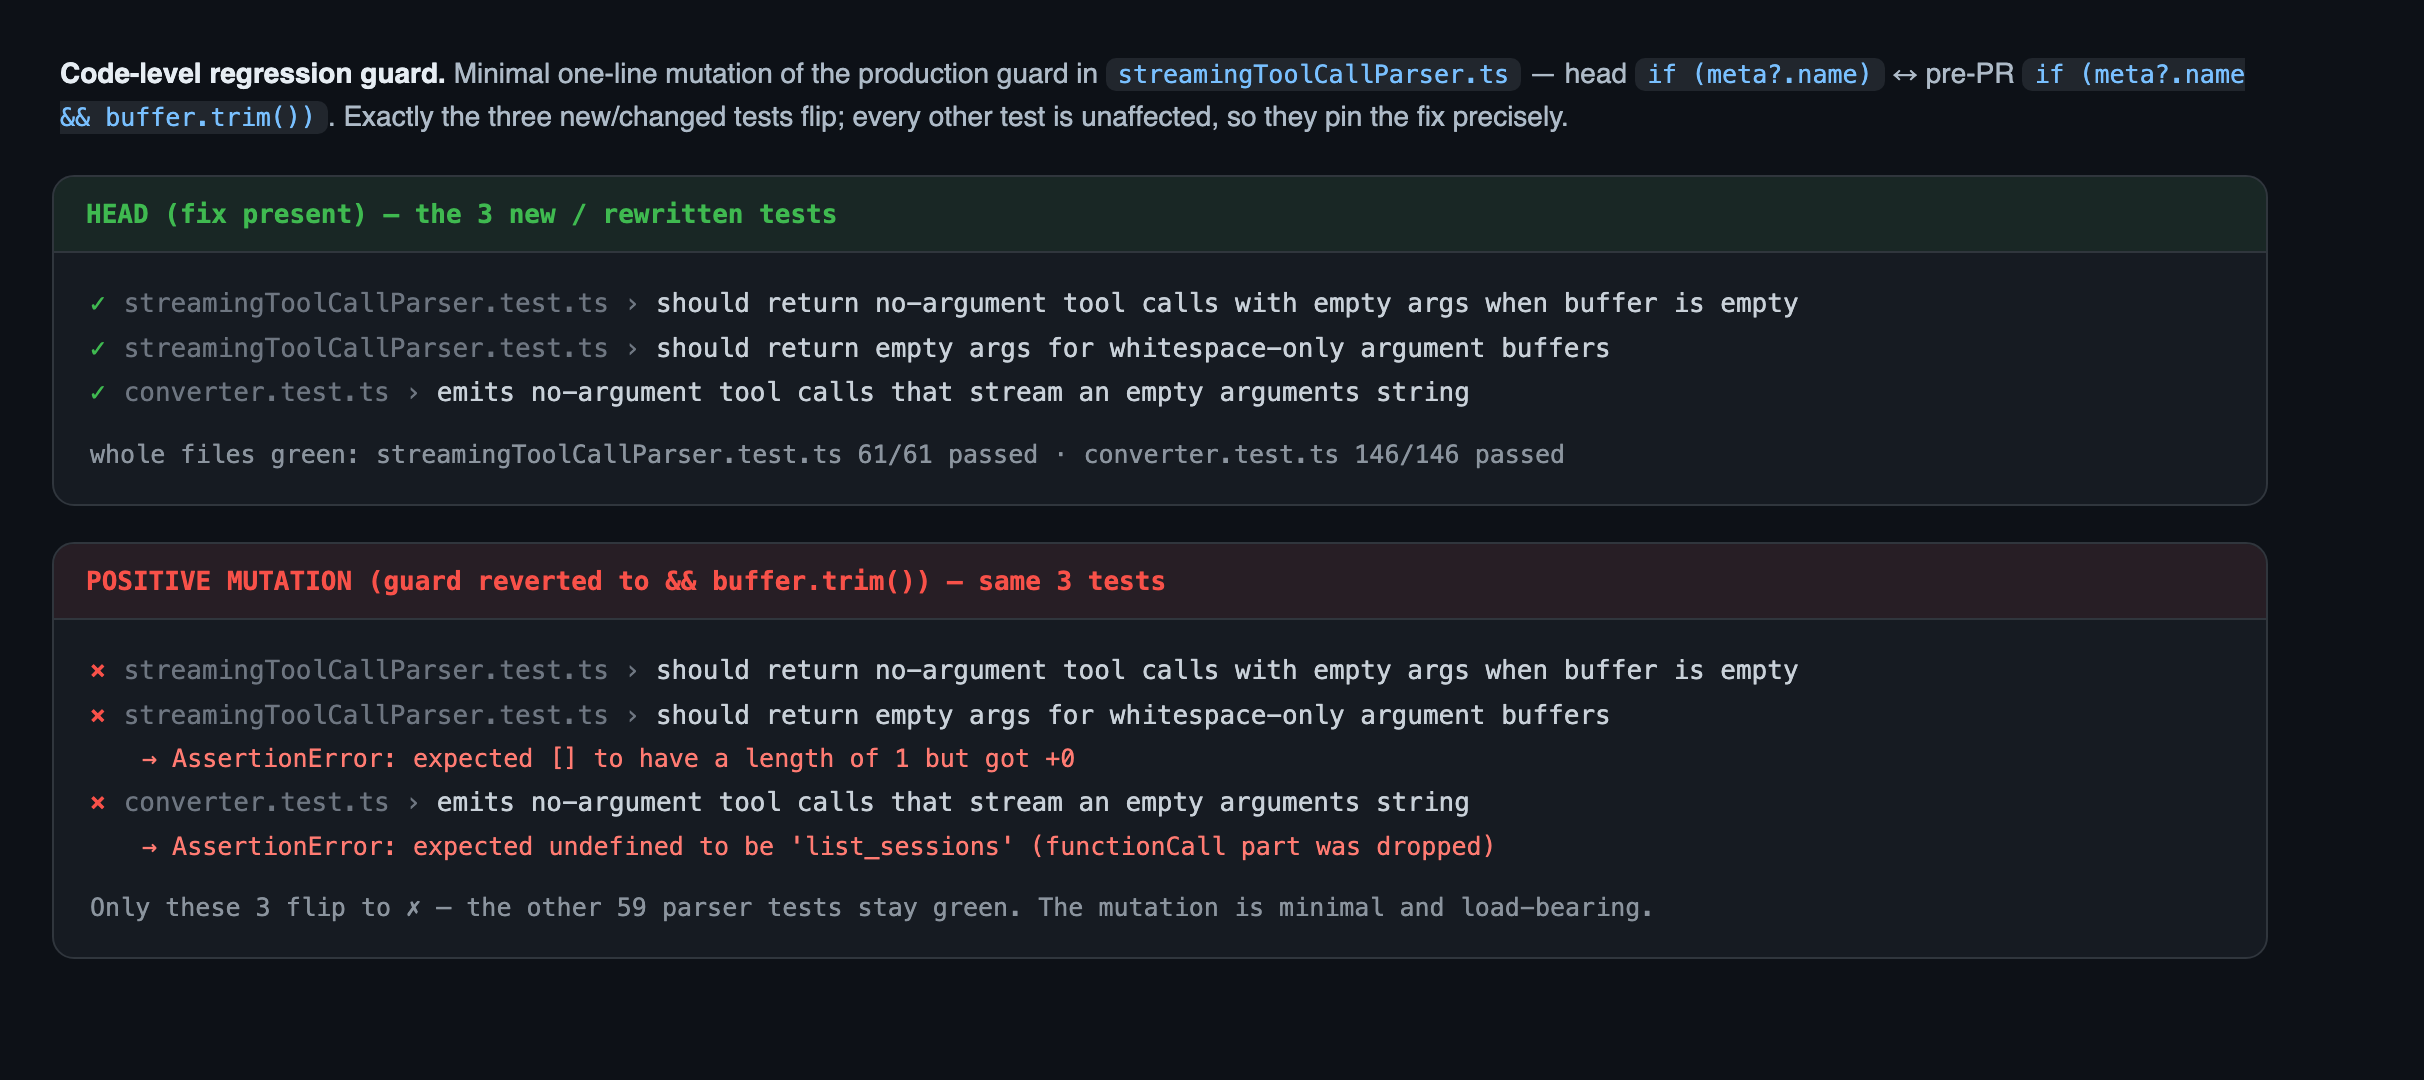
Every request had 2. Code-level regression guard (mutation A/B)At head all three new/rewritten tests pass. Reverting only the guard back to
So the tests genuinely pin the fix — a future regression would be caught. Minor nit (non-blocking)The JSDoc above Verdict✅ Correct, narrowly scoped, matches the non-streaming path, and regression-protected. No behavior change for tool calls that stream real arguments, nor for name-less / truncated calls ( Verification: worktree at PR head, 🇨🇳 中文说明(完整对应)✅ 维护者验证 —— 本地构建 + 真实二进制端到端我在本地构建了该 PR 并用真实二进制做了端到端验证。修复确实解决了所报告的故障,且有承重的回归测试保护。建议合并(LGTM)。 审阅范围: head 为什么旧行为会毁掉一整轮: 当被丢弃的调用是这一轮唯一的内容时, 1. 真实二进制端到端(真正的用户可见症状)用除那一行判定外完全相同的源码构建了两个 bundle,让真实的 (见上方英文处第一张截图)
每个请求都是 2. 代码层回归保护(变异 A/B)在 head 上三个新增/改写的测试全部通过。只把那行判定改回 (见上方英文处第二张截图) 说明这些测试真正"钉住"了修复——将来若回归会被抓到。 小瑕疵(不阻塞)
结论✅ 修复正确、范围收敛、与非流式路径对齐、且有回归保护。对流式返回真实参数的工具调用、以及无名称/被截断的调用均无行为变化( 验证方式:在 PR head 建 worktree, |

|
Hi @tomsen-ai — thanks for picking this up. The bug is real, the fix direction is right, and the regression tests look good. Before merging, could you take another pass at @doudouOUC's review comment above? The concern is that this PR relaxes the completion gate in
This is dormant on OpenAI / Anthropic / DashScope (unique index per tool call), but the PR description explicitly calls out llama.cpp-style servers — exactly the class of provider most likely to reuse indices. Suggested fix (from the review): switch the occupancy signal from Happy to take this over if you're busy — just say the word. |


… tool calls

Follow-up to review feedback: after empty buffers became a legal end
state for no-argument tool calls, three parser methods still used
buffer.trim() to decide whether an index slot was occupied. A provider
reusing indices could then silently overwrite a completed no-argument
call (addChunk collision guard, findNextAvailableIndex) or append stray
continuation chunks to it (findMostRecentIncompleteIndex).

Switch the occupancy signal in all three places to the name metadata,
keeping the JSON-completeness check for non-empty buffers. Add
regression tests for both corruption paths and update the stale
getCompletedToolCalls JSDoc.

Co-Authored-By: Claude Fable 5 <[email protected]>


|
Thanks @wenshao for the thorough verification, and @doudouOUC for catching the occupancy inconsistency — the concern is real, and it's addressed in 0d2b91d. All three spots now use name metadata as the occupancy signal, with two deviations from the literal snippets in the review, both needed for the fix to actually take effect:
One Regression tests added for both corruption paths:
Mutation check: reverting only Also fixed the stale |
 wenshao
left a comment
wenshao
left a comment
There was a problem hiding this comment.
[Critical] streamingToolCallParser.ts:130 — Missing !meta?.name guard in no-ID continuation routing
The PR correctly updated three of four sites that used !buffer.trim() as the "incomplete call" signal to also check !meta?.name. But the inline continuation branch in addChunk() at line ~130 was missed:
// Line 130 — NOT updated (still uses old guard)
if (existingDepth > 0 || !existingBuffer.trim()) {
  actualIndex = index;
Compare with the correctly updated findMostRecentIncompleteIndex (line 383):
if (meta?.id && (depth > 0 || (!buffer.trim() && !meta?.name))) {A continuation chunk (no ID) arriving at the index of a completed no-arg call enters the !existingBuffer.trim() branch and is appended to the completed call, corrupting its buffer. The in-progress call that should receive the chunk is starved. Two tool calls corrupted simultaneously.
Fix — mirror the name-guard from findMostRecentIncompleteIndex:
const existingMeta = this.toolCallMeta.get(index);
if (existingDepth > 0 || (!existingBuffer.trim() && !existingMeta?.name)) {
  actualIndex = index;
Test gap — The existing test "should not route continuation chunks to a completed no-argument tool call" sends the continuation at index 2 (a completed call with non-empty buffer → JSON.parse branch → findMostRecentIncompleteIndex), never exercising this still-broken inline path. A test that would catch this:
parser.addChunk(0, '{"key":', 'call_1', 'function1');
parser.addChunk(1, '', 'call_2', 'no_arg_function');
parser.addChunk(1, '"value"}'); // continuation at no-arg call's OWN index
// Assert: no_arg_function still has args: {}, function1 gets {key: "value"}
— qwen3.7-max via Qwen Code /review
Suggestions — commit
|
| File | Issue | Suggested fix |
|---|---|---|
streamingToolCallParser.ts:95,167,379 |
"Is this slot complete?" check is implemented inline in three locations (collision detection, replay guard, findNextAvailableIndex) with slightly different formulations — the line 130 oversight is a direct consequence of this duplication |
Extract a private isSlotComplete(index: number): boolean helper and call it from all three sites. The helper would return `meta?.name && depth === 0 && (!buffer.trim() |
— qwen3.7-max via Qwen Code /review
…ical empty-opener shape

Review follow-up on the no-ID continuation routing at addChunk. Mid-stream,
an empty buffer with name metadata is formally undecidable between "completed
no-argument call" and "canonical opener awaiting its first argument fragment"
(every OpenAI-compatible provider opens with arguments:"" and streams
fragments ID-less at the same index). Routing must favor the canonical shape,
so the guard stays; a new test pins that shape, which the suite previously
did not cover.

The corruption concern from review is instead bounded at emit time: a buffer
polluted by a stray fragment can parse or repair to a non-object value, which
now collapses to {} so a polluted no-argument call still emits empty args.

Co-Authored-By: Claude Fable 5 <[email protected]>
… argument collapse

Review follow-up: a stray fragment that happens to parse as a valid JSON
object is indistinguishable from real arguments at emit time, so log both
the non-object collapse and empty-buffer emissions to aid diagnosis.

Co-Authored-By: Claude Fable 5 <[email protected]>
|
Thanks for the careful second pass. Before changing anything I ran an empirical A/B on the Critical, and the result is that line ~130 cannot take the name-guard — but the concerns behind both findings are real, and a5db830 + f1efd7f address them at the layer where they are addressable. Evidence below. 1. The suggested edit does not change the routing outcomeWith the suggested condition, an ID-less chunk arriving at a completed no-arg call's index skips the first branch — but then enters the 2. The version that would change routing breaks the canonical streaming shapeTo make the proposed test pass, an empty buffer with name metadata must be treated as complete and routed away via parser.addChunk(0, '', 'call_1', 'function1'); // canonical opener
parser.addChunk(0, '{"x":'); // ID-less fragment — misrouted under route-away
parser.addChunk(0, '1}');Notably, the existing suite never pinned this shape — which I suspect is why route-away looked viable. a5db830 adds the lock test. The underlying issue: at this code point, "completed no-argument call" and "opener awaiting its first fragment" are formally indistinguishable; only stream end resolves them. Routing has to favor the canonical case — the pathological one (a provider reusing a completed call's index for another call's ID-less fragment) requires the provider to already be violating index semantics, at which point fragment ownership is unknowable under any policy. 3. What I did take from the Critical: bounding the damageThe A/B surfaced a real secondary bug in the pathological case: the polluted buffer 4. Replay guard at line ~157Same structure as §1: for an empty buffer, the suggested condition enters the guard, 5. Valid-object pollution (latest suggestion)Agreed — a stray fragment that parses as a valid JSON object is indistinguishable from real arguments at emit time, and logging is the only detector. f1efd7f adds debug logging for both the non-object collapse and empty-buffer emissions. Happy to adjust if there's a routing policy I've missed — but I couldn't find an edit at line ~130 that helps the pathological case without breaking the canonical one, and the canonical one is every provider's every multi-fragment tool call. |
…t tool calls

Review follow-up: after empty buffers became a legal completed state, a
replayed opener (duplicate ID, QwenLM#5107 lineage) could overwrite a completed
no-argument call's name metadata, since the replay guard only engaged on
non-empty buffers.

Swallowing every known-ID chunk at that state would drop ID-bearing
argument fragments for providers whose opener streams empty arguments, so
the guard uses the protocol shape as discriminator: a chunk carrying a
name but no argument content is an opener replay and is ignored; a chunk
with argument content is a continuation and appends. Regression tests
cover both directions.

Co-Authored-By: Claude Fable 5 <[email protected]>
|
Good catch this round — the invariant is right and I've adopted it, with one scope adjustment grounded in the delta protocol. Details: The finding is real. After empty buffers became a legal completed state, a replayed opener (duplicate ID — the #5107 pathology this guard was built for) could indeed overwrite a completed no-argument call's But the proposed swallow drops legitimate fragments. I applied the suggested implementation verbatim: it passes its own regression test and the existing suite — and silently swallows ID-bearing argument fragments after an empty opener: parser.addChunk(0, '', 'call_1', 'function1'); // canonical empty opener
parser.addChunk(0, '{"x":1}', 'call_1'); // known-ID continuation — swallowed, args lostProviders that repeat the tool-call ID on argument fragments exist, and under the swallow their with-args calls execute with The protocol itself offers the discriminator. An opener-shaped replay carries a Residual ambiguity, stated for the record: a known-ID chunk carrying both a name and argument content is indistinguishable between a name-repeating provider's fragment and a content-carrying duplicate opener. The guard appends — consistent with its original design, which also appends to unparseable buffers — and the emit-time non-object collapse plus the debug logging from f1efd7f bound and surface the residual case. |
…ion scan

Review follow-up: pin the null and array branches of the emit-time
non-object collapse, and exercise findNextAvailableIndex scanning past
multiple occupied no-argument slots during collision relocation.

Co-Authored-By: Claude Fable 5 <[email protected]>
|
Both coverage gaps addressed in 852e763: the null and array branches of the emit-time collapse are now pinned, and the relocation test stacks two no-argument calls so |
|
@wenshao All review rounds are now addressed — 096eea5 adopts the replay-guard invariant with the protocol-scoped implementation (opener-shaped replays ignored, ID-bearing argument continuations preserved), and 852e763 closes the remaining coverage gaps. 70/70 parser + 146/146 converter tests green at head. Ready for your re-review whenever convenient. |
| // Check if this tool call is incomplete. An empty buffer counts only | ||
| // while no name has arrived: with name metadata it is a complete | ||
| // no-argument call, and stray chunks must not be appended to it | ||
| if (meta?.id && (depth > 0 || (!buffer.trim() && !meta?.name))) { |
There was a problem hiding this comment.
[Critical] Same !meta?.name guard applied here but missed at line 130 (no-ID continuation fast-path)
The PR correctly updated three of four sites that used !buffer.trim() as the "incomplete call" signal to also check !meta?.name — here, findNextAvailableIndex (~line 379), and the replay guard (~line 167). But the no-ID continuation fast-path at line 130 was not updated:
// Line 130 (unchanged by this PR, not in diff):
if (existingDepth > 0 || !existingBuffer.trim()) {
  actualIndex = index;
A completed no-argument call has depth=0, buffer="", so !existingBuffer.trim() short-circuits to actualIndex = index. A stray no-ID continuation chunk arriving at that index gets appended to the completed call instead of being routed through findMostRecentIncompleteIndex. The non-object collapse guard in getCompletedToolCalls catches non-object pollution, but a stray chunk forming a valid JSON object (e.g. {"x":1}) passes through undetected — emitting wrong args for the no-arg call while the intended target call stalls with truncated args.
The canonical-shape test (should route ID-less argument fragments to a call whose opener streamed empty arguments) still passes with this fix because findMostRecentIncompleteIndex correctly handles the routing.
Suggested fix (at line 130):
const existingMeta = this.toolCallMeta.get(index);
if (existingDepth > 0 || (!existingBuffer.trim() && !existingMeta?.name)) {
  actualIndex = index;
— qwen3.7-max via Qwen Code /review
|
@qwen-code /triage |
Maintainer verification — real end-to-end test on Linux 🐧I built this PR locally and drove it end-to-end through a mock OpenAI‑compatible SSE server (llama.cpp wire shape) under
1) Live E2E — the exact symptom from #6249, reproduced and fixedMock server streams a single no‑argument BEFORE — AFTER — PR #6250 (fix applied): the no‑arg call survives with
2) Standalone parser harness (outside vitest, on the real source)The issue's deterministic repro plus the corruption edge cases, driven through the compiled parser via The 3 shared‑pass rows confirm the harness isn't vacuously failing — it's precisely the no‑argument behaviors that changed. 3) Unit before/after (the PR's own claim)Reverting only the production file to 4) Re‑verification of my earlier [Critical] (line 129, name‑guard in no‑ID continuation routing)I re‑ran my exact scenario on the current HEAD and compared against Findings, stated plainly:
Net: my [Critical]'s worry ("no‑arg call corrupted") does not materialize — the no‑arg call is safer than before, and the residual (a starved sibling under a non‑canonical stream) is truncation‑flagged and no worse than Notes / caveats
RecommendationVerified — the fix correctly resolves #6249 end‑to‑end on Linux, with no regression in the pathological path my [Critical] targeted (in fact an improvement over 中文版本(点击展开)维护者验证 —— Linux 本地真实端到端测试 🐧我在本地拉取并构建了本 PR,用一个模拟 OpenAI 兼容的 SSE 服务器(llama.cpp 的报文形状),在
1)真实 E2E —— 复现并修复 #6249 的确切症状模拟服务器以 llama.cpp 方式流式返回一个无参 修复前 —— 修复后 —— PR #6250: 无参调用以
2)独立解析器 harness(脱离 vitest,直接跑真实源码)将 issue 的确定性复现 + 若干损坏边界,用 3)单测前后对比(PR 自身声明)仅把生产文件回退到 4)对我此前 [Critical](line 129,无 ID 续传路由缺少 name 守卫)的复验我在当前 HEAD 上重跑了我给出的确切场景,并与 结论,直说:
综上: 我 [Critical] 担心的"无参调用被损坏"并未发生 —— 无参调用比之前更安全,剩余情形(非规范流下同批次的兄弟调用被饿死)已被截断标记,且不比 备注 / 说明
建议已验证 —— 该修复在 Linux 上端到端正确解决了 #6249,且在我 [Critical] 针对的病态路径上没有回归(反而优于 |


What this PR does
Makes the streaming tool-call parser emit tool calls whose arguments buffer is empty at stream end (as
args: {}) instead of silently dropping them, matching the non-streaming conversion path. Rewrites the unit test that encoded the old drop behavior, and adds regression tests at parser level and converter chunk level.Why it's needed
For tools that take no parameters, some OpenAI-compatible providers stream
arguments: ""(or omit the field entirely) and never send an argument fragment — llama.cpp's server, for example, omitsargumentswhen empty and never synthesizes"{}". Today the streaming parser drops such calls wholesale (if (meta?.name && buffer.trim())), while the non-streaming path keeps them withargs: {}. When the turn contains only that tool call, the whole turn looks empty and the client raisesInvalidStreamError: Model stream ended with empty response text., triggering pointless retries. Qwen Code's own built-in no-argument tools (task_list,cron_list,enter_plan_mode) are in the blast radius.Fixes #6249
Reviewer Test Plan
How to verify
cd packages/core && npx vitest run src/core/openaiContentGenerator/— includes the new regression tests: the parser emits an empty-args call (the old test asserted the drop), and the converter chunk path delivers afunctionCallwithargs: {}.main, the new parser testshould return no-argument tool calls with empty args when buffer is emptyfails withexpected [] to have a length of 1; on this branch it passes. Fullnpm run preflightis green.{name: "task_list", arguments: ""}+finish_reason: "tool_calls"(script shared in Streaming tool calls with an emptyargumentsstring are silently dropped, causing "Model stream ended with empty response text" retry loops #6249). Before: API error + identical retry requests. After: the tool call surfaces and executes, the conversation completes.Evidence (Before & After)
Same mock server (streams a no-arg
task_listcall, llama.cpp-style), same prompt:Before (v0.19.5):
After (this branch):
Tested on
Risk & Scope
Low risk, narrow scope: one guard relaxed in
streamingToolCallParser.ts(production code), everything else is tests. Behavior changes only for tool calls whose arguments buffer is empty at stream end — previously dropped (then surfacing as a fake "empty response" error with retries), now emitted withargs: {}like the non-streaming path. Tool calls with a missing/unknown name are still filtered out, and truncation detection (hasIncompleteToolCalls) is unaffected since an empty buffer has depth 0. No API/config surface changes.Linked Issues
argumentsstring are silently dropped, causing "Model stream ended with empty response text" retry loops #6249中文说明
本 PR 做了什么:流式工具调用解析器在收流结束、参数缓冲为空时,不再整体丢弃该工具调用,而是以
args: {}正常发出,与非流式转换路径(converter.ts)行为对齐。同时把原先固化"丢弃"行为的单测改写为新语义,并在 parser 层和 converter chunk 层补充回归测试。为什么需要:对无参数工具,部分 OpenAI 兼容服务端会以
arguments: ""收尾且不再发送任何参数分片(如 llama.cpp 在参数为空时会完全省略该字段)。此时整轮回复看起来既无文本也无工具调用,客户端抛出Model stream ended with empty response text并无意义地自动重试。Qwen Code 内置的无参工具(task_list、cron_list、enter_plan_mode)均在影响范围内。风险与范围:低风险、窄范围——生产代码仅放宽一个判定条件;无名称的工具调用仍会被过滤;截断检测不受影响;无 API/配置面变化。