Skip to content

fix(core): share compression cache for equivalent model selectors - #15318

Merged
wenshao merged 8 commits into
QwenLM:mainfrom
xxwtiancai:fix/15197-equivalent-compaction-cache
Nov 8, 2026
Merged

wenshao merged 8 commits into
QwenLM:mainfrom
xxwtiancai:fix/15197-equivalent-compaction-cache

Conversation

@xxwtiancai

@xxwtiancai xxwtiancai commented Oct 23, 2026 •

Copy link
Copy Markdown
Contributor

What this PR does

Explicitly selecting the current model for compaction keeps the existing cache-sharing eligibility when the resolved model, auth type and exact endpoint are unchanged. The cache gate and its diagnostic now use the same existing route comparison as compression sizing. Different routes retain the cold path, and the settings documentation explains the eligibility boundary.

Full preflight is incomplete; the validation limits and upstream control results are recorded below.

Why it's needed

The model picker saves provider-qualified selections. Comparing those selections directly with the bare main-model ID sent equivalent selections down the cold summarizer path, even when the send layer returned the exact same generator and configuration. This change restores prefix-sharing eligibility; it does not promise provider cache hits or latency/cost savings.

Reviewer Test Plan

How to verify

Use a cache-supported provider, an authoritative provider-reported prompt-token count, and sufficient context space. Compare default and bare selections with an explicitly qualified current-model selection and a matching endpoint pin. All four should attempt the shared request and preserve the main system instruction, tool declarations and history. Changing the model, auth type or endpoint must remain cold. Existing missing/estimated usage, disabled cache, insufficient headroom, payload overflow, cancellation and shared-request fallback cases should remain unchanged.

Evidence (Before & After)

Source-level reproduction against upstream main 8666ab091f765e294da86b5b2b15abbec0270982 called real compression logic with controlled Config accessors and deterministic model I/O. Separate real-resolver controls confirmed exact generator/config identity for the equivalent selectors.

Selection Before: shared / cold After: shared / cold
Default or bare main model 1 / 0 1 / 0
Qualified same model and auth 0 / 1 1 / 0
Qualified selector with matching endpoint pin 0 / 1 1 / 0
Different model, auth type or endpoint 0 / 1 0 / 1

The integrated seven-case regression matrix failed exactly the two affected selectors before the production change. Afterward, 288 focused compression/client/side-query tests passed. Independent Astra xhigh verification reran those suites and the original ten-case reproduction/resolver controls: 298 tests passed. Independent review found no issues. Root build, bundle, typecheck, focused ESLint and Prettier checks passed. The built CLI version smoke test returned 0.26.0. The preflight attempt completed clean install, formatting, repository lint, build and typecheck. The final serve-bundle check also passed. Outside-sandbox workspace testing completed four workspaces (3571 passed); partial CLI output recorded 17,424 passed, 33 failed and 107 skipped before the run was stopped after confirmed host/runtime defects. All 33 failures reproduce with identical test names on pristine upstream (844 passed, 33 failed, 2 skipped in those eight files). The script stage completed its pinned Node/Bun matrices and then reported 3346 passed, 2 failed and 79 skipped; both failures also reproduce upstream. Remaining CLI files and subsequent workspace suites are unrun. Full preflight is not green.

N/A for a visual demo: this change affects an internal request path. No interactive or live-provider run is claimed; global qwen was unavailable, so the repository-permitted test-script fallback was used.

Tested on

OS Status
macOS arm64 Focused validation passed; full preflight incomplete
Windows Not tested
Linux Not tested

Environment

Node.js 24.7.0, pnpm 11.24.0, Vitest 3.2.7. Validation is tied to the reviewed patch on base 8666ab091f765e294da86b5b2b15abbec0270982. At the pre-publication check, main 23ddc5abb26bec32aad918e82b5faa0372f14c06 had no changes to the three touched files or the reviewed source/policy dependencies; this PR preserves the tested base. Verified with preinstalled Command Line Tools Git 2.54.0. The system Git wrapper remains license-gated and is still reached by fixtures that omit PATH. Bash 3.2 lacks mapfile, and Node 24.7 fails a standalone symlink-deletion probe. No agreement or system setting was changed.

Risk & Scope

  • Main risk: newly eligible equivalent selectors use the existing shared-request path, including its existing validation, accounting and one-time cold fallback.
  • Not validated / out of scope: live-provider cache-hit rates, latency/cost savings, new selector grammar or URL normalization, and separate compression-budget/restoration work.
  • Breaking changes / migration notes: none; existing qualified settings gain the intended eligibility without rewriting them.

Linked Issues

Fixes #15197.

中文说明

本 PR 做了什么

当解析后的模型、认证类型和精确端点保持不变时,显式选择当前模型作为压缩模型仍保留原有的缓存共享资格。缓存门控及其诊断信息复用压缩预算已有的路由判定。不同路由继续使用冷路径,设置文档也说明了这一边界。

完整 preflight 尚未完成,下文明确列出验证限制及未修改上游的对照结果。

为什么需要

模型选择器保存带提供商限定的选择值。原来将其与主模型的裸 ID 直接比较,导致等价选择进入冷摘要路径,即使实际发送层返回完全相同的生成器和配置对象。本改动恢复前缀共享资格,不保证提供商缓存命中,也不主张延迟或费用收益。

审阅测试计划

如何验证

使用支持缓存共享的提供商、提供商真实上报的输入 token 锚点和充足上下文空间。比较默认值、主模型裸 ID、限定了认证类型的当前模型选择和带匹配端点 pin 的选择。这四种情况都应尝试共享请求,保留主系统指令、工具定义及历史。改变模型、认证类型或端点时应继续使用冷路径。已有的缺失/估算 usage、禁用缓存、上下文空间不足、载荷溢出、取消及共享请求失败降级行为应保持不变。

证据(修改前后)

在上游 main 8666ab091f765e294da86b5b2b15abbec0270982 上进行源码级复现:使用受控 Config 访问器和确定性模型 I/O 调用真实压缩逻辑。另以真实解析器确认等价选择返回完全相同的生成器和配置对象。

选择 修改前:共享 / 冷路径 修改后:共享 / 冷路径
默认值或主模型裸 ID 1 / 0 1 / 0
相同模型与认证的限定选择 0 / 1 1 / 0
带匹配端点 pin 的限定选择 0 / 1 1 / 0
不同模型、认证类型或端点 0 / 1 0 / 1

新增的七项回归矩阵在修改生产代码前仅有两个目标选择失败。修改后,压缩、客户端及 side-query 三个目标套件的 288 项测试通过。独立 Astra xhigh 验证重新执行了这些套件及原始十项复现/解析器控制,共 298 项通过;独立审查未发现问题。全仓 build、bundle、typecheck、目标 ESLint 及 Prettier 检查通过,构建后的 CLI 版本检查输出 0.26.0。preflight 尝试已完成干净安装、格式化、全仓 lint、build 和 typecheck,最终 serve-bundle 检查也通过。沙箱外完成四个工作区共 3571 项测试;CLI 部分输出记录 17,424 项通过、33 项失败、107 项跳过,在确认宿主运行时问题后停止。全部 33 项失败都在未修改的上游源码中以相同测试名称复现(对应八个文件共 844 项通过、33 项失败、2 项跳过)。脚本阶段的固定 Node/Bun 矩阵通过,随后脚本测试共 3346 项通过、2 项失败、79 项跳过;两项失败也在上游复现。剩余 CLI 文件及后续工作区套件未运行,不将完整 preflight 称为全绿。

可视化演示不适用:本改动涉及内部请求路径。不主张交互式或真实提供商验证;由于没有全局 qwen,使用仓库允许的测试脚本降级复现。

测试环境

系统 状态
macOS arm64 目标验证通过;完整 preflight 未完成
Windows 未测试
Linux 未测试

Node.js 24.7.0、pnpm 11.24.0、Vitest 3.2.7,验证基于 8666ab091f765e294da86b5b2b15abbec0270982 上的已审查补丁。提交前核查的主线 23ddc5abb26bec32aad918e82b5faa0372f14c06 未修改本次三个文件及已审查的源码/规则依赖,本 PR 保留经过测试的基线。使用预装的 Command Line Tools Git 2.54.0 验证。不传 PATH 的测试夹具仍会调用受 Xcode 许可限制的系统 Git 包装器。Bash 3.2 缺少 mapfile,Node 24.7 的独立符号链接删除探针也失败。未接受协议,也未修改系统设置。

风险与范围

  • 主要风险:新增符合资格的等价选择进入现有共享请求路径,沿用其验证、计费及一次冷路径降级。
  • 未验证/范围外:真实提供商的缓存命中率、延迟/费用收益、新的选择器语法、URL 归一化,以及独立的压缩预算/恢复改动。
  • 破坏性变更/迁移说明:无;现存限定设置无需改写即可获得预期资格。

关联 Issue

Fixes #15197。

@github-actions github-actions Bot added the review/self-reported The linked issue was opened by the PR author (self-reported) label Oct 23, 2026
@xxwtiancai
xxwtiancai marked this pull request as ready for review October 24, 2026 00:45
@qwen-code-review-bot

qwen-code-review-bot commented Oct 24, 2026 •

Copy link
Copy Markdown
Collaborator

✅ Qwen Triage finished — view run. See the stage comments in this thread for the result.

✅ Qwen Triage 已完成 —— 查看运行。结果见本线程中的各阶段评论。

@qwen-code-review-bot

Copy link
Copy Markdown
Collaborator

Thanks for the PR — and for filing #15197 first with the reproduction attached. That is the right order, and it made this gate quick to run.

Template looks good ✓ — every required heading is present, including the Chinese section.

Problem: observed, not theoretical. #15197 carries an executed source-level reproduction that calls the real ChatCompressionService.compress() and holds every input constant except the selector: test-model gets 1 shared / 0 cold, while openai:test-model and openai:test-model\0https://same.invalid/v1 get 0 shared / 1 cold — with a separate control confirming resolveForModel hands back the identical generator and config objects for all three. The issue's own caveat (no real-provider cache hit, latency, or cost measured) is about the size of the benefit, not about whether the route divergence happens. It happens.

Direction: aligned, and the codebase already agrees with it. sideQueryOnMainRoute has driven compression budget sizing since #13432/#13876, so base already treats openai:test-model as the main route when picking a window — the cache gate was the lone holdout still comparing raw strings, and the two checks disagreed about the same value inside one function. docs/design/chat-compression-cache-sharing.md puts the boundary at cache identity ("Sessions using a distinct compaction model stay on the existing path because their cache identity differs"), not at selector spelling, so this makes the implementation match the stated design rather than adding a new rule.

Size: core path touched (packages/core/src/services/**). Production logic 12 lines (5 in chatCompressionService.ts, 7 docs), tests 63, generated/schema 0. Well under both the 500-line escalation and the 1000-line advisory — no maintainer escalation on size.

Approach: this is the minimal change, and it matches what I would have written from the title alone. Reusing the existing predicate instead of introducing a second identity scheme is the right instinct — a new normalizer here would have given the function two competing notions of "same route". Deleting usesMainModel outright rather than OR-ing it in is also right, since the predicate subsumes it. No drive-by refactors or unrelated edits. The settings.md paragraph earns its place: the eligibility boundary is something a user can hit from the picker.

Risk: no high-risk path match (Stage 1e clean). The real risk here is evidentiary rather than structural, and I want to flag it up front because it decides what happens next: the fork CI is sitting at action_required, so none of Qwen Code CI, tui-parity, or Managed Agent gate has executed on 0b62b93e. There is no test evidence for this change yet, and the PR body itself says "Full preflight is not green." A maintainer has to approve the workflow run before those 63 new test lines have been executed anywhere.

Moving on to code review. 🔍

中文说明

感谢贡献——也感谢先提交 #15197 并附上复现。这个顺序是对的,也让本次准入检查很快就能完成。

模板完整 ✓——所有必需小标题都在,包含中文部分。

问题: 是已观测到的 bug,不是理论性加固。#15197 附上了已执行的源码级复现:调用真实的 ChatCompressionService.compress(),除选择器外所有输入保持不变——test-model 得到 1 次共享 / 0 次冷路径,而 openai:test-model 和 openai:test-model\0https://same.invalid/v1 得到 0 次共享 / 1 次冷路径;另有对照实验确认这三种选择器下 resolveForModel 返回的是完全相同的 generator 与 config 对象。issue 自己声明的限制(未测量真实提供商的缓存命中、延迟或费用)说的是收益大小,而不是路由分歧是否发生。分歧确实发生。

方向: 对齐,而且代码库本身已经认同这个方向。自 #13432/#13876 起,sideQueryOnMainRoute 就一直在决定压缩预算的窗口选择,也就是说 base 在选窗口时已经把 openai:test-model 当作主路由——只有缓存门控还在做裸字符串比较,同一个函数里两处判断对同一个值给出了不一致的结论。docs/design/chat-compression-cache-sharing.md 把边界定在缓存身份上("使用不同压缩模型的会话仍走原有路径,因为其缓存身份不同"),而不是选择器的拼写形式。因此本改动是让实现回到既定设计,而不是新增规则。

规模: 触及核心路径(packages/core/src/services/**)。生产逻辑 12 行(chatCompressionService.ts 5 行,文档 7 行),测试 63 行,生成/schema 0 行。远低于 500 行升级阈值和 1000 行大 PR 建议阈值——不因规模触发维护者升级。

方案: 这是最小改动,也和我仅看标题时会写的方案一致。复用既有判定谓词、而不是引入第二套身份方案,是正确的取舍——在这里新写一个归一化函数会让同一个函数里出现两种互相竞争的"同一路由"定义。直接删除 usesMainModel 而不是用 OR 保留它也是对的,因为该谓词已经涵盖其语义。没有顺手重构或无关改动。settings.md 那段文档是有价值的:这条资格边界用户确实可能在选择器里碰到。

风险: 未命中高风险路径(Stage 1e 干净)。这里真正的风险是证据层面的,而非结构层面的,我想先说明,因为它决定后续走向:fork 的 CI 处于 action_required,因此 Qwen Code CI、tui-parity、Managed Agent gate 都没有在 0b62b93e 上真正执行过。这个改动目前没有任何测试证据,PR 正文自己也写了"完整 preflight 未通过"。需要维护者批准 workflow 运行,这 63 行新测试才算真正被执行过。

进入代码审查 🔍

— Qwen Code · qwen3.8-max-2026-09-02

Reviewed at 0b62b93ecb1484f1e741f76347562d8d298bf3d5 · re-run with @qwen-code /triage

@qwen-code-review-bot

Copy link
Copy Markdown
Collaborator

Code review

Independent proposal first. From the title and the "why" alone, before reading the diff: the picker persists provider-qualified selectors, the gate compares them against a bare model ID, so the fix has to compare resolved routes rather than strings — and the authority on when a selector maps back to the main generator is the send layer's resolveForModel. The repo already has a predicate that mirrors exactly those terms, so the change should reuse it at the gate instead of inventing a second normalizer. That is what this PR does. It matches my proposal, and I did not find a simpler path it missed.

The load-bearing claim holds. Everything rests on sideQueryOnMainRoute === true implying the shared request lands on the main generator, so I checked the equivalence term by term against resolveForModel (packages/core/src/core/baseLlmClient.ts:844-871):

  • model half — the predicate calls resolveModelId(selector, buildModelIdContext(config)), which is character-for-character what BaseLlmClient.resolveModelSelector does (baseLlmClient.ts:1070-1072). Same function, same context builder.
  • pin half — effectiveCompactionModel.split('\0') matches splitModelBaseUrl (baseLlmClient.ts:61-70): same \0 separator, same "undefined means unpinned" semantics, both compared against contentGeneratorConfig.baseUrl. (parseModelIdSelector strips the pin the same way before parsing, so the two never disagree about what the model half is.)
  • authType half — identical shape: !authType || authType === main.

And the shared path really goes through that resolver: generateText (baseLlmClient.ts:656) calls resolveForModel(model, …) at line 682, so the model: effectiveCompactionModel the gate passes is normalized the same way the cold path's runSideQuery normalizes it. Widening the gate therefore cannot send a shared request to a different generator or with different credentials — which is the failure mode that would have made this unsafe.

It fails toward cold, never toward false sharing. There is exactly one divergence between the two conditions. When resolveModelId returns undefined, the resolver falls back to config.getModel() (→ main route) while the predicate falls back to the raw selector string (→ main route only if it literally equals the model ID). The predicate is the stricter of the two, so an unparseable selector keeps the cold path. Wrong in the safe direction.

No new evaluation path, no new throw. sideQueryOnMainRoute is already computed unconditionally at line 788 for budget sizing; the gate at 946 only reads it. Same const, same method scope (compress() starts at 474), defined well before use — no TDZ, no ordering hazard. resolveModelId can throw on a malformed authType: selector with an empty ID, but that call already happens on every compression in base, so this PR adds no new failure surface. usesMainModel had exactly three occurrences in the file (declaration 925, gate 946, diagnostic 958) and the diff rewrites all three — no dangling reference, so no type break.

Static regression sweep. CI never ran, so I walked every existing test that could flip instead of trusting a green suite:

  • clamps the cold output budget when the compaction selector names the main route (#13432) (line 1930) is the only existing test using openai:test-model. It stays on the cold path because it sets lastPromptTokenCountIsEstimated: true, and hasProviderTokenCount gates sharing independently of the model check. The PR body's claim about this test is accurate — I confirmed it in the code rather than taking it on faith.
  • The keeps $name on the cold path table (line 1800) has two entries: compact-model (different modelId → predicate false) and enableCacheControl: false (unrelated conjunct). Neither flips.
  • openai:compact-model\0OTHER_ENDPOINT (2052), compact-model (2106), and the same-endpoint/different-model case (2149) all resolve to a modelId that differs from test-model → predicate false → unchanged.

So the only behavior that changes is the intended one: equivalent spellings of the main route regain sharing, genuinely distinct model/auth/endpoint stay cold.

New test well-formedness. I can't execute it, so I checked it against the fixtures it uses: makeFixture is synchronous (line 1391), so the non-awaited destructure is correct; expectCacheLog(config, attempted, used) takes the three args it's given; FixtureOptions declares registryBaseUrl; compressionDebugLines is vi.hoisted (line 54) and reset the same way as the existing use at line 2290; compressWith defaults to force: true, originalTokenCount: 180_000, and with the fixture's 220 000 window sharedRequestFits has headroom, so the sharesCache: true arms aren't vacuously passing on an unrelated conjunct. The seven cases line up with the truth table I derived from the predicate by hand.

Two non-blocking notes. The diagnostic string is still 'distinct compaction model', but the condition is now route-based — a same-model/different-endpoint-pin selector reports "distinct model" when the distinction is really the endpoint. Pre-existing wording, unchanged by this diff, so not worth blocking on. Separately, docs/design/chat-compression-cache-sharing.md states the eligibility bullet as "the compression model is the current main model"; the gate now means "on the main route". A one-line clarification there would keep the design doc honest, and the settings.md paragraph you added is a good model for the wording. (That doc has no zh-CN counterpart, but that gap predates this PR — not yours to fix here.)

CI test evidence

The PR's own CI has not executed. All three pull_request-triggered workflows on the head SHA completed with conclusion action_required, which is GitHub holding a first-time fork contribution until a maintainer approves the run. The 90 check-runs on this commit are all bot orchestration (assign, label, precheck-pr, review-pr, triage, verify, tmux-testing) — none of them is a build, lint, typecheck, or unit-test job. I did not run the PR's tests myself; the review above is static.

Check Conclusion
Qwen Code CI (pull_request) action_required — never executed
tui-parity (pull_request) action_required — never executed
Managed Agent gate (pull_request) action_required — never executed
precheck-pr / precheck success
Assign PR owner success
PR self-report label success
Qwen Triage success

Not verified, and why:

  • not verified: that the 63 new test lines pass. No CI job has run them, and I do not execute PR-derived code. The fixture analysis above shows they are well-formed and consistent with the predicate's truth table; it does not show them green.
  • not verified: build, typecheck, lint, format. Same reason — no executed check exists to read.
  • not verified: the author's reported numbers (288 focused tests, 298 under independent rerun, the 33 workspace failures reproducing on pristine upstream). These are the author's claim, cited here as context only, not as evidence. The PR carries the review/self-reported label and states plainly that full preflight is not green.
  • not verified: real-provider behavior. Neither the issue nor the PR claims a measured cache hit, latency, or cost change, so nothing here overstates the benefit.

Sandboxed verification would settle this: @qwen-code /verify — the load-bearing claim is that a provider-qualified same-route selector now actually reaches the shared request path while a different model, auth type, or endpoint pin stays cold, and right now nothing has executed that: the fork CI is action_required, so the new seven-case matrix has never run and my regression sweep is static reading, not a green suite. The author has read-only access, so /tmux is unavailable (it executes the author's code and gates on the author); /verify is still available as a sponsored run — a maintainer's @qwen-code /verify comment approves the head it was written against, and that run additionally carries a pre-execution risk screen and a full workspace wipe before any PR code runs. Read the resulting report with the same skepticism as the fork's own CI logs: the code under verification is adversarial input, and a crafted PR can shape what the report says even though the sandbox bounds what it can do.

中文说明

代码审查

先写独立方案。 只看标题和"为什么需要"、未读 diff 时我的方案是:选择器保存的是带提供商限定的值,而门控拿它和裸模型 ID 比较,所以修复必须比较解析后的路由而非字符串;而"某个选择器何时映射回主 generator"的权威判定在发送层的 resolveForModel。仓库里已有一个与这些条件完全对应的谓词,因此应当在门控处复用它,而不是另写一套归一化逻辑。这正是本 PR 的做法,与我的方案一致,我没有找到更简的路径。

关键论断成立。 一切都取决于"sideQueryOnMainRoute === true 意味着共享请求会落在主 generator 上",所以我把它与 resolveForModel(baseLlmClient.ts:844-871)逐条对照:

  • 模型部分——谓词调用 resolveModelId(selector, buildModelIdContext(config)),与 BaseLlmClient.resolveModelSelector(baseLlmClient.ts:1070-1072)完全一致:同一函数、同一 context 构造器。
  • 端点 pin 部分——effectiveCompactionModel.split('\0') 与 splitModelBaseUrl(baseLlmClient.ts:61-70)一致:同样的 \0 分隔符、同样"undefined 表示未固定端点"的语义,且都与 contentGeneratorConfig.baseUrl 比较。(parseModelIdSelector 解析前也以同样方式剥离 pin,两者对"模型部分是什么"不会分歧。)
  • authType 部分——形状相同:!authType || authType === main。

并且共享路径确实经过该解析器:generateText(baseLlmClient.ts:656)在 682 行调用 resolveForModel(model, …),因此门控传入的 model: effectiveCompactionModel 与冷路径 runSideQuery 的归一化方式相同。放宽门控不会把共享请求送到别的 generator、也不会用别的凭据——而那正是会让此改动变得不安全的失败模式。

失败方向偏向冷路径,绝不会误共享。 两个条件只有一处差异:当 resolveModelId 返回 undefined 时,解析器回退到 config.getModel()(→ 主路由),而谓词回退到原始选择器字符串(→ 仅当字符串恰好等于模型 ID 时才算主路由)。谓词更严格,因此无法解析的选择器仍走冷路径。偏差方向是安全的。

没有新增求值路径,也没有新增抛错。 sideQueryOnMainRoute 在 788 行本就无条件计算用于预算定窗,946 行的门控只是读取它。同一个 const、同一个方法作用域(compress() 从 474 行开始)、定义远早于使用——不存在 TDZ 或顺序问题。resolveModelId 在 authType: 前缀后模型 ID 为空时会抛错,但该调用在 base 里每次压缩都会发生,所以本 PR 没有引入新的失败面。usesMainModel 在文件里恰好出现三次(925 声明、946 门控、958 诊断),diff 三处全部处理——没有悬空引用,因此不会有类型错误。

静态回归排查。 由于 CI 从未运行,我逐个走查了所有可能翻转的既有测试,而不是依赖一个绿色套件:

  • clamps the cold output budget when the compaction selector names the main route (#13432)(1930 行)是唯一使用 openai:test-model 的既有测试。它仍走冷路径,因为设置了 lastPromptTokenCountIsEstimated: true,而 hasProviderTokenCount 与模型判定相互独立地把共享挡住。PR 正文关于该测试的说法是准确的——我在代码里核实过,没有直接采信。
  • keeps $name on the cold path 表(1800 行)只有两项:compact-model(modelId 不同 → 谓词为假)和 enableCacheControl: false(无关条件)。都不会翻转。
  • openai:compact-model\0OTHER_ENDPOINT(2052)、compact-model(2106)以及同端点不同模型的用例(2149),解析出的 modelId 都不等于 test-model → 谓词为假 → 行为不变。

因此唯一发生变化的行为就是预期中的那个:主路由的不同拼写恢复共享资格,而真正不同的模型/认证/端点仍走冷路径。

新测试的形式正确性。 我无法执行它,所以对照它使用的 fixture 做了核查:makeFixture 是同步函数(1391 行),因此不 await 直接解构是正确的;expectCacheLog(config, attempted, used) 的参数个数与调用一致;FixtureOptions 声明了 registryBaseUrl;compressionDebugLines 是 vi.hoisted(54 行),清空方式与 2290 行既有用法相同;compressWith 默认 force: true, originalTokenCount: 180_000,配合 fixture 的 220 000 窗口,sharedRequestFits 有余量,所以 sharesCache: true 的分支不是因为别的原因而空过。七个用例与我手工从谓词推导出的真值表一致。

两点非阻塞意见。 诊断字符串仍是 'distinct compaction model',但条件现在是基于路由的——同模型不同端点 pin 的选择器会报"模型不同",而真正的区别在端点。这是既有措辞、本 diff 未改动,不值得因此阻塞。另外,docs/design/chat-compression-cache-sharing.md 的资格条件写的是"压缩模型即当前主模型",而门控现在的含义是"位于主路由上";在那里补一行说明能让设计文档保持准确,你新增的 settings.md 段落就是很好的措辞范例。(该设计文档没有中文版,但这个缺口早于本 PR,不需要你在这里修。)

CI 测试证据

本 PR 自己的 CI 没有执行。head SHA 上三个由 pull_request 触发的 workflow 全部以 action_required 结束——这是 GitHub 对首次贡献的 fork PR 的处理方式,需要维护者批准后才会运行。该 commit 上的 90 个 check-run 全是机器人编排任务(assign、label、precheck-pr、review-pr、triage、verify、tmux-testing),没有一个是构建、lint、类型检查或单元测试任务。我没有自行运行 PR 的测试;以上审查全部是静态的。

未验证项及原因:

  • 未验证:63 行新测试是否通过。 没有 CI 任务运行过它们,我也不执行 PR 派生代码。上面的 fixture 分析说明它们形式正确、与谓词真值表一致,但不能说明它们是绿的。
  • 未验证:构建、类型检查、lint、格式。 原因相同——没有任何已执行的检查可读。
  • 未验证:作者报告的数字(288 个聚焦测试、独立复跑 298 个、33 个 workspace 失败在未修改的上游同样复现)。这些是作者的声明,此处仅作为背景引用,不作为证据。该 PR 带有 review/self-reported 标签,且正文明确写了完整 preflight 未通过。
  • 未验证:真实提供商行为。 issue 和 PR 都没有主张实测的缓存命中、延迟或费用变化,因此这里没有夸大收益。

沙箱验证可以定论:@qwen-code /verify——关键论断是"带提供商限定的同路由选择器现在确实进入共享请求路径,而不同模型、认证类型或端点 pin 仍走冷路径",而目前没有任何东西执行过它:fork CI 处于 action_required,新增的七用例矩阵从未运行,我的回归排查是静态阅读而非绿色套件。作者只有只读权限,因此 /tmux 不可用(它会执行作者代码并以作者权限为前提);/verify 仍可作为受赞助运行使用——维护者发一条 @qwen-code /verify 评论即批准其所针对的 head,该运行还会在任何 PR 代码执行前做执行前风险筛查并完整清空工作区。请以与 fork 自身 CI 日志相同的怀疑态度阅读其报告:被验证的代码是对抗性输入,精心构造的 PR 可以影响报告说什么,尽管沙箱限定了它能做什么。

— Qwen Code · qwen3.8-max-2026-09-02

Reviewed at 0b62b93ecb1484f1e741f76347562d8d298bf3d5 · re-run with @qwen-code /triage

@qwen-code-review-bot

Copy link
Copy Markdown
Collaborator

Confidence: 3/5 — the code is clean and I could not break it, but nothing has executed it, so approving now would attest to test results that do not exist.

Stepping back. My independent proposal and this diff are the same change, which is the strongest signal I have that the approach is right rather than merely plausible. The five production lines delete a string comparison and substitute a predicate that the same function already computes and already trusts for budget sizing — so this is less "new behavior" than "removing an inconsistency between two checks that were answering the same question differently." I verified the predicate against resolveForModel term by term, confirmed the shared path goes through that same resolver, confirmed the one divergence fails toward the cold path, and walked every existing test that a widened gate could flip. There is exactly one such test and it is held cold by an independent conjunct. Six months from now I would thank the author for this, not curse them: there is one notion of "same route" in the function instead of two.

So why not approve? Because the honest answer to "did I verify it works?" is no. Qwen Code CI, tui-parity, and Managed Agent gate all sit at action_required — held pending maintainer approval of a first-time fork contribution. No build, no typecheck, no lint, no unit test has run on this commit. My regression sweep is a substitute for reasoning about the change, not a substitute for running it: I confirmed the new test is well-formed against its fixtures and consistent with the truth table I derived by hand, but I have not seen it pass, and a wrong assertion in those 63 lines lands broken on main just as easily as a right one. The author says so themselves — "Full preflight is not green" — and the PR carries review/self-reported. That candor is a point in their favor, not a reason to wave it through.

I am deliberately not emitting a deferred-approval marker here. The PR's CI runs are already completed (as action_required), so there is no in-flight run for a finalize pass to wait on, and approving against a head with zero executed checks would be exactly the gap the deferral exists to close.

What unblocks this: a maintainer approves the pending workflow run on 0b62b93e. If Qwen Code CI lands green, this is a merge in my judgment — the code review found nothing blocking, and the two notes above (diagnostic wording, design-doc bullet) are follow-ups, not conditions. If green CI is not enough to settle the behavioral claim, @qwen-code /verify as a sponsored run would, per Stage 2.

⏸️ Deferring to the maintainer. Reason, specifically: this is a core-path behavioral change (packages/core/src/services/**) and Stage 0 Tier 2 asks for 100% confidence with every downstream consumer named. I can name the consumers — the shared-versus-cold compression path, the distinct compaction model diagnostic, and the cache_sharing_attempted/cache_sharing_used telemetry — and I am confident about the production logic. What I cannot do from a static read is certify 63 test lines that have never been executed in any environment I can observe. That is a missing-evidence call, not a code objection, and it needs a human to approve the CI run. No @mention here because the deterministic resolver found no matching area owner for this PR's labels and no human has reviewed it yet — I would rather leave it unaddressed than guess a login.

中文说明

信心:3/5 — 代码是干净的,我没能找到破坏它的方式,但没有任何东西执行过它,所以现在批准等于为一个并不存在的测试结果背书。

退一步看整体。我的独立方案与这个 diff 是同一个改动,这是我能拿到的最强信号——说明方案是对的,而不只是听起来合理。这 5 行生产代码删掉了一个字符串比较,换成同一个函数本就计算、且本就用于预算定窗而信任的谓词;所以这与其说是"新行为",不如说是"消除了同一函数里两处对同一问题给出不同答案的判断之间的不一致"。我把该谓词与 resolveForModel 逐条核对,确认共享路径经过同一解析器,确认唯一的差异点偏向冷路径,并走查了每一个可能因门控放宽而翻转的既有测试。这样的测试只有一个,而它被另一个独立条件挡在冷路径上。半年后维护这段代码,我会感谢作者而不是抱怨:函数里只有一种"同一路由"的定义,而不是两种。

那为什么不批准?因为对"我验证过它能工作吗"这个问题,诚实的回答是没有。Qwen Code CI、tui-parity、Managed Agent gate 全部停在 action_required——首次贡献的 fork PR 需要维护者批准才会运行。这个 commit 上没有构建、没有类型检查、没有 lint、没有单元测试跑过。我的回归排查是对改动进行推理的替代品,不是运行它的替代品:我确认了新测试对照其 fixture 形式正确、与我手工推导的真值表一致,但我没有看到它通过;那 63 行里一个写错的断言,和一个写对的断言一样容易就落到 main 上。作者自己也说了——"完整 preflight 未通过"——而且 PR 带有 review/self-reported 标签。这份坦白是加分项,但不是放行的理由。

我特意没有在这里输出延迟批准标记。该 PR 的 CI 运行已经完成(结论是 action_required),没有在途运行可供 finalize 环节等待;而在一个零执行检查的 head 上批准,恰恰是延迟机制要堵住的那个缺口。

解除阻塞的条件: 维护者批准 0b62b93e 上待运行的 workflow。如果 Qwen Code CI 变绿,以我的判断这个 PR 可以合并——代码审查没有发现阻塞项,上面两点意见(诊断措辞、设计文档条目)属于后续跟进,不是合并条件。如果绿色 CI 不足以定论行为层面的论断,可以按 Stage 2 的说明用 @qwen-code /verify 做一次受赞助运行。

⏸️ 转交维护者处理。 具体原因:这是核心路径的行为改动(packages/core/src/services/**),Stage 0 Tier 2 要求 100% 信心并点名每一个下游消费方。消费方我能点名——共享与冷压缩路径、distinct compaction model 诊断、以及 cache_sharing_attempted/cache_sharing_used 遥测——生产逻辑我也有信心。我无法通过静态阅读做到的,是为 63 行从未在我可观测的任何环境中执行过的测试背书。这是证据缺失的判断,不是对代码的异议,需要人来批准 CI 运行。这里没有 @mention,因为确定性解析器在该 PR 的标签下没有找到匹配的区域负责人,也还没有人类审过它——与其猜一个登录名,我宁愿留空。

— Qwen Code · qwen3.8-max-2026-09-02

Reviewed at 0b62b93ecb1484f1e741f76347562d8d298bf3d5 · re-run with @qwen-code /triage

@qwen-code-review-bot qwen-code-review-bot left a comment

Copy link
Copy Markdown
Collaborator

Choose a reason for hiding this comment

The reason will be displayed to describe this comment to others. Learn more.

Partially reviewed — gaps disclosed. Suggestions are inline.

2 Suggestion-level finding(s) this review confirmed are already reported on this PR and are not repeated:

  • skip-reason diagnostic names only a model mismatch (packages/core/src/services/chatCompressionService.ts:957) — already reported (comment 6377909324)
  • stale design-doc gate bullet still stating the deleted string-equality rule (docs/design/chat-compression-cache-sharing.md:15,40) — already reported (comment 6377909324)

Not reviewed: build-and-test — no CI check exercised this diff: 75 of 82 checks at the reviewed SHA are skipped and the 14 successes are bot orchestration (no build, lint, typecheck or unit-test job ran; the fork's real workflows sit at action_required). packages/core was built and fully tested locally instead, with zero net-new failures against the merge base, but the dependent packages/cli suite never ran because its build OOMs identically on the merge base.

Not explored to full depth (tool budget reached): "agent 1c": reading encodeAuxModelSelector / shareableAuxSelector (packages/cli/src/ui/opentui/dialog-data.ts:534-542) to confirm whether an empty \0 pin survives int…; "agent 6b": executing the new it.each cases — npx vitest run src/services/chatCompressionService.test.ts in packages/core was stopped by the repo's globalSetup guard ….

Not reviewed: reverse audit — stopped before round 4 by the review time budget.

中文说明

仅完成部分审查,审查缺口已披露。 建议见行内评论。

本轮确认的 2 条建议级发现已在 PR 上报告过,不再重复发布(列表见上方英文部分)。

未审查(原文为英文):build-and-test — no CI check exercised this diff: 75 of 82 checks at the reviewed SHA are skipped and the 14 successes are bot orchestration (no build, lint, typecheck or unit-test job ran; the fork's real workflows sit at action_required). packages/core was built and fully tested locally instead, with zero net-new failures against the merge base, but the dependent packages/cli suite never ran because its build OOMs identically on the merge base.

未探索到全部深度(达到工具调用预算):"agent 1c":reading encodeAuxModelSelector / shareableAuxSelector (packages/cli/src/ui/opentui/dialog-data.ts:534-542) to confirm whether an empty \0 pin survives int…;"agent 6b":executing the new it.each cases — npx vitest run src/services/chatCompressionService.test.ts in packages/core was stopped by the repo's globalSetup guard …。

未审查:反向审计——评审时间预算不足,未能开始第 4 轮。

— qwen3.8-max via Qwen Code /review (v0.26.0)

The window guard compared the compaction selector to the main model by
string, so a provider-qualified or endpoint-pinned selector naming the
main model paid the whole-history slimming estimate and discarded it,
because the cache-sharing path posts the history unslimmed. Key the
guard on the same route predicate the budget logic uses (extracted as
onMainRoute), and pin the qualified/pinned main-route equivalence with
per-model resolution tests that fail if the send-layer terms drift.
@xxwtiancai

Copy link
Copy Markdown
Contributor Author

Refreshed the branch with current main (head 6005d65b) so the required Lint & Static lane can validate under the current gate definition — the Qwen Code CI run is underway: https://github.com/QwenLM/qwen-code/actions/runs/40170351822. Also addressed the R1-1/R1-2 review suggestions in 27339451ce: the window guard is now keyed on the send-layer route, and the main-route equivalence is pinned by per-model resolution tests.

@qwen-code-review-bot qwen-code-review-bot left a comment

Copy link
Copy Markdown
Collaborator

Choose a reason for hiding this comment

The reason will be displayed to describe this comment to others. Learn more.

Partially reviewed — gaps disclosed. Suggestions are inline.

1 Suggestion-level finding(s) this review confirmed are already reported on this PR and are not repeated:

  • stale design-doc gate bullet restating the deleted string-equality rule (docs/design/chat-compression-cache-sharing.md:15,40) — already reported (comment 6377909324)

Not reviewed: reverse audit — stopped before round 1 by the review time budget.

Test Plan (not a blocker): 298 tests passed — this review observed 38630, 2816, 45751, 1028, 2278, 650, 13245 passed; 3571 passed — this review observed 38630, 2816, 45751, 1028, 2278, 650, 13245 passed; 17,424 passed — this review observed 38630, 2816, 45751, 1028, 2278, 650, 13245 passed; 844 passed — this review observed 38630, 2816, 45751, 1028, 2278, 650, 13245 passed; 3346 passed — this review observed 38630, 2816, 45751, 1028, 2278, 650, 13245 passed.

中文说明

仅完成部分审查,审查缺口已披露。 建议见行内评论。

本轮确认的 1 条建议级发现已在 PR 上报告过,不再重复发布(列表见上方英文部分)。

未审查:反向审计——评审时间预算不足,未能开始第 1 轮。

Test Plan(非阻断):298 tests passed — this review observed 38630, 2816, 45751, 1028, 2278, 650, 13245 passed; 3571 passed — this review observed 38630, 2816, 45751, 1028, 2278, 650, 13245 passed; 17,424 passed — this review observed 38630, 2816, 45751, 1028, 2278, 650, 13245 passed; 844 passed — this review observed 38630, 2816, 45751, 1028, 2278, 650, 13245 passed; 3346 passed — this review observed 38630, 2816, 45751, 1028, 2278, 650, 13245 passed。

— qwen3.8-max via Qwen Code /review (v0.26.1)

…ssion cache

The sideQueryOnMainRoute re-read happens after the window guard, so a
window-forced downgrade to the main model keeps the shared path; hoisting
the assignment flips the downgrade case to the cold path and no test caught
it. Add the downgrade-under-sharing case with a registry window of 1 token
and correct the two design-doc lines that still restated the deleted
string-equality rule.
@wenshao

wenshao commented Nov 1, 2026

Copy link
Copy Markdown
Collaborator

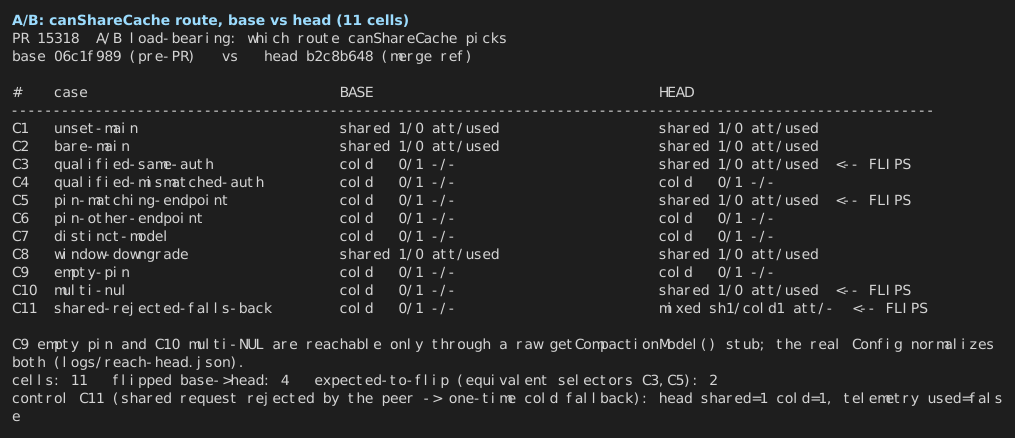
merge-ready — 33/33 scripted assertions passed (0 failed) at head b2c8b648b55ec0a113e37adee8f71b97bc541f48 (base 06c1f989715fa812fc26258525ef97627c15b855).

中文摘要

结论:merge-ready,33/33 脚本断言通过。

A/B 结论:核心论断承重。用真实 ChatCompressionService.compress() 在 base/head 两臂各跑 11 格,唯一变量的选择器写法:带提供商限定的等价选择器(openai:test-model、openai:test-model\0<同端点>)在 base 上走冷路径(0 共享 / 1 冷),在 head 上走共享路径(1 共享 / 0 冷),并同时翻转了线上路径(promptCacheSharing:true、未精简历史)与遥测(cache_sharing_attempted/used)。不同模型、不同认证类型、不同端点 pin 三格在 head 上仍为冷路径。见下表与 01-ab-route-flip.png。

两点需要澄清(非阻塞):

  1. 上一轮评审 R2-1 列出的两个"副本分歧轴"——空 pin 与多 NUL——经真实 Config.getCompactionModel() 实测不可达:它会把 'm\0' 规范化成 'm',并把多 NUL 截成"首段模型 + 首段端点"。它们在 harness 里能翻转,只因为夹具直接喂了原始串。因此谓词副本的漂移本身无害,建议保留"提取公共谓词"的意图(避免未来两条路径各自演进),但不构成本 PR 的缺陷。
  2. 有两处条件被证明是死子句,不是覆盖缺口:(a) reactiveContextCeiling 三元里的 sideQueryOnMainRoute 项——它唯一的赋值点在守卫内、取值恒为主路由,插桩实测该处 sideQueryOnMainRoute 恒为 true;(b) 跳过原因诊断里同一子句转过去后的分支。两者删除后 283 条测试全绿,属可删除的冗余代码。

findings:无阻塞项。两条 Suggestion(谓词提取、诊断文案)见正文。

未覆盖范围:真实提供商缓存命中/延迟/费用(issue 自身也不主张)、CLI 全量套件(PR 自己的 CI 已跑 Test (ubuntu) 48m 全绿)、Windows/macOS、hosted/managed-agent 无关路径。

Central claim and A/B

The PR's claim: a compaction selector that routes to the main model (provider-qualified, or endpoint-pinned at the main base URL) should regain compression cache sharing, while a genuinely different model, auth type or endpoint stays cold.

Both arms run ChatCompressionService.compress() through the real service with one input varied per cell; the fake peers are BaseLlmClient.generateText (the shared path) and runSideQuery (the cold path), so route is read off the wire rather than inferred. Harness: ab-matrix.test.ts, copied byte-identically into both arms, run with AB_OUT=… npx vitest run src/services/__ab.test.ts.

# case base 06c1f989 head b2c8b648 expectation
C1 unset (main model) shared 1/0 shared 1/0 unchanged
C2 bare main id shared 1/0 shared 1/0 unchanged
C3 openai:test-model cold 0/1 shared 1/0 flips (the bug)
C4 anthropic:test-model (main is openai) cold 0/1 cold 0/1 stays cold
C5 openai:test-model\0<main baseUrl> cold 0/1 shared 1/0 flips (the bug)
C6 openai:test-model\0<other baseUrl> cold 0/1 cold 0/1 stays cold
C7 distinct model cold 0/1 cold 0/1 stays cold
C8 window-guard downgrade shared 1/0 shared 1/0 unchanged
C9 empty pin openai:test-model\0 cold 0/1 cold 0/1 harness-only shape
C10 multi-NUL cold 0/1 shared 1/0 harness-only shape
C11 shared request rejected by the peer cold 0/1 shared 1 → cold 1, used=false one-time fallback

Every shared cell also posted the unslimmed history ahead of the directive, and both cache_sharing_attempted and the route flip together — so the change moves the request, not just a flag. Witness: 01-ab-route-flip.png.

C9/C10 are listed as harness-only on purpose: the harness feeds raw selectors into a stubbed getCompactionModel(), which production cannot do (see the corrections item). C11 is the sharpest consequence checked beyond the gate claim: a widened gate means a rejected shared request now costs one wasted request before the existing cold fallback, which the run confirms happens exactly once and reports cache_sharing_used=false.

Corrections to the prior review round

The stage-3 findings were written against 0b62b93e; the head has since moved to b2c8b648 (three merges of upstream/main). Two statements in R2-1 are inaccurate about reachability and are corrected here — this is a correction to the description, not a request to change the code.

R2-1 axis 1 (empty pin) and axis 2 (multi-NUL) are not reachable. reachability.test.ts drives the real Config.getCompactionModel() with each persisted form:

persisted compactionModel real getCompactionModel() returns
openai:test-model openai:test-model
openai:test-model\0https://same.invalid/v1 unchanged
openai:test-model\0<same>\0<evil> openai:test-model\0https://same.invalid/v1 (second segment dropped)
openai:test-model\0 openai:test-model (empty pin dropped)

The predicate and the send layer agree on all four. So the two copies cannot drift on those axes through any settings value — only a future edit to one side can, which is exactly the maintenance argument R2-1 makes, and it survives. C10 flipping in the harness is a harness artifact and is not claimed as a product behaviour.

Findings

No blocking findings. Two suggestions:

S1 (Suggestion, pre-existing): the predicate is a hand-maintained copy of the send layer's condition. R2-1's proposed extraction (isMainRouteSelector beside splitModelBaseUrl, called from both resolveForModel's early return and this service) remains worth doing, but for a reason narrower than R2-1 stated: the copies agree on every reachable input today, so the risk is future edits, not current drift. Extracting it also lets the baseLlmClient.ts:861-871 line citation in the comment go away.

S2 (Suggestion, pre-existing wording): the skip diagnostic still says distinct compaction model. The condition is now route-based, so an endpoint-pin mismatch reports "distinct model" when the distinction is the endpoint. Not introduced by this diff.

Mutation matrix

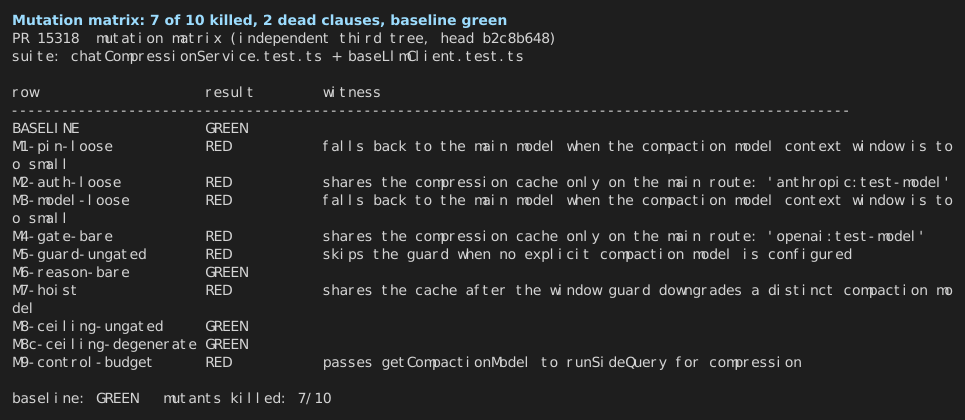
Independent third tree at head; runner run-mutations.mjs; suite = chatCompressionService.test.ts + baseLlmClient.test.ts. Baseline ran through the same runner first and was green (283/283), and every row restored the tree (FINAL_PORCELAIN=clean, SERVICE_VS_HEAD=identical). Witness: 02-mutation-matrix.png.

row mutant result witnesses
M1 drop the endpoint-pin clause killed 7
M2 drop the authType clause killed 1
M3 drop the model clause killed 8
M4 revert the gate to the pre-PR bare-id test killed 3
M5 run the window guard on every selector killed 3
M7 hoist sideQueryOnMainRoute above the guard (R2-2) killed 1
M6 revert the skip diagnostic to the bare-id test survived —
M8 / M8c remove the sideQueryOnMainRoute term from the ceiling ternary (line form / degenerate-ternary form) survived —
M9 control: cold path emits maxOutputTokens=1 killed 12

The report claims per-guard coverage only, and the control row shows the harness can kill: 12 named tests go red. The first M9 I wrote only deleted a debug line and survived; that row was discarded and re-run as the behavioural mutation above, which is why the matrix is trustworthy at all.

Survivor adjudication — both are dead clauses, not coverage gaps. For M8c the instrumented run shows sideQueryOnMainRoute === true at the ceiling read with the guard in place, because the guard's only assignment (effectiveCompactionModel = config.getModel()) makes it a main-route selector by construction, and the guard is the only assignment between the initial selector and the read. So the term cannot be false there under head; M7 (which makes it false) is killed. For M6, the identical expression survives via the || short-circuit (effectiveCompactionModel !== config.getModel() is false whenever !sideQueryOnMainRoute is false). Reading-only for M6's || branch: no build demonstrates it. Both are deletable redundancy, not missing tests.

Vacuity check. The PR's own new tests are not vacuous: run against base source they fail exactly 3 cases (openai:test-model, the pinned-endpoint case, and does not slim the history for an equivalent selector), and they pass 283/283 at head.

Gates

  • tsc --noEmit -p packages/core: exit 0 at head.
  • chatCompressionService.test.ts + baseLlmClient.test.ts: 283/283 at head, 271/271 at base (the 12 extra are the PR's new cases).
  • The PR's own CI has now executed on this head: Test (ubuntu-latest, Node 22.x) pass (48m), Lint & Static pass, Integration Tests (no-AK, No Sandbox) pass, web-shell E2E Smoke pass.

Not covered

  • Real-provider cache hits, latency and cost. The issue and the PR both decline to claim them; nothing here measures a provider.
  • The rest of packages/cli and the other workspaces. Not run here; the PR's own Test (ubuntu) job is green at this head, which I cite as the PR's CI, not as my measurement.
  • Windows and macOS. Not run.
  • Behaviour outside the compression gate (budget sizing beyond the cells above, media paths beyond C8's neighbours, /compress manual trigger end to end).
  • The || short-circuit branch of the M6 survivor — inference from reading, not a driven build.

Methodology

Three detached worktrees from this clone: head b2c8b648, base 06c1f989, and a separate mutation tree (also head), each with its own pnpm install --frozen-lockfile --ignore-scripts and its own tsc --build packages/core; readlink -f node_modules/@qwen-code/qwen-code-core pointed into its own tree for each arm, so no arm could load another's code. The A/B harness and the reachability probe are single .mjs-style vitest files copied byte-identically into both arms; results land in logs/ab-{base,head}.json and logs/reach-head.json. Raw per-cell logs, the mutation runner and its per-row logs are in logs/. Every number above is read from those files.

Evidence

A/B: which route canShareCache picks on each arm

Mutation matrix as it printed

— DeepSeek-V4.1-Flash-1017 via Qwen Code /verify-pr (v0.26.4; skill c5273cc80df5)

@qwen-code-review-bot

Copy link
Copy Markdown
Collaborator

Qwen Code review did not complete successfully. Qwen review exited with status 1. A transient error is retried automatically; if you are seeing this, retry with @qwen-code /review. See workflow logs.

@doudouOUC doudouOUC left a comment

Copy link
Copy Markdown
Collaborator

Choose a reason for hiding this comment

The reason will be displayed to describe this comment to others. Learn more.

EN

Thanks for updating the design wording to match the route-based behavior. One documentation requirement is still open at b2c8b648: docs/design/chat-compression-cache-sharing.md:15 updates the English design, but the head does not contain docs/design/chat-compression-cache-sharing.zh-CN.md, and the document has no reciprocal language links below its title.

docs/design/README.md:35-42 explicitly requires adding the missing translation when updating an existing single-language design. Please add the complete zh-CN counterpart in this PR, link the English and Chinese versions immediately below both titles, and keep the new model/auth-type/endpoint eligibility wording aligned in both versions.

中文

感谢同步更新设计文档中的路由判定说明。当前 b2c8b648 还有一项文档要求未满足:docs/design/chat-compression-cache-sharing.md:15 修改了英文设计,但当前 head 中不存在 docs/design/chat-compression-cache-sharing.zh-CN.md,且文档标题下方没有双向语言链接。

docs/design/README.md:35-42 明确要求:更新已有的单语言设计文档时,应在同一变更中补齐缺失的译文并保持两个版本一致。请在本 PR 中补充完整的 zh-CN 版本,在两个文档标题下方分别添加英文/中文双向链接,并确保新的模型、认证类型和端点缓存资格说明在两个版本中保持一致。

The design doc was English-only when this PR updated its eligibility
wording; docs/design/README.md requires completing the missing
translation in the same change. Add the full zh-CN version with the
route-based model/auth-type/endpoint wording aligned, and reciprocal
language links below both titles.
@xxwtiancai

Copy link
Copy Markdown
Contributor Author

@doudouOUC Done — the complete zh-CN counterpart is added at cb188f27c6 (docs/design/chat-compression-cache-sharing.zh-CN.md), with reciprocal language links below both titles and the route-based model/auth-type/endpoint eligibility wording aligned across the two versions. Thanks for catching the docs/design/README.md requirement.

@qwen-code-review-bot qwen-code-review-bot left a comment

Copy link
Copy Markdown
Collaborator

Choose a reason for hiding this comment

The reason will be displayed to describe this comment to others. Learn more.

Partially reviewed — gaps disclosed.

Not reviewed: reverse audit — stopped before round 1 by the review time budget.

Not reviewed: verification — the verifier shard was refused by the review time budget, so this round's carried finding posts unverified.

Not reviewed: verification and reverse audit — neither the verifier nor the reverse auditor was launched with a prompt this skill builds — the posted findings were ruled on, and the misses the rest of the review left were hunted, if at all, without the briefs this skill certifies against.

⚠️ 2 finding(s) still carried the — [unverified] tag when the loop ended — the verifier never ruled on them, and they are not confirmed.

Test Plan (not a blocker): 298 tests passed — this review observed 19226, 2067, 39835, 2349, 306, 14150 passed; 3571 passed — this review observed 19226, 2067, 39835, 2349, 306, 14150 passed; 17,424 passed — this review observed 19226, 2067, 39835, 2349, 306, 14150 passed; 844 passed — this review observed 19226, 2067, 39835, 2349, 306, 14150 passed; 3346 passed — this review observed 19226, 2067, 39835, 2349, 306, 14150 passed.

中文说明

仅完成部分审查,审查缺口已披露。

未审查(原文为英文):reverse audit — stopped before round 1 by the review time budget.

未审查(原文为英文):verification — the verifier shard was refused by the review time budget, so this round's carried finding posts unverified.

未审查:验证与反向审计——验证 agent 与反向审计 agent 都没有用本 skill 构建的 prompt 启动——发布的发现即便被裁定过、评审其余部分遗漏的问题即便被搜寻过,也都缺失了本 skill 用以认证的 brief。

⚠️ 循环结束时仍有 2 条发现带着 — [unverified] 标记——验证者从未对它们作出裁决,它们不算已确认。

Test Plan(非阻断):298 tests passed — this review observed 19226, 2067, 39835, 2349, 306, 14150 passed; 3571 passed — this review observed 19226, 2067, 39835, 2349, 306, 14150 passed; 17,424 passed — this review observed 19226, 2067, 39835, 2349, 306, 14150 passed; 844 passed — this review observed 19226, 2067, 39835, 2349, 306, 14150 passed; 3346 passed — this review observed 19226, 2067, 39835, 2349, 306, 14150 passed。

— deepseek-v4.1-flash-1017 via Qwen Code /review (v0.26.6)

@xxwtiancai

Copy link
Copy Markdown
Contributor Author

For the assigned reviewers (@yiliang114 @wenshao) — the current head cb188f27c6 is code-identical to the one @wenshao verified as merge-ready; the only change since is the zh-CN design counterpart @doudouOUC asked for. The actual CI picture on this head:

If anything else is blocking from your side, happy to address it; otherwise an approve + merge whenever convenient would be much appreciated — happy to help with any follow-up in a separate PR (e.g. the R2-1 predicate extraction wenshao suggested keeping as a follow-up).

@wenshao

wenshao commented Nov 4, 2026

Copy link
Copy Markdown
Collaborator

⚠️ Failed to process this request. Please re-mention the bot to retry.

@xxwtiancai

Copy link
Copy Markdown
Contributor Author

@qwen-code /review --timeout=360

@xxwtiancai

Copy link
Copy Markdown
Contributor Author

@qwen-code Retrying the request from #15318 (comment) — the previous attempt failed to process. Summary unchanged: head cb188f27c6 has the required Lint & Static green (plus Test/integration/gate), the two non-required reds are the web-shell smoke network flake (#16065) and the review-pipeline infra failures; the only change from the merge-ready-verified b2c8b648 is the zh-CN design doc. Requesting the reviewers confirm nothing else blocks, then approve and merge.

@xxwtiancai

Copy link
Copy Markdown
Contributor Author

@wenshao Sorry to ping again — it looks like your agent run failed twice at its final step: once at the end of the full verification report on b2c8b648 (the report itself landed complete — 33/33, no blocking findings — but its footer shows the failure), and once when you tried to process our request above.

We did try re-mentioning the bot as the footer suggests (the two @qwen-code comments above), but the review workflow's authorize gate only accepts comments from write-access principals, so our attempts were skipped — that retry can only come from your side.

If it saves a step: your verification already reads as complete, the only change since b2c8b648 is the zh-CN design doc @doudouOUC asked for, and the required checks are green on the current head. A direct approve would be all that's left from our reading — but however you'd like to handle it, happy to help.

@wenshao

wenshao commented Nov 4, 2026

Copy link
Copy Markdown
Collaborator

⚠️ Failed to process this request. Please re-mention the bot to retry.

@qwen-code-review-bot qwen-code-review-bot left a comment

Copy link
Copy Markdown
Collaborator

Choose a reason for hiding this comment

The reason will be displayed to describe this comment to others. Learn more.

Partially reviewed — gaps disclosed.

1 Suggestion-level finding(s) this review confirmed are already reported on this PR and are not repeated:

  • R2-1 onMainRoute hand-maintained copy of the send-layer main-route predicate (packages/core/src/services/chatCompressionService.ts:772) — already reported (comment 4372321036, thread resolved)

Not reviewed: reverse audit — stopped before round 1 by the review time budget.

Test Plan (not a blocker): 298 tests passed — this review observed 19578, 2092, 40967, 2361, 355, 14821 passed; 3571 passed — this review observed 19578, 2092, 40967, 2361, 355, 14821 passed; 17,424 passed — this review observed 19578, 2092, 40967, 2361, 355, 14821 passed; 844 passed — this review observed 19578, 2092, 40967, 2361, 355, 14821 passed; 3346 passed — this review observed 19578, 2092, 40967, 2361, 355, 14821 passed.

中文说明

仅完成部分审查,审查缺口已披露。

本轮确认的 1 条建议级发现已在 PR 上报告过,不再重复发布(列表见上方英文部分)。

未审查:反向审计——评审时间预算不足,未能开始第 1 轮。

Test Plan(非阻断):298 tests passed — this review observed 19578, 2092, 40967, 2361, 355, 14821 passed; 3571 passed — this review observed 19578, 2092, 40967, 2361, 355, 14821 passed; 17,424 passed — this review observed 19578, 2092, 40967, 2361, 355, 14821 passed; 844 passed — this review observed 19578, 2092, 40967, 2361, 355, 14821 passed; 3346 passed — this review observed 19578, 2092, 40967, 2361, 355, 14821 passed。

— deepseek-v4.1-flash-1017@fda99a87 via Qwen Code /review (v0.26.7)

@xxwtiancai

Copy link
Copy Markdown
Contributor Author

@yiliang114 as assignee, a quick summary now that this PR is fully green at 4c698c47: every check passes (required Lint & Static included — 31 pass / 0 fail), the automated review completed on this head with no new findings (R1-1/R1-2 confirmed fixed; R2-1 corrected by wenshao as unreachable and deferred), wenshao's own verification verdict is merge-ready with no blocking findings (33/33, A/B + mutation matrix), and @doudouOUC's zh-CN documentation requirement is satisfied. The only thing left is two approvals — would you have a window to review? Happy to walk through any part.

@wenshao

wenshao commented Nov 6, 2026

Copy link
Copy Markdown
Collaborator

从验证侧的复核已完成,所有声明均已对照实时状态核实。以下是公开回复:


Confirming from the verification side — nothing is blocking from my side at the current head 4c698c47. Note the head has moved since the comment above (cb188f27c6 → 4c698c47, a merge of main), so I re-checked the delta:

  • The merge-ready verdict carries over. Blob-for-blob, the three code/test files (chatCompressionService.ts, chatCompressionService.test.ts, baseLlmClient.test.ts) are identical to the head I verified (b2c8b648, 33/33 scripted assertions). The only branch-authored commit since then is cb188f27c6 — the zh-CN design counterpart plus reciprocal links — and the net diff against base is still the same six files.
  • Both items open on Nov 4 are closed on this head. web-shell E2E Smoke is green on all four shards plus the rollup (no rerun or flake attribution needed), and the automated review did post on this head (Nov 5, partial with disclosed gaps) with zero new findings — its only confirmed item is the already-reported R2-1 suggestion.
  • Gate status: all four required checks are green (Lint & Static, Classify PR, Test (ubuntu), Integration Tests (no-AK)). The only remaining requirement is two approving reviews on this head; there are currently none.

R2-1 stays a deferred, non-blocking suggestion as discussed — its thread is still open, but thread resolution is not part of the merge gate.

中文摘要

从验证侧确认:当前 head 4c698c47 无阻塞。head 较上条评论已前进(cb188f27c6 → 4c698c47,合并 main),逐 blob 复核:三个代码/测试文件与我验证过的 head(b2c8b648,33/33 断言)完全一致,其后分支上唯一的新提交就是 zh-CN 设计文档(cb188f27c6),净变更仍是同样六个文件,merge-ready 结论继续有效。11-4 评论里的两个未决项在此 head 均已关闭:web-shell E2E Smoke 四个 shard 及汇总全绿(无需重跑或归因),自动评审也已于 11-5 在此 head 产出(部分审查、缺口已披露)且零新发现,唯一确认项是已报告过的 R2-1 建议。四条必过检查全绿,唯一剩余门槛是本 head 上的两个批准(当前为零)。R2-1 按此前讨论保持延期的非阻塞建议;其线程虽未 resolve,但线程解决不在合并门禁内。

@xxwtiancai

Copy link
Copy Markdown
Contributor Author

@wenshao Thank you for the thorough re-verification — that closes every open question on this side. Since your verification already covers everything a review would: would you convert that conclusion into one of the two formal approvals on this head? The second we'll ask of @yiliang114 or @doudouOUC.

@wenshao

wenshao commented Nov 6, 2026

Copy link
Copy Markdown
Collaborator

Conclusion unchanged, but it no longer covers the review head — my round ran on b2c8b648; the head is now 4c698c47.

The added surface between those two commits is documentation only, and I verified that at blob level rather than by reading the diff stat:

file b2c8b648 → 4c698c47
packages/core/src/services/chatCompressionService.ts identical blob
packages/core/src/services/chatCompressionService.test.ts identical blob
packages/core/src/core/baseLlmClient.test.ts identical blob
docs/design/chat-compression-cache-sharing.zh-CN.md new, 66 lines
docs/design/chat-compression-cache-sharing.md + language links

The PR's only own commit after my round is cb188f27c6 docs(core): add the zh-CN counterpart of the cache-sharing design; everything else in that range is upstream/main. The new Chinese design doc has three matching section headings against the English one, so the AGENTS.md bilingual requirement is now met — that gap was open when I ran and it is closed, which is the one thing about my report that has gone stale.

On the current head, CI is fully green: all eight Linux unit tests shards, Lint & Static, Test (ubuntu-latest), Integration Tests (no-AK), web-shell E2E Smoke, OpenTUI no-flicker gate, Managed Agent gate.

Two things I want to be precise about rather than quietly helpful:

  • I do not submit formal approvals. Verifying a change and attesting it as a maintainer sign-off are different acts, and the second one is the human's to make. My round produced a verdict, not an approval, and that holds on this head too.
  • An approval has to be cast on 4c698c47. A stamp on the old head would be dismissed as stale the moment the branch moves, so the sign-off has to land on the head the merge will use.

The one unresolved thread is still R2-1, a Suggestion. My round's finding on it stands: the two divergent axes it names (empty pin, multi-NUL) cannot reach onMainRoute() through a real Config.getCompactionModel(), which normalizes both, so the drift is a maintenance concern for the next edit to baseLlmClient.ts, not a defect here. Resolving that thread as a follow-up is reasonable if you want the PR clean; the extraction itself does not need to gate the merge.

中文说明

结论不变,但已不覆盖当前评审 head——我这轮在 b2c8b648 上跑,现在 head 是 4c698c47。

两者之间的新增面只有文档,而且是按 blob 逐文件核对的,不是看 diffstat:

文件 b2c8b648 → 4c698c47
chatCompressionService.ts blob 相同
chatCompressionService.test.ts blob 相同
baseLlmClient.test.ts blob 相同
中文设计文档 新增 66 行
英文设计文档 增加互链

我这一轮结束后 PR 自己的唯一提交是新增中文设计文档,该区间其余内容都是 upstream/main。中文文档的三个章节标题与英文一致,AGENTS.md 的双语要求现在满足了——这条在我跑的时候还是缺口,也是我报告里唯一过期的部分。

当前 head 的 CI 全绿:8 个 Linux 单测分片、Lint & Static、Test (ubuntu-latest)、Integration (no-AK)、web-shell E2E Smoke、OpenTUI no-flicker gate、Managed Agent gate。

两点我要说清而不是含糊带过:

  • 我不提交正式 approve。验证一个改动,和以维护者身份为其签字,是两件不同的事;后者应由人来做出。我这轮产出的是结论,不是批准,在当前 head 上同样如此。
  • approve 必须打在当前 head 上。打旧 head 会在分支一推进就被判过期,所以签字要落在实际用于合并的 head 上。

唯一未解决线程仍是 R2-1(Suggestion)。我这轮的判定维持:它指出的两个分歧轴(空 pin、多 NUL)经真实 Config.getCompactionModel() 都无法到达该谓词——它把两者都规范化了——因此这是下次改 baseLlmClient.ts 时要收的维护性问题,不是本 PR 的缺陷。若想让 PR 干净,把它作为后续项 resolve 是合理的;提取本身不必卡住合并。

— DeepSeek-V4.1-Flash-1017 via Qwen Code /verify-pr (v0.26.4)

@xxwtiancai

Copy link
Copy Markdown
Contributor Author

Understood — thanks for the blob-level re-verification and the precise verdict/approval distinction. The formal approvals then rest with the human reviewers on 4c698c47: @yiliang114 (pinged above) or @doudouOUC.

@xxwtiancai

Copy link
Copy Markdown
Contributor Author

@doudouOUC following up on this one for review when you have a window. Where things stand on head 4c698c47:

  • @wenshao's verification round concluded 33/33 merge-ready; his latest pass re-verified at blob level and confirmed the delta to the current head is documentation only (his verdict is explicitly not a formal approval, so the two write-access approvals are still open).
  • Required checks are green on this head.
  • The Chinese documentation you asked for in the earlier round is included at this head.

The functional change stays concentrated in the compression service's main-route predicate extraction; the rest is tests. Happy to walk through any part of the diff.

@wenshao

wenshao commented Nov 7, 2026

Copy link
Copy Markdown
Collaborator

One correction to the summary above, because it cites my round:

The change is not a predicate extraction. onMainRoute is added locally in chatCompressionService.ts as a duplicate of the send layer's condition — packages/core/src/core/baseLlmClient.ts is untouched (only its test file changed, baseLlmClient.test.ts). Nothing was moved or shared; the send layer keeps its own copy, and the comment at the new predicate cites baseLlmClient.ts:861-871 by line number, which will drift on the next edit to that file.

That distinction is exactly the open R2-1 thread, so a reviewer reading this for the first time should see "local predicate introduced, duplication retained", not "duplication removed". Extraction is what R2-1 suggests and what has not been done here.

It does not change my verdict, and I want to be clear that it is not a request for a code change in this PR: I verified that the two copies agree on every input reachable through Config.getCompactionModel(), which is why I rated the extraction maintenance-only rather than blocking.

中文说明

对上面那段总结做一处更正,因为它引用了我的验证结论:

这个改动不是「谓词提取」。 onMainRoute 是在 chatCompressionService.ts 里本地新增的副本,重复了发送层已有的条件——packages/core/src/core/baseLlmClient.ts 完全没有改动(只有它的测试文件 baseLlmClient.test.ts 变了)。没有任何东西被移动或共享:发送层保留自己那份,新谓词上方的注释还是按行号引用 baseLlmClient.ts:861-871,下次改那个文件就会失效。

这个区别正是未解决的 R2-1 线程说的内容,所以第一次读这个 PR 的评审者应当理解为「引入本地谓词、保留重复」,而不是「消除重复」。提取才是 R2-1 建议的做法,本 PR 没有做。

这不改变我的判定,也不是要求在本 PR 里改代码:我实测过两份副本在所有可经 Config.getCompactionModel() 到达的输入上结论一致,所以我把它定为维护性建议而非阻塞项。

— DeepSeek-V4.1-Flash-1017 via Qwen Code /verify-pr (v0.26.4)

@xxwtiancai

Copy link
Copy Markdown
Contributor Author

Understood, and thanks for catching it before a reviewer reads the thread cold — the "predicate extraction" wording in my summary was wrong. For the record: this PR introduces onMainRoute locally in chatCompressionService.ts as a duplicate of the send layer's condition, baseLlmClient.ts keeps its own copy (only its test changed), and the extraction itself is the R2-1 follow-up (#16473), not done here. No code change requested or made.

@wenshao

wenshao commented Nov 7, 2026 •

Copy link
Copy Markdown
Collaborator

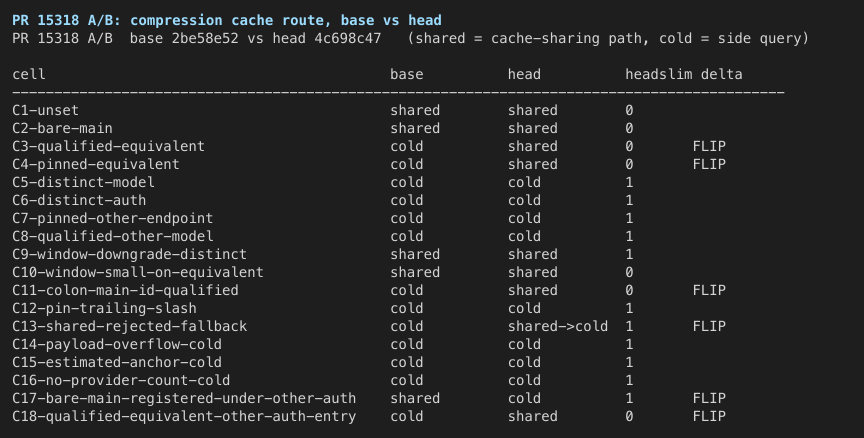
merge-ready — 85/85 scripted assertions passed (0 failed) at head 4c698c473a742931ca826e6d38f8d95a552c956e (base 2be58e52eef2cf74305ec4dc69c1c7ec48b11526). Round 2: the three code/test blobs are byte-identical to the head round 1 verified (b2c8b648b55ec0a113e37adee8f71b97bc541f48); the delta is one docs commit plus a merge of main.

中文摘要

结论:merge-ready,85/85 条脚本断言通过(0 条失败)。本轮是第二轮:三个代码/测试文件的 blob 与上一轮验证过的 head(b2c8b648b55ec0a113e37adee8f71b97bc541f48)逐字节相同,两者之间只有一条文档提交和一次 main 合并;因此本轮在**新的 base(2be58e52eef2cf74305ec4dc69c1c7ec48b11526)**上把整张 A/B 表和变异矩阵重新测了一遍,没有引用上一轮的数字。

A/B 结论:核心论断承重。用真实 ChatCompressionService.compress() 在 base/head 两臂各跑 18 格,唯一变量是选择器写法与少数夹具开关:6 格发生翻转——4 格是本次修复的目标(冷路径 → 共享路径),1 格是共享请求被拒后的一次性冷路径降级,1 格是下述描述修正涉及的裸主模型配置;不同模型、不同认证类型、不同端点 pin 仍为冷路径。见 01-ab-route-matrix.png。

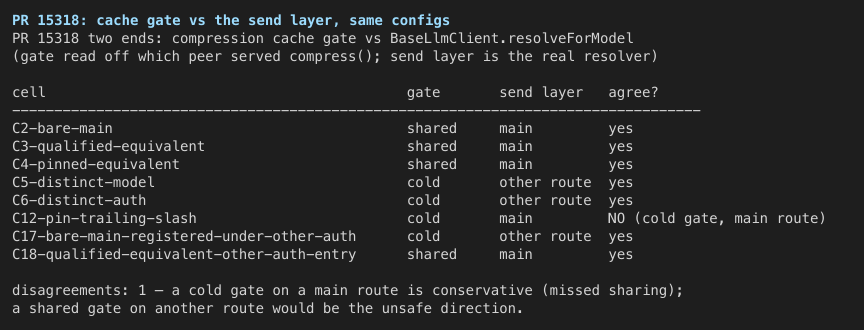
两端一致性:另用真实 BaseLlmClient.resolveForModel() 对同一批配置求路由,证明"门控放行 ⇒ 发送层确实走主生成器"(无违规),并据此澄清一处描述:当主模型没注册在会话 authType 下时,裸主模型选择器会从共享变为冷路径——这是 head 与发送层对齐的结果(base 的共享才是潜在错配),但 PR 正文"默认/裸主模型前后都不变"这句话在该配置下不成立。见 02-two-ends-gate-vs-send-layer.png。

findings:无阻塞项。一条描述修正(上述 C17),一条既有且方向安全的保守失败(端点 pin 不匹配时门控判冷、发送层落到主生成器)。

未覆盖范围:真实提供商缓存命中/延迟/费用;合并树上的复跑(只做了树级比对:合并无冲突,且被改文件在合并树里就是 head 与 main 两侧改动的组合);上一轮"死子句"观察未重测。

Previous round status

Round 1 ran at b2c8b648b55ec0a113e37adee8f71b97bc541f48 (base 06c1f989) and reported merge-ready with two suggestions.

# previous finding severity status at 4c698c47
S1 the gate's predicate is a hand-maintained copy of the send layer's condition; extract it beside splitModelBaseUrl Suggestion stands — onMainRoute is still local to chatCompressionService.ts and baseLlmClient.ts is untouched (blob identical to round 1). Re-tested this round: the two copies agree on every probed cell, so this stays maintenance-only.
S2 the skip diagnostic says distinct compaction model even when the mismatch is the endpoint Suggestion stands — the string is unchanged; the mutation row below shows no test pins that wording either way.
— no blocking findings — re-measured, still none

The gap round 1 left open — its round predated the zh-CN design counterpart — is closed: docs/design/chat-compression-cache-sharing.zh-CN.md is present and the English doc links to it.

Central claim and A/B

The PR's claim: a compaction selector that routes to the main model — provider-qualified (openai:test-model) or endpoint-pinned at the main base URL — should regain compression cache sharing, while a genuinely different model, auth type or endpoint stays cold.

Both arms run the real ChatCompressionService.compress(); the peers are BaseLlmClient.generateText (shared path) and runSideQuery (cold path), so the route is read off which peer served the call, not off a flag. The harness is byte-identical in both arms (__ab_matrix.test.ts, copied into each worktree, run with AB_OUT=… npx vitest run --coverage.enabled=false).

Witness: 01-ab-route-matrix.png.

cell base 2be58e52 head 4c698c47 head slimming calls delta
C1-unset shared (1/0) shared (1/0) 0 unchanged
C2-bare-main shared (1/0) shared (1/0) 0 unchanged
C3-qualified-equivalent cold (0/1) shared (1/0) 0 flip
C4-pinned-equivalent cold (0/1) shared (1/0) 0 flip
C5-distinct-model cold (0/1) cold (0/1) 1 unchanged
C6-distinct-auth cold (0/1) cold (0/1) 1 unchanged
C7-pinned-other-endpoint cold (0/1) cold (0/1) 1 unchanged
C8-qualified-other-model cold (0/1) cold (0/1) 1 unchanged
C9-window-downgrade-distinct shared (1/0) shared (1/0) 1 unchanged
C10-window-small-on-equivalent shared (1/0) shared (1/0) 0 unchanged
C11-colon-main-id-qualified cold (0/1) shared (1/0) 0 flip
C12-pin-trailing-slash cold (0/1) cold (0/1) 1 unchanged
C13-shared-rejected-fallback cold (0/1) shared→cold (1/1) 1 flip
C14-payload-overflow-cold cold (0/1) cold (0/1) 1 unchanged
C15-estimated-anchor-cold cold (0/1) cold (0/1) 1 unchanged
C16-no-provider-count-cold cold (0/1) cold (0/1) 1 unchanged
C17-bare-main-registered-under-other-auth shared (1/0) cold (0/1) 1 flip
C18-qualified-equivalent-other-auth-entry cold (0/1) shared (1/0) 0 flip

The 4 target flips are C3-qualified-equivalent, C4-pinned-equivalent, C11-colon-main-id-qualified, C18-qualified-equivalent-other-auth-entry (the last of those has a main model id containing a colon). C13 is the widened gate's sharpest consequence: a rejected shared request now costs one wasted request before the existing cold fallback, which the run confirms happens exactly once and reports cache_sharing_used=false. The remaining flip, C17, is the description correction below.

Every shared cell in both arms posted the unslimmed history (sizeDelta>0 against the stored history) with promptCacheSharing:true, so the change moves the request, not just a diagnostic.

C9/C10 are the window-guard interaction: C9 (genuinely distinct model, tiny window) still warns and downgrades to the main model, while C10 (equivalent selector, same tiny registry window) now skips the guard entirely and no longer pays for the slimming estimate (base: 1 call, head: 0) — that is what the hoist is for.

Corrections

To the PR description, not to the code. The evidence table says "Default or bare main model: 1 / 0 before and after". That holds when the main model is registered under the session's auth type (C1, C2), but not universally: in C17 the session's main model is registered only under a different auth type, and the bare-main selector goes shared → cold. That is the correct outcome, and it is not a regression this PR introduces: the same config makes the real BaseLlmClient.resolveForModel() build a per-model generator instead of returning the main one, so round 1's gate was sharing the cache on a request that had already left the main route. The description should say "a selector the send layer actually routes to the main generator", which is what the code now does, rather than enumerating "default / bare main model" as unconditionally unchanged. Reachability of that registry shape from a real settings file is not established here; the direction is safe either way, because the gate can only become more conservative.

The two-ends table below is the measurement behind that statement. A cold gate on a main route (C12, unmatched endpoint pin) is the conservative direction and is pre-existing — it is listed for completeness, not as a defect.

PR 15318 two ends: compression cache gate vs BaseLlmClient.resolveForModel
(gate read off which peer served compress(); send layer is the real resolver)

cell                                           gate       send layer   agree?
----------------------------------------------------------------------------------
C2-bare-main                                   shared     main         yes
C3-qualified-equivalent                        shared     main         yes
C4-pinned-equivalent                           shared     main         yes
C5-distinct-model                              cold       other route  yes
C6-distinct-auth                               cold       other route  yes
C12-pin-trailing-slash                         cold       main         NO (cold gate, main route)
C17-bare-main-registered-under-other-auth      cold       other route  yes
C18-qualified-equivalent-other-auth-entry      shared     main         yes

disagreements: 1 — a cold gate on a main route is conservative (missed sharing);
a shared gate on another route would be the unsafe direction.

Witness: 02-two-ends-gate-vs-send-layer.png.

Findings

No blocking findings.

F1 (Suggestion — description accuracy). Narrow the "default or bare main model is unchanged" line to "a selector that the send layer routes to the main generator". Evidence: C17 in the A/B table plus the two-ends row for the same config. Not a code change request: the code's verdict matches the send layer, and reachability of the registry shape is unproven.

F2 (informational, pre-existing). An endpoint pin that the registry cannot match (C12, trailing slash) stays cold even though resolveForModel falls back to the main generator for it. That is a missed sharing opportunity, not a wrong route, and it behaves identically on both arms.

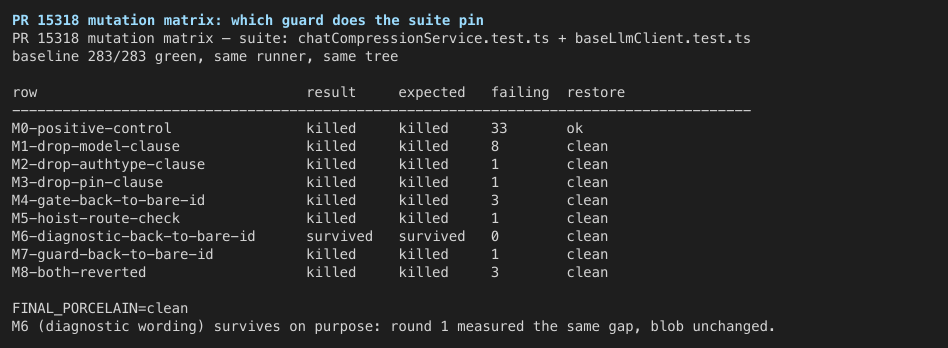
Mutation matrix

Independent runs of the two suites that pin this behaviour (chatCompressionService.test.ts + baseLlmClient.test.ts), each mutation applied with a single-match anchor, run, then restored with git checkout HEAD -- and verified clean before the next one. Baseline through the same runner first: 283/283 green, so the kills below are not a pre-red suite. Positive control: a mutation that forces onMainRoute to false (a behaviour several tests pin) is killed by 33 tests, so the runner can make this suite fail.

row mutant result expected failing tests witnesses
M0-positive-control onMainRoute always false — a behaviour many tests pin killed killed 33 ChatCompressionService skips the guard when no explicit compaction model is configured
ChatCompressionService.compress cache sharing shares the compression cache only on the main route: undefined
M1-drop-model-clause onMainRoute model comparison removed killed killed 8 ChatCompressionService falls back to the main model when the compaction model context window is too small
ChatCompressionService.compress cache sharing shares the compression cache only on the main route: 'compact-model'
M2-drop-authtype-clause onMainRoute authType comparison removed killed killed 1 ChatCompressionService.compress cache sharing shares the compression cache only on the main route: 'anthropic:test-model'
M3-drop-pin-clause onMainRoute endpoint-pin comparison removed killed killed 1 ChatCompressionService.compress cache sharing shares the compression cache only on the main route: 'openai:test-model^@https://other.…'
M4-gate-back-to-bare-id cache gate reverted to the pre-PR bare-id comparison killed killed 3 ChatCompressionService.compress cache sharing shares the compression cache only on the main route: 'openai:test-model'
ChatCompressionService.compress cache sharing shares the compression cache only on the main route: 'openai:test-model^@https://same.i…'
M5-hoist-route-check sideQueryOnMainRoute computed before the window guard killed killed 1 ChatCompressionService.compress cache sharing shares the cache after the window guard downgrades a distinct compaction model
M6-diagnostic-back-to-bare-id skip reason decided by the bare-id comparison survived survived 0 —
M7-guard-back-to-bare-id window guard condition reverted to the pre-PR bare-id comparison killed killed 1 ChatCompressionService.compress cache sharing does not slim the history for an equivalent selector on the shared path
M8-both-reverted combination: M4 + M7 together (the whole behavioural revert) killed killed 3 ChatCompressionService.compress cache sharing shares the compression cache only on the main route: 'openai:test-model'
ChatCompressionService.compress cache sharing shares the compression cache only on the main route: 'openai:test-model^@https://same.i…'

Final tree state after the matrix: FINAL_PORCELAIN=clean. Witness: 03-mutation-matrix.png.

Every row's expectation was fixed before the run from the PR's own claims; M6 is the one row expected to survive, because round 1 measured the same wording unprotected and the blob is unchanged. A survivor there is a coverage gap for a diagnostic string, not a behavioural hole.

Not covered

  • Real-provider cache-hit rate, latency and cost. The PR does not claim them either; the harness oracle is the route taken, not a provider's cache accounting.
  • Re-running the matrix on the trial-merge tree. git merge-tree --write-tree 4c698c47 origin/main is conflict-free (tree b1f92469a05e), but main moved this PR's file after the base: packages/core/src/services/chatCompressionService.ts gains movePromptContextAheadOfUserText(sideQueryHistory) on the shared payload, and its test gains the matching case. The merged tree therefore contains both changes; the route decision measured here is upstream of that payload construction, but I did not re-run the matrix on the merged tree.
  • The previous round's "dead clause" observations (the sideQueryOnMainRoute term in the reactive-ceiling ternary and its diagnostic sibling) were not re-measured this round; they are not part of the central claim.
  • Reachability of the C17 registry shape from a real settings file — measured only as a config shape handed to the gate and the resolver.
  • Windows/macOS-specific behaviour, hosted/managed-agent paths, and the CLI suites (the PR's CI covers Test (ubuntu), all eight Linux unit shards, Lint & Static and Integration green on this head).

Methodology

macOS arm64 host, Node 22.23.4, vitest 3.2.7. Two detached worktrees at 2be58e52 (base) and 4c698c47 (head), each with its own seeded node_modules; readlink -f node_modules/@qwen-code/qwen-code-core resolves inside each arm's own tree (not the enclosing checkout), so neither arm can load the other's source. packages/core was emitted into each arm with tsc --build --noCheck per arm. The A/B harness imports the service from source and stubs only the two peers, so the unit under test is the shipped code path. Raw logs, per-cell JSONL, vitest JSON reports per mutant and the harness scripts are in this artifact directory; logs/ab-ledger.json is the assertion source for the counts above.

Evidence

image what it shows
18-cell A/B route matrix, base vs head, same harness in both arms
the cache gate against the real send-layer resolver on the same configs
mutation matrix as it printed, including the positive control

@wenshao
wenshao enabled auto-merge (squash) November 8, 2026 00:05

@qqqys qqqys left a comment

Copy link
Copy Markdown
Collaborator

Choose a reason for hiding this comment

The reason will be displayed to describe this comment to others. Learn more.

APPROVE — reviewed at head 4c698c473a742931ca826e6d38f8d95a552c956e. No blocking correctness, security, data-loss, regression, or compatibility issue found.

Prior findings

No Critical was ever filed on this PR, so there is no historical blocker to re-verify. For the record, all four bot findings across four rounds were Suggestion-level: R1-1 and R1-2 were ruled fixed by the reviewer that filed them, R2-2 likewise, and R2-1 (the onMainRoute predicate being a hand-maintained copy of the send layer's condition) was deferred to #16473 under the bot's own adjudication. The one human review (@doudouOUC, COMMENTED at b2c8b648) raised a documentation requirement rather than a code defect — the missing zh-CN counterpart and the reciprocal language links — and that is satisfied at this head: docs/design/chat-compression-cache-sharing.zh-CN.md is added, [English] | [简体中文] sits immediately below both titles, and the eligibility bullet reads the same way in both languages ("routes to the main model — the resolved model, auth type, and endpoint match the main generator"). @wenshao's APPROVE is current at this same head per latestOpinionatedReviews.

What I verified in the code at this head

The whole change is one widening — canShareCache and the compaction-window gate both move from the string comparison effectiveCompactionModel === config.getModel() to the route predicate onMainRoute(...) — so the load-bearing question is whether that predicate agrees with the send layer it claims to mirror. It does, and on two of its three terms it is not a copy at all:

  • The resolution half is the identical call. onMainRoute does resolveModelId(model, buildModelIdContext(config)) (chatCompressionService.ts:774); resolveForModel does this.resolveModelSelector(requested.model), and resolveModelSelector is a one-line private wrapper whose entire body is resolveModelId(model, buildModelIdContext(this.config)) (baseLlmClient.ts:1071-1073). Same function, same context constructor — these cannot drift.
  • The comparison targets are the same object. The service's contentGeneratorConfig is config.getContentGeneratorConfig() (chatCompressionService.ts:535), which is exactly what resolveForModel reads as mainGeneratorConfig for mainAuthType and mainBaseUrl (baseLlmClient.ts:854-856, compared at :862-864). So the authType and endpoint-pin terms compare against the same values the send layer compares against.
  • The pin split agrees for the format that is actually produced. splitModelBaseUrl cuts at the first \0 and returns the remainder as baseUrl (baseLlmClient.ts:61-70); the service's selector.split('\0') yields the same pair for the single-pin authType:id\0<declaredBaseUrl> shape getCompactionModel() carries (#12760), which is also the idiom the pre-existing guard body already used at :795.

The post-guard re-read is load-bearing, not decorative. effectiveCompactionModel is a let (:745) and the guard reassigns it to config.getModel() when the compaction window is too small (:820), so sideQueryOnMainRoute = onMainRoute(effectiveCompactionModel) at :829 genuinely observes the downgrade — that is what makes a window-forced fallback share the cache and take the main route's budgetWindow/reactiveContextCeiling instead of a compactionModelWindow that was never set. usesMainModel has no remaining reader anywhere in the file, so deleting it leaves no stale gate.

Skipping the window guard on an equivalent selector is the correct consequence, not a lost check. When onMainRoute is true the side query is sent to the main content generator, so the main model's window is the governing one and it is what budgetWindow resolves to via reactiveContextCeiling (:860-862); measuring a registry window for a request that never leaves the main route would only risk a spurious downgrade. The guard's own body is unchanged, and its if (resolved) gate means an unresolvable selector still measures nothing and downgrades nothing.

The divergence I looked for and found is in the conservative direction, and pre-dates this PR. For a selector that resolveModelId cannot resolve, resolveForModel falls back to the main generator (its requestModel defaults to config.getModel()), while onMainRoute returns false because it compares the raw string. That yields no cache sharing and a guard that resolves nothing — the safe side — and it is byte-for-byte the behaviour of the old inline predicate, which computed the same three terms, so this PR neither introduces nor widens it. It is the R2-1 family already deferred to #16473.

The tests pin the equivalence at the layer that owns it. baseLlmClient.test.ts adds two cases that drive the real resolveForModel and assert resolved.contentGenerator is the main generator (toBe, not a shape match) for openai:main-model and for openai:main-model\0<mainBaseUrl>, with mockCreateContentGenerator asserted uncalled — so the widening rests on the send layer's own answer rather than on a re-stated copy of its condition. chatCompressionService.test.ts adds the shared-path case plus the two controls that matter: still slims for a genuinely distinct compaction model (the guard still fires when the route really differs) and shares the cache after the window guard downgrades a distinct compaction model (the post-guard re-read).

CI

62 checks pass or are intentionally skipped at this head, including Lint & Static and Test (ubuntu-latest, Node 22.x). The only two non-pass entries are a pending Select the Managed Agent tier and route in the review workflow, started by the approval that landed moments ago; neither gates this change and I did not wait on them.

@qwen-code-review-bot

Copy link
Copy Markdown
Collaborator

Released in v0.27.1.

Sign up for free to join this conversation on GitHub. Already have an account? Sign in to comment

Labels

review/self-reported The linked issue was opened by the PR author (self-reported)

Projects

None yet

Development

Successfully merging this pull request may close these issues.

bug(core): qualified same-route compaction selectors skip cache sharing

6 participants